Cognition's SWE-2 favicon

Cognition's SWE-2

SWE-2 is Cognition's flagship coding model post-trained from Kimi K3, designed for agentic software engineering with focused codebase navigation and disciplined verification across multiple effort levels.

Code & ITNavigates repositories using read,…Runs compilation, linting, and…Constructs git commits and communicates…Identifies alternative data sources and…
Cognition's SWE-2 product interface screenshot
Estimated monthly visits
427K
Data period:
Listed on AIToolly

What Is Cognition's SWE-2? Product Overview

What the product does and how it is positioned

SWE-2 is a specialized coding model developed by Cognition, post-trained from the 2.8-trillion-parameter Kimi K3 base model using reinforcement learning tailored to agentic software engineering.

Integrated directly across Devin environments, SWE-2 executes end-to-end development workflows including repository search, multi-file code editing, build verification, and test authoring.

What Can You Use Cognition's SWE-2 For?

Source-supported ways to use the product

Repository Maintenance and Bug Fixing

Developers can assign codebase issues to SWE-2 to inspect relevant files, plan changes, apply code updates, and commit verified fixes.

Automated Test Generation and Regression Checking

Engineering teams can use the model to write end-to-end tests that independently validate software modifications against edge cases.

Post-Training Architecture and Reinforcement Learning

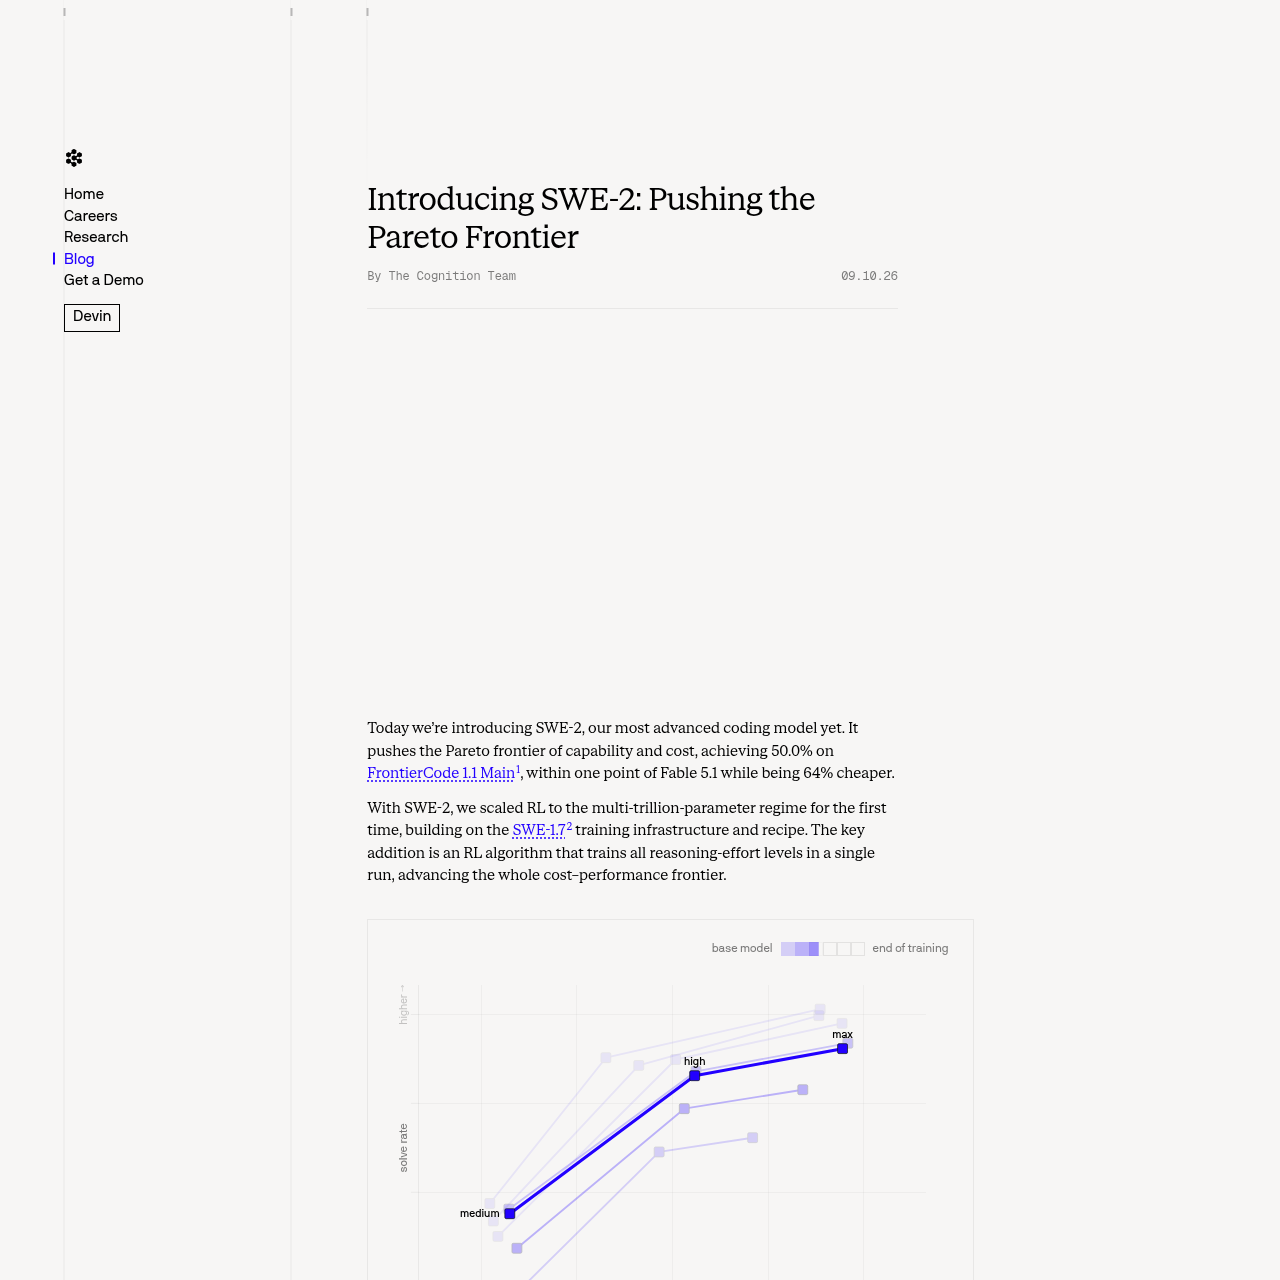
SWE-2 is post-trained from Kimi K3, scaling reinforcement learning to a multi-trillion-parameter model to optimize performance across reasoning-effort tiers in a single training run.

The training architecture uses a length-weighted reward baseline to stabilize gradient variance without requiring extra backward passes. Serving rollouts rely on NVFP4 and FP8 kernels alongside speculative decoding supported by an online-updated draft model.

  • Incorporates linear penalties matched to the local slope of the base model's frontier curve across effort levels.
  • Applies length-weighted group baselines to reduce policy divergence between training and inference.
  • Uses low-precision NVFP4 and FP8 kernels with quantization-aware training to manage memory overhead during rollouts.

What to Test Before Choosing Cognition's SWE-2

Checks to run with your own material and workflow

  • Verify that SWE-2 is accessible in the intended interface, such as Devin Desktop, Devin CLI, Devin Web, or Devin Fusion.
  • Check whether medium, high, or max reasoning effort settings align best with the complexity and exploration requirements of the target repository.
  • Review project requirements that rely heavily on advanced terminal commands against documented performance on terminal-based benchmarks.

Cognition's SWE-2 Sources and Last Checked

What was checked and when

Last checked
Category
Code & IT

Cognition's SWE-2 Frequently Asked Questions

Answers based on the source-checked product record

What foundation model is SWE-2 built upon?

SWE-2 is post-trained from Kimi K3, a 2.8-trillion-parameter model with prior reinforcement learning for agentic coding.

Which deployment environments support SWE-2?

SWE-2 is available within Devin Desktop and Devin CLI, with rollouts extending to Devin Web and Devin Fusion.

How does SWE-2 approach repository exploration compared to earlier models?

SWE-2 focuses its exploration on relevant files, enabling it to initiate code editing in fewer exploratory steps than SWE-1.7.

What reasoning effort levels can be selected in SWE-2?

The model supports medium, high, and max effort levels, providing options between rapid code edits and deeper planning or verification.

How does SWE-2 handle verification when challenged?

SWE-2 re-derives conclusions by executing test artifacts and inspecting technical evidence rather than accepting user hypotheses without verification.

Explore other recently added tools in the same category.