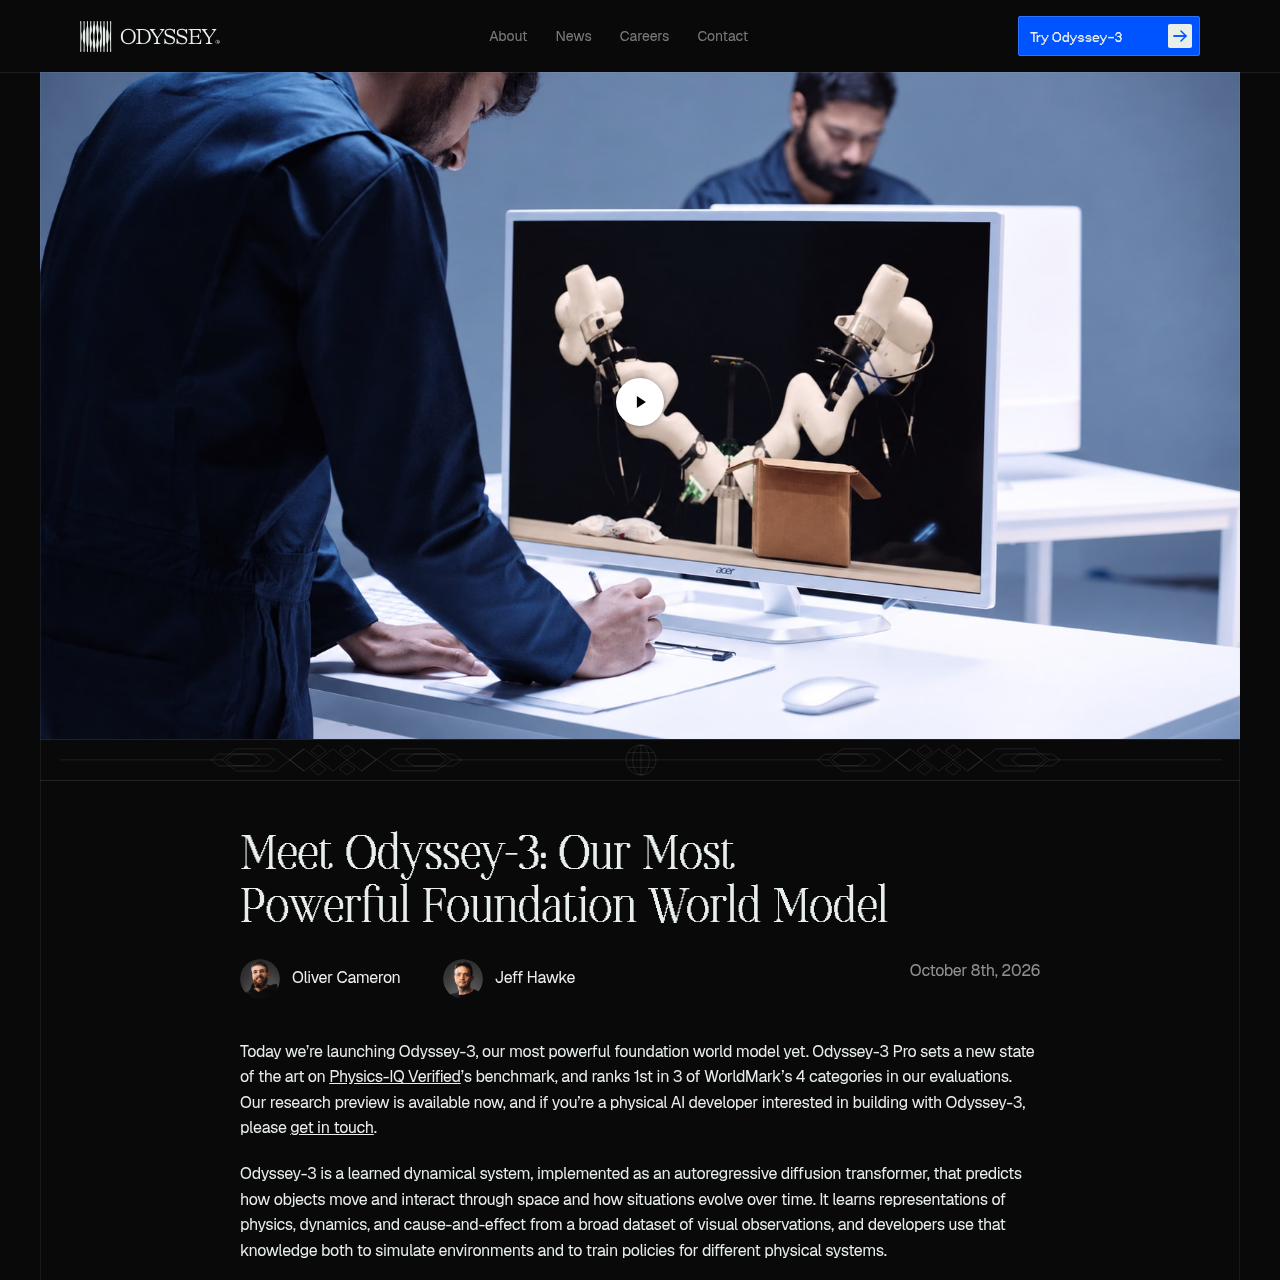
Odyssey 3 is an autoregressive diffusion transformer world model designed to simulate real-time physical dynamics and power autonomous systems.
Image GeneratorPredicting object movement,…Generating multi-sensor camera…Providing simulated environmentsServing as a visual representation…
Estimated monthly visits
19K
Data period:
Listed on AIToolly
What Is Odyssey 3? Product Overview
What the product does and how it is positioned
Odyssey 3 is a foundation world model implemented as an autoregressive diffusion transformer that simulates how objects, dynamics, and physical interactions evolve across time and space.
Trained on video observations, gameplay inputs, and simulated rigid-body physics, the model provides an interactive environment generator and visual representation foundation for robotics and physical AI policies.
What Can You Use Odyssey 3 For?
Source-supported ways to use the product
Humanoid Robot Control
The company presents this as a customer use case where Flexion built humanoid control policies on Odyssey 3 that maintained task execution under environmental and lighting changes.
Autonomous Vehicle Policy Training
Developers adapted Odyssey 3 to predict waypoints for closed-loop driving demonstrations using a frozen model backbone.
Robotic Arm Manipulation
Developers trained manipulation policies on robot demonstration data to execute tasks and exhibit recovery behaviors such as regrasping.
Model Architecture and Real-Time Distillation
Odyssey 3 operates as a multi-step video diffusion transformer that incorporates temporally resolved prompts and action inputs to generate future visual states.
Through causal masking and teacher forcing, the system functions autoregressively by conditioning future predictions on prior visual history, while an adversarial and distribution-matching distillation pipeline reduces step count to enable real-time response.
Trained on annotated internet video, gameplay with input logging, and simulated rigid-body interactions
Outputs video at 832x480 resolution in Odyssey-3 and 1280x720 in Odyssey-3 Pro
Enables interaction via first-person, third-person, and decoupled camera viewpoints
What to Test Before Choosing Odyssey 3
Checks to run with your own material and workflow
Confirm whether 832x480 or 1280x720 output resolutions meet the visual fidelity requirements of your downstream evaluation pipeline.
Verify the volume of paired observation and action data required to train a hardware-specific decoder for your target machine.
Check model predictions against specific domain requirements such as fluid dynamics, optics, solid mechanics, or thermodynamics.