ElevenLabs Realtime
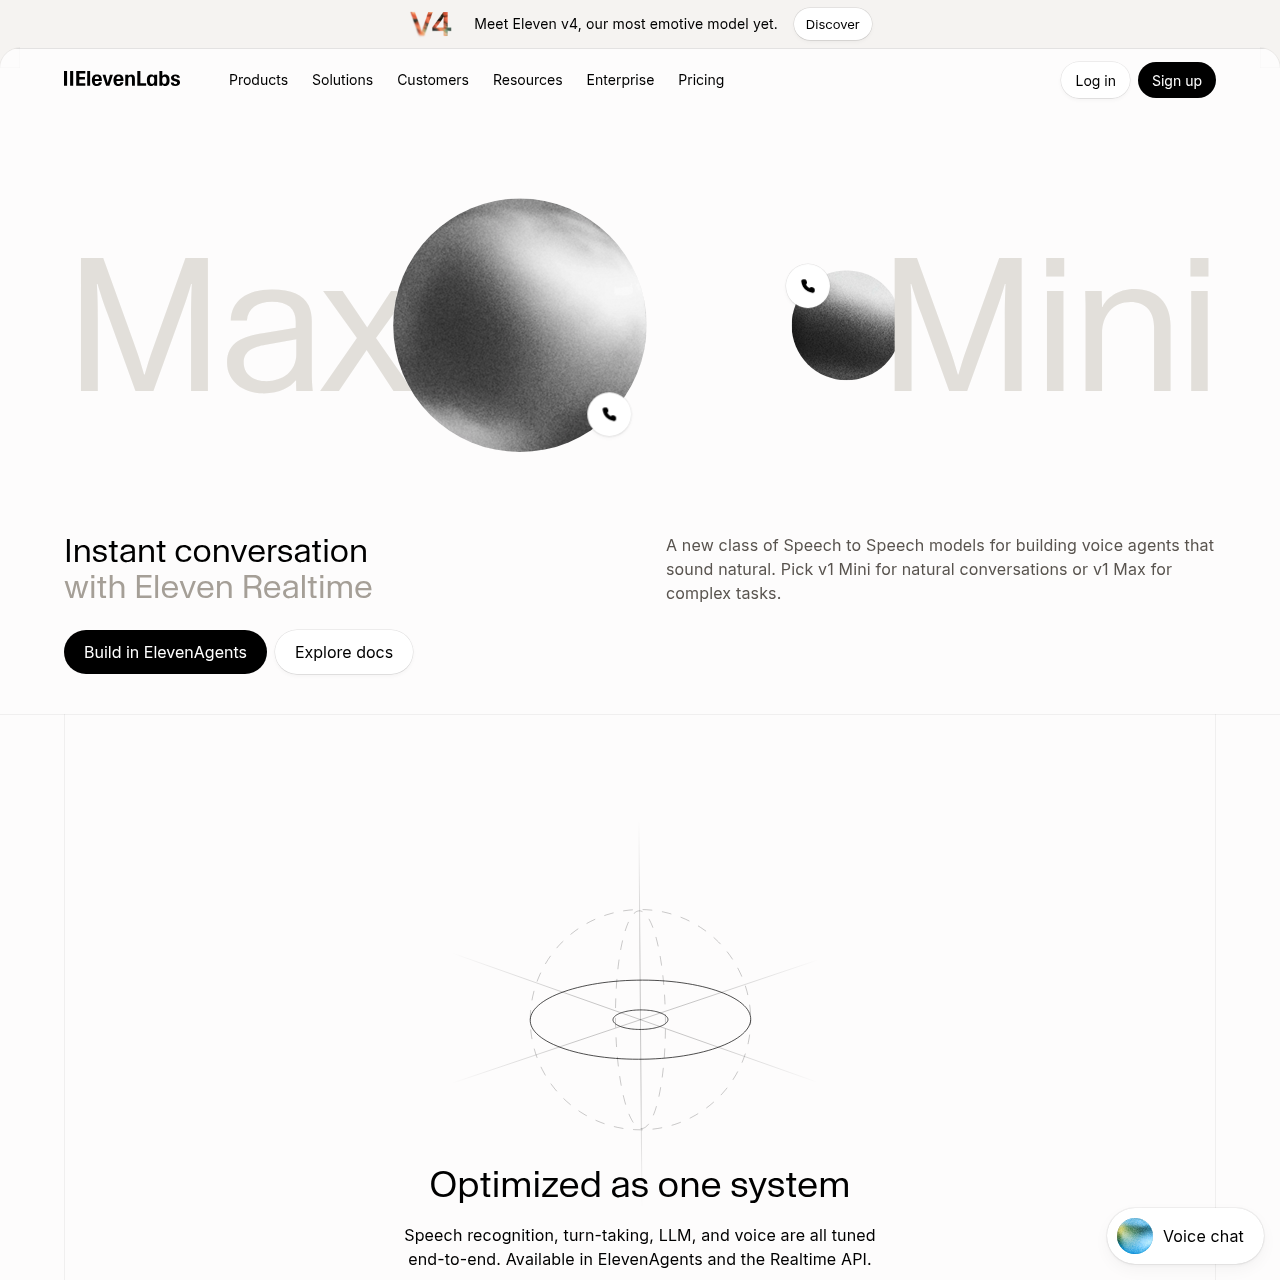
ElevenLabs Realtime delivers end-to-end speech-to-speech models, v1 Mini and v1 Max, combining speech recognition, turn-taking, and voice synthesis for conversational agents with an OpenAI-compatible WebSocket API.
What the product does and how it is positioned
ElevenLabs Realtime is a suite of speech-to-speech models designed for interactive conversational voice agents. The architecture unifies speech recognition, turn-taking logic, language model processing, and vocal synthesis into an end-to-end system designed to preserve conversational pacing across interruptions.
The system is available in two model configurations: v1 Mini, targeted at expressive, fluid interactions, and v1 Max, targeted at structured reasoning and automated tool execution. Users can implement these models through the no-code ElevenAgents environment or via a WebSocket API compatible with OpenAI Realtime handlers.
Source-supported ways to use the product
v1 Mini supports interactive characters, voice assistants, and language or subject tutors requiring natural dialogue timing and vocal expression.
v1 Max handles complex inquiries, automated scheduling, and qualification dialogues while maintaining conversational flow and invoking external tools.
The documented workflow, where available
Initialize a new agent within the ElevenAgents interface or configure a session connection using the Realtime API.
Choose between the v1 Mini model for conversational flow or the v1 Max model for reasoning and tool invocation.
Select from over 17,500 voices and configure language settings across the supported roster of 90+ languages and accents.
Engage in live voice conversations over WebSocket channels and monitor auditable interaction logs within the management dashboard.
ElevenLabs Realtime integrates speech recognition, turn management, language comprehension, and voice generation into a single end-to-end pipeline. This setup avoids chaining separate external services for transcription, inference, and text-to-speech, allowing agents to respond to rapid conversational interjections naturally.
Developers can access the system through ElevenAgents or programmatically over WebSocket connections using the Realtime API. Because the API matches OpenAI's Realtime protocol and client events, existing client handlers, logging tools, and SDK setups can be transitioned by modifying the destination endpoint and model string.
Checks to run with your own material and workflow
What was checked and when
Answers based on the source-checked product record
Eleven Realtime is an end-to-end speech-to-speech model family that combines speech recognition, turn-taking, language modeling, and voice synthesis into a single conversational system.
v1 Mini is optimized for expressive dialogue and natural conversation pacing, while v1 Max is built for complex tasks, reasoning, and calling tools during business interactions.
Eleven Realtime provides an OpenAI-compatible API that shares the same client and server events, allowing developers to switch the endpoint and model name while keeping their existing handlers and tooling.
The platform provides access to more than 17,500 voices spanning multiple styles and supports real-time voice conversations across more than 90 languages and regional accents.
The platform encrypts data in transit and at rest, supports SOC 2 Type II, ISO 27001, ISO 42001, HIPAA, PCI DSS Level 1, and GDPR compliance, and offers EU Data Residency and Zero Retention options.