
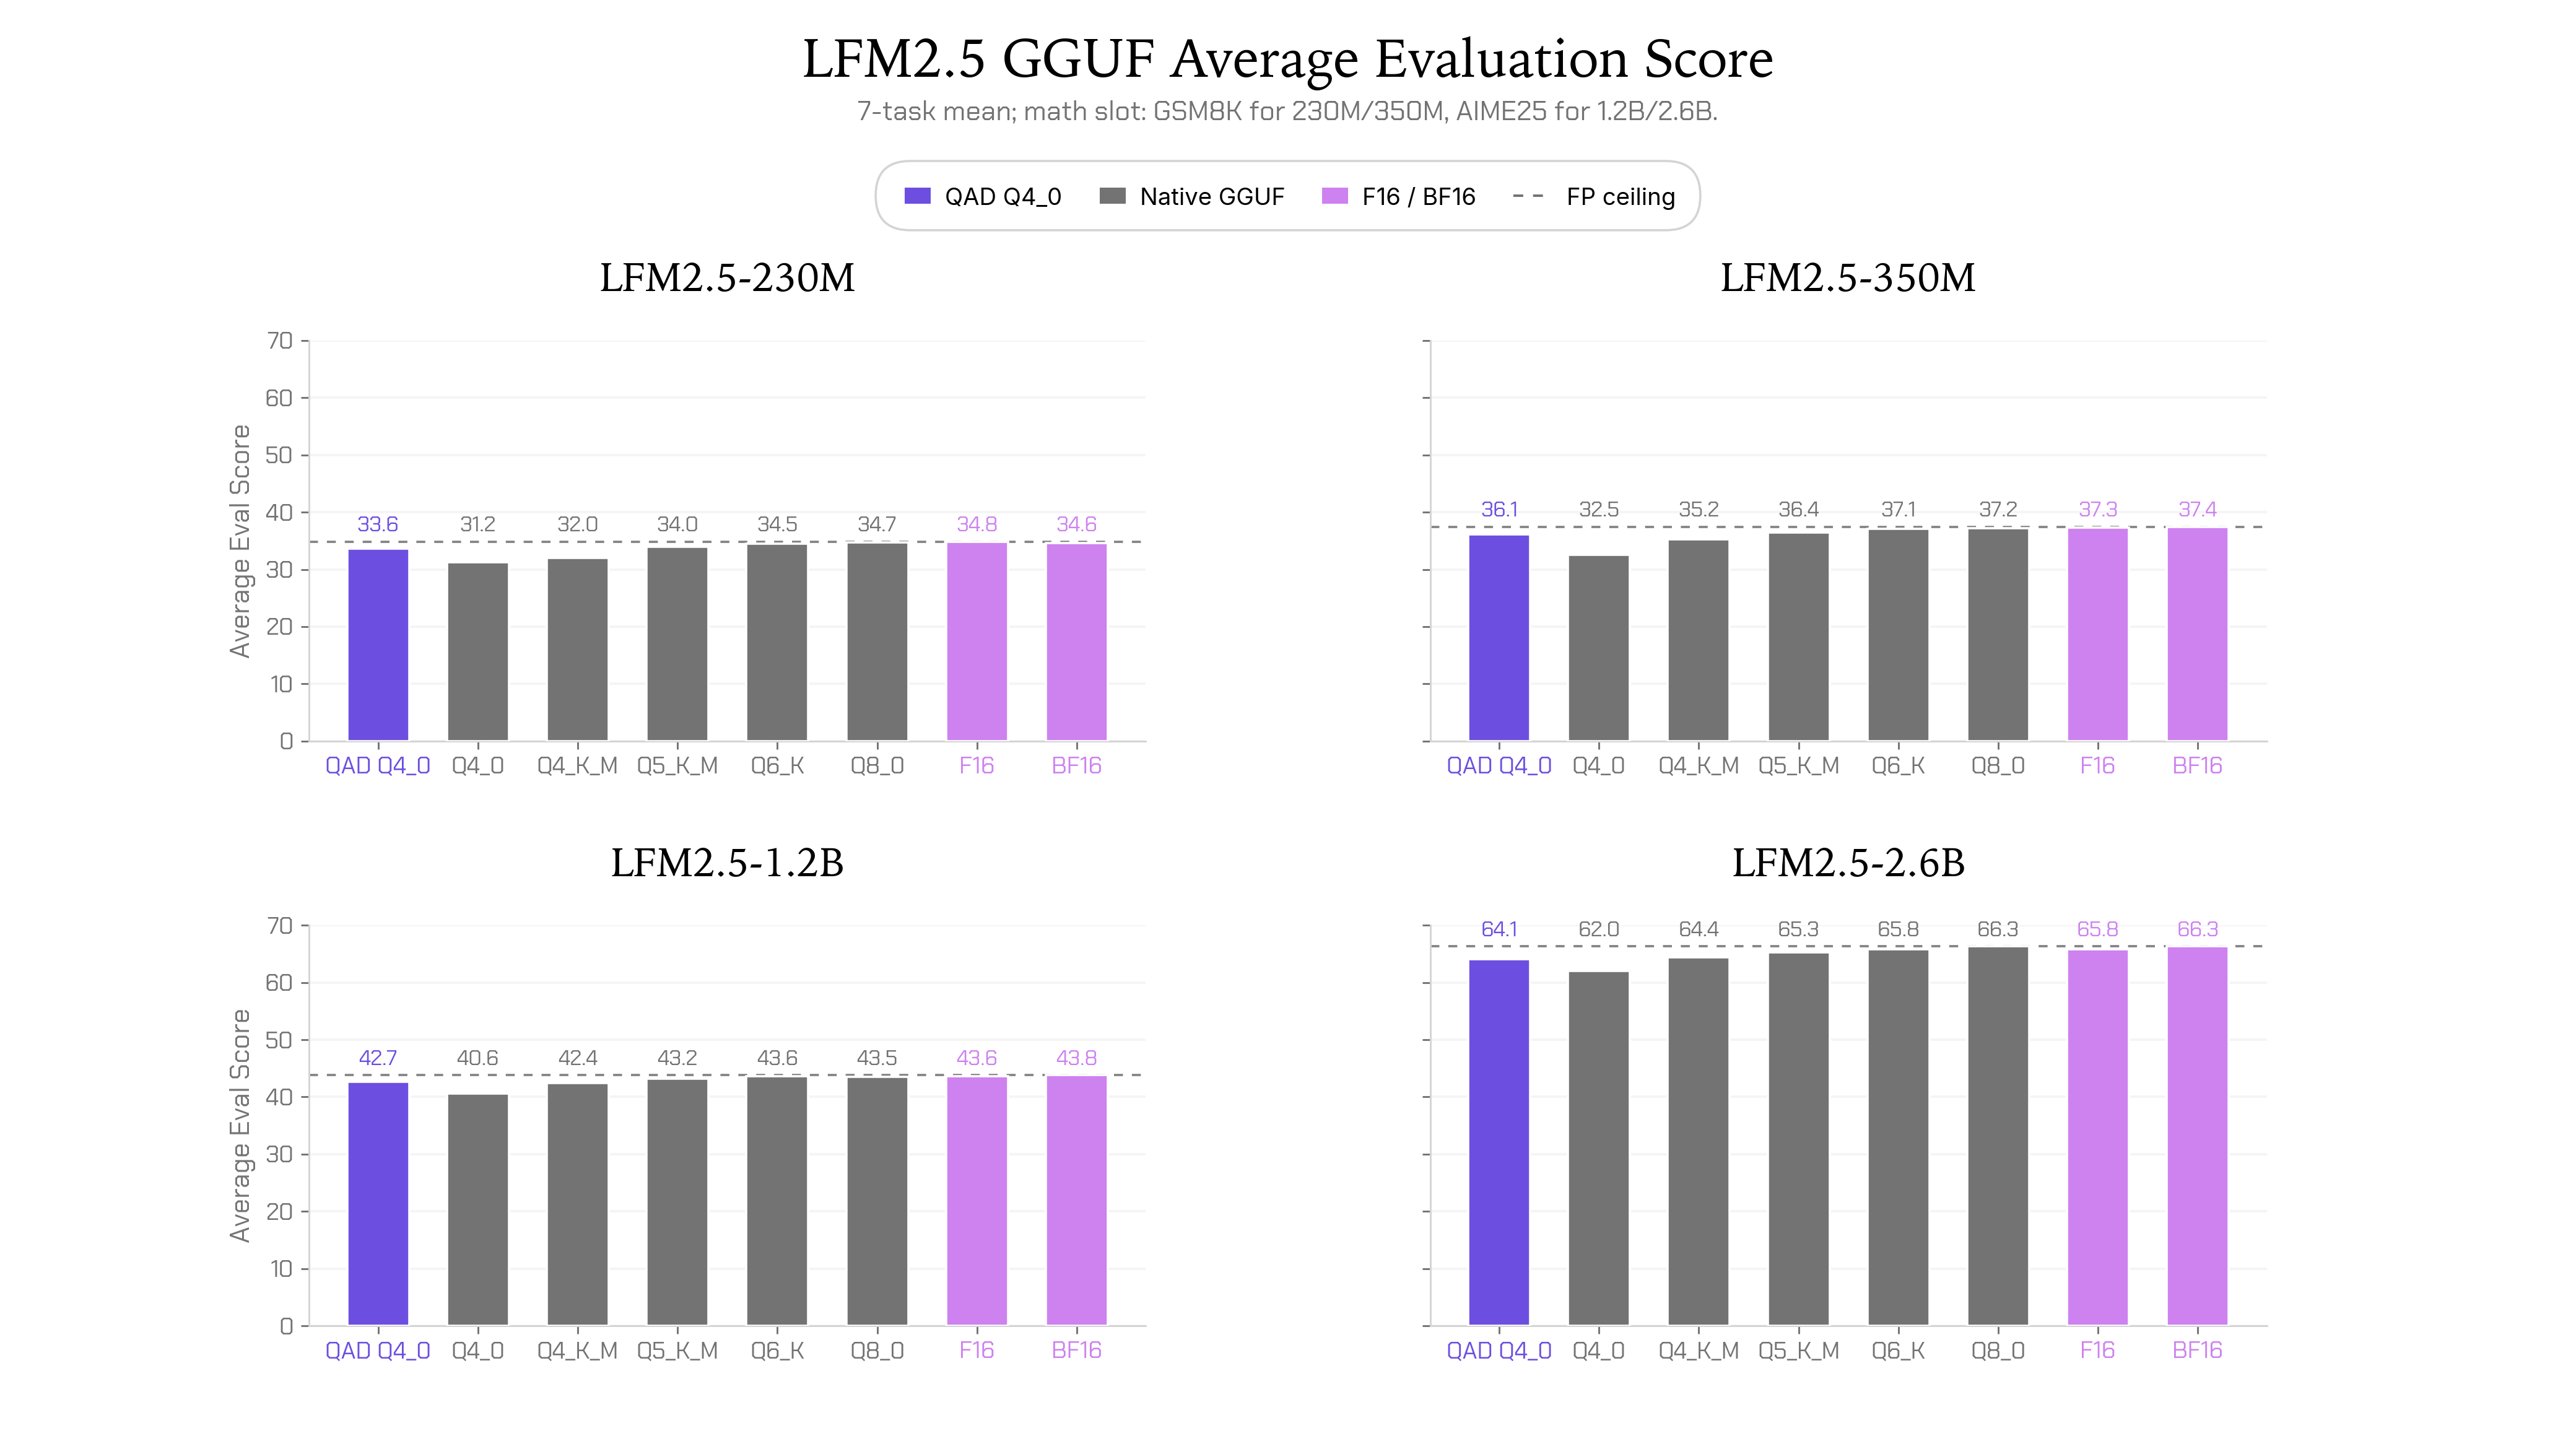
Liquid AI Releases LFM2.5 Q4_0 Checkpoints via Quantization-Aware Distillation
Liquid AI has announced the release of LFM2.5 Q4_0 checkpoints, a development achieved through the application of Quantization-Aware Distillation (QAD). This release, hosted on the Hugging Face platform, introduces optimized 4-bit quantized versions of the LFM2.5 model. By utilizing QAD, the developers aim to maintain the model's performance integrity while significantly reducing its memory footprint and computational requirements. The availability of these checkpoints marks a technical progression in the LFM2.5 ecosystem, focusing on the intersection of model compression and knowledge distillation to facilitate more efficient AI deployment.
Key Takeaways
- Release of LFM2.5 Q4_0: Liquid AI has officially made the Q4_0 checkpoints for the LFM2.5 model available to the public.
- Quantization-Aware Distillation (QAD): The checkpoints were developed using QAD, a specialized technique that combines quantization and knowledge distillation.
- Optimization Focus: The primary goal of this release is to provide a high-performance model in a 4-bit quantized format (Q4_0).
- Hugging Face Integration: The checkpoints are hosted on the Hugging Face platform, ensuring accessibility for the broader AI research and development community.
In-Depth Analysis
The Emergence of LFM2.5 Q4_0 Checkpoints
The release of the LFM2.5 Q4_0 checkpoints represents a targeted effort by Liquid AI to address the growing demand for efficient large-scale models. According to the announcement, these checkpoints are the direct result of a process known as Quantization-Aware Distillation. While standard quantization often involves post-training adjustments that can lead to a loss in precision, the LFM2.5 Q4_0 checkpoints are designed to mitigate these issues by integrating the quantization constraints directly into the distillation process. This ensures that the 4-bit representation (Q4_0) retains as much of the original model's intelligence as possible.
Understanding Quantization-Aware Distillation (QAD)
The core methodology behind this release is Quantization-Aware Distillation. In this framework, a larger or more precise "teacher" model guides the training of a smaller or quantized "student" model—in this case, the LFM2.5 Q4_0. By being "quantization-aware," the distillation process accounts for the limitations of 4-bit precision during the learning phase. This approach allows the LFM2.5 checkpoints to achieve a balance between the reduced resource requirements of the Q4_0 format and the high-level performance characteristics expected from the LFM2.5 architecture. The focus remains on maintaining accuracy even as the bit-depth is lowered to optimize for hardware efficiency.
Industry Impact
The introduction of LFM2.5 Q4_0 checkpoints via QAD has significant implications for the AI industry, particularly in the realm of edge computing and local deployment. By providing high-quality 4-bit checkpoints, Liquid AI lowers the barrier to entry for developers who may not have access to high-end enterprise GPUs. This move supports the broader industry trend toward model democratization, where the focus shifts from purely increasing model size to enhancing the efficiency and deployability of existing architectures. Furthermore, the use of QAD sets a technical precedent for how distillation can be used to recover performance lost during aggressive quantization, potentially influencing future model release strategies across the sector.
Frequently Asked Questions
Question: What is the significance of the Q4_0 format for LFM2.5?
The Q4_0 format refers to a 4-bit quantization method. For LFM2.5, this means the model's weights are compressed to 4 bits, which significantly reduces the amount of VRAM required to run the model and speeds up inference on compatible hardware, making it more suitable for consumer-grade devices.
Question: How does Quantization-Aware Distillation (QAD) improve these checkpoints?
QAD improves the checkpoints by training the quantized model to mimic a higher-precision teacher model. Unlike standard quantization, which happens after training, QAD allows the model to learn how to compensate for the reduced precision of the 4-bit format during the distillation process, resulting in higher accuracy than traditional post-training quantization.
Question: Where can these LFM2.5 Q4_0 checkpoints be accessed?
The checkpoints are available through the LiquidAI organization on the Hugging Face platform, allowing researchers and developers to integrate them into their existing workflows and experiment with the optimized LFM2.5 architecture.

