Google Research Identifies Recall as the Primary Bottleneck for Parametric Factuality in Generative AI
A recent publication from Google Research, titled "Empty shelves or lost keys? Recall is the bottleneck for parametric factuality," explores the underlying causes of factual inaccuracies in generative AI models. The research investigates whether models fail to provide correct information because they never learned it (empty shelves) or because they cannot retrieve it from their internal parameters (lost keys). The study concludes that the primary bottleneck for parametric factuality is recall—the model's ability to access information already stored within its weights. This finding suggests that improving AI factuality requires a focus on internal retrieval mechanisms rather than simply increasing the volume of training data or model size, marking a significant shift in how researchers approach the challenge of model reliability.
Key Takeaways
- Recall as the Primary Bottleneck: The research identifies that the inability to retrieve stored information (recall) is the main factor limiting parametric factuality in generative AI.
- The "Empty Shelves" vs. "Lost Keys" Framework: Google Research uses this metaphor to distinguish between a lack of stored knowledge (empty shelves) and a failure to access existing knowledge (lost keys).
- Parametric Factuality Focus: The study specifically addresses facts stored within the model's own parameters rather than external knowledge retrieval (RAG).
- Shift in AI Development: The findings suggest that enhancing the internal search and retrieval capabilities of neural networks is crucial for improving factual accuracy.
In-Depth Analysis
Understanding Parametric Factuality
Parametric factuality refers to the ability of a generative AI model to accurately state facts based solely on the information stored within its internal weights, or parameters, which are established during the training process. Unlike Retrieval-Augmented Generation (RAG), which pulls information from external databases, parametric factuality relies on the model's "memory." As generative AI becomes more integrated into daily tasks, the reliability of this internal knowledge base is critical. The Google Research blog post addresses a fundamental question: when a model provides an incorrect answer, is it because the information was never there, or because the model failed to find it?
The Metaphor: Empty Shelves or Lost Keys?
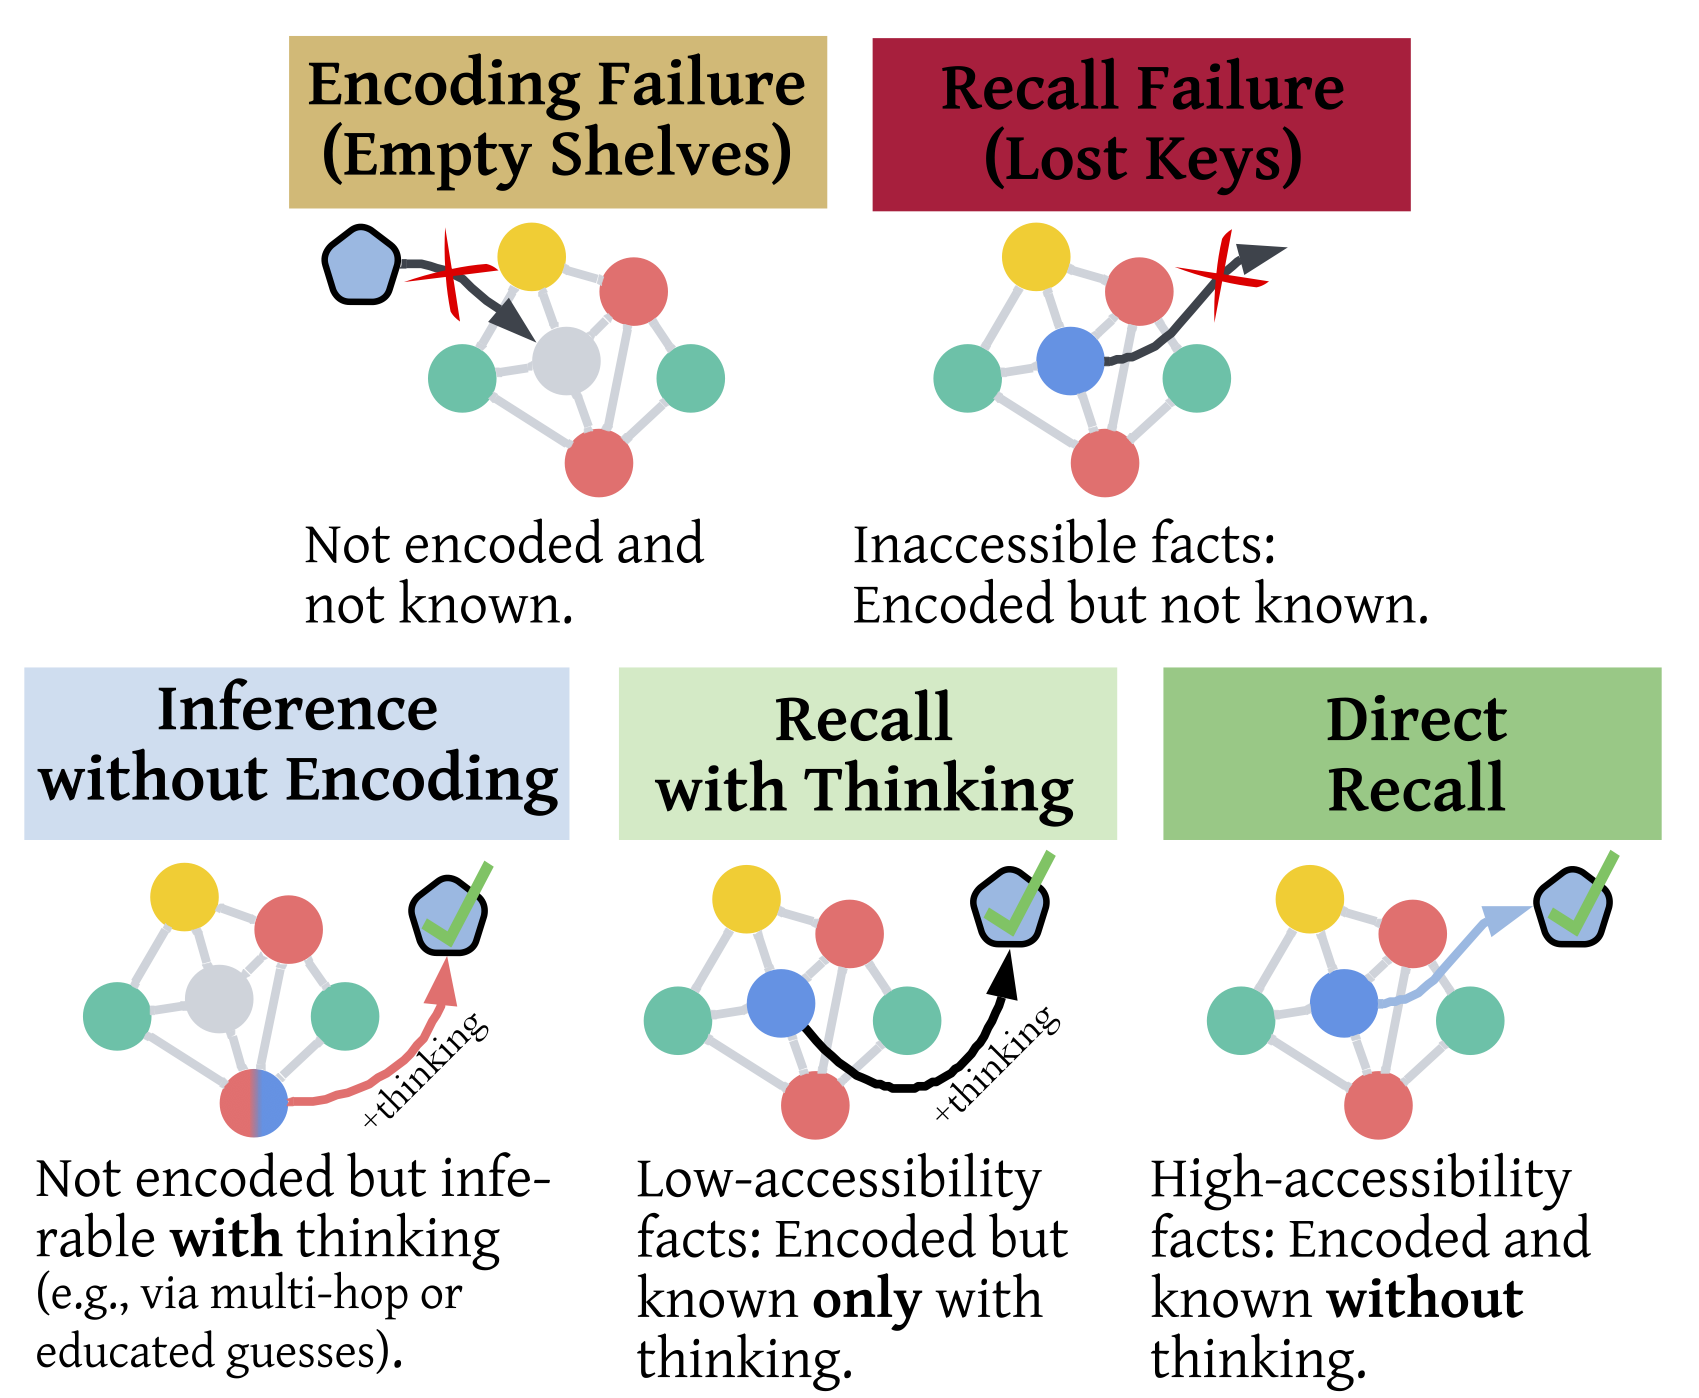
To categorize the failures in AI factuality, the researchers introduce two distinct concepts: "empty shelves" and "lost keys."
-
Empty Shelves: This scenario occurs when the model's parameters do not contain the required information. This could be due to the information being absent from the training dataset or the model failing to compress and store that specific data point during the learning phase. In this case, the "shelf" where the fact should sit is literally empty.
-
Lost Keys: This scenario describes a situation where the information was successfully learned and is stored within the model's parameters, but the model fails to retrieve it when prompted. The "fact" is on the shelf, but the model has "lost the keys" to access that specific location.
By distinguishing between these two modes, the research provides a clearer diagnostic framework for understanding why Large Language Models (LLMs) hallucinate or provide incorrect factual statements.
Identifying Recall as the Bottleneck
The core finding of the Google Research study is that "recall" is the significant bottleneck. This implies that in many instances of factual error, the model actually possesses the necessary information within its parameters (the keys are lost, but the shelves are not empty). The bottleneck is not necessarily the capacity of the model to store facts, but rather the efficiency and accuracy of the mechanisms used to navigate its internal parameter space to retrieve those facts during inference.
This insight is pivotal because it suggests that simply scaling models—adding more parameters or more training data—may not be the most efficient path to perfect factuality. If the bottleneck is recall, then the industry must look toward architectural improvements or training techniques that specifically enhance the model's internal "indexing" and "retrieval" capabilities.
Industry Impact
The identification of recall as the primary bottleneck for parametric factuality has several implications for the AI industry:
- Model Architecture Design: Future AI architectures may prioritize structures that facilitate easier internal information routing and retrieval, moving beyond simple transformer blocks to more sophisticated memory-management designs.
- Training Efficiency: Instead of focusing solely on the breadth of data, researchers might focus on "memorization and retrieval" benchmarks during the training phase to ensure that once a fact is learned, it remains accessible.
- Refining Factuality Benchmarks: The industry may move toward more nuanced evaluations that can distinguish between a model's lack of knowledge and its failure to recall, allowing for more targeted improvements in model development.
- Optimization of LLMs: For developers working on specialized models (e.g., medical or legal AI), this research highlights the importance of ensuring high recall rates for critical domain-specific facts already present in the training set.
Frequently Asked Questions
Question: What is the difference between parametric factuality and RAG?
Parametric factuality refers to the facts a model knows internally through its training (stored in weights). RAG (Retrieval-Augmented Generation) is a technique where the model looks up information from an external source (like the internet or a private database) before generating a response.
Question: Why is recall considered a "bottleneck" in AI?
Recall is considered a bottleneck because even if a model has been trained on a piece of information, it often fails to retrieve that specific information correctly during a conversation. This means the limitation isn't the model's "memory capacity" but its "retrieval efficiency."
Question: How does the "lost keys" analogy help AI researchers?
It helps researchers identify that the problem isn't always a lack of data. If the problem is "lost keys," researchers know they need to improve the model's internal search mechanisms rather than just feeding it more data or making the model larger.