
Inside the Architecture of vLLM: A Comprehensive Breakdown of High-Throughput LLM Inference Systems in 2025
This technical analysis explores the architecture of vLLM, a state-of-the-art high-throughput Large Language Model (LLM) inference system. Based on the V1 engine as of August 2025, the breakdown details the core components that enable efficient inference, including PagedAttention, continuous batching, and advanced scheduling. The article outlines the system's progression from a fundamental offline engine to a sophisticated, multi-GPU serving layer capable of handling concurrent web traffic. Key features such as chunked prefill, prefix caching, and speculative decoding are highlighted as essential for optimizing performance. This overview provides a high-level mental model for developers and researchers interested in the evolution of LLM engines and their role in modern AI infrastructure.
Key Takeaways
- Core Architecture: The vLLM system is built upon a fundamental LLM engine core that utilizes PagedAttention and continuous batching to achieve high-throughput inference.
- Evolution to V1: The analysis focuses on the V1 engine, noting that while the V0 engine is now deprecated, its foundational concepts remain relevant to the current architecture.
- Advanced Optimization: High-level features such as chunked prefill, prefix caching, and speculative decoding are integrated to enhance the efficiency of the prefill and decoding phases.
- Scalability and Serving: vLLM transitions from offline single-GPU execution to a distributed serving layer designed for concurrent web scaffolding and multi-GPU environments.
In-Depth Analysis
The Foundation: LLM Engine and Engine Core
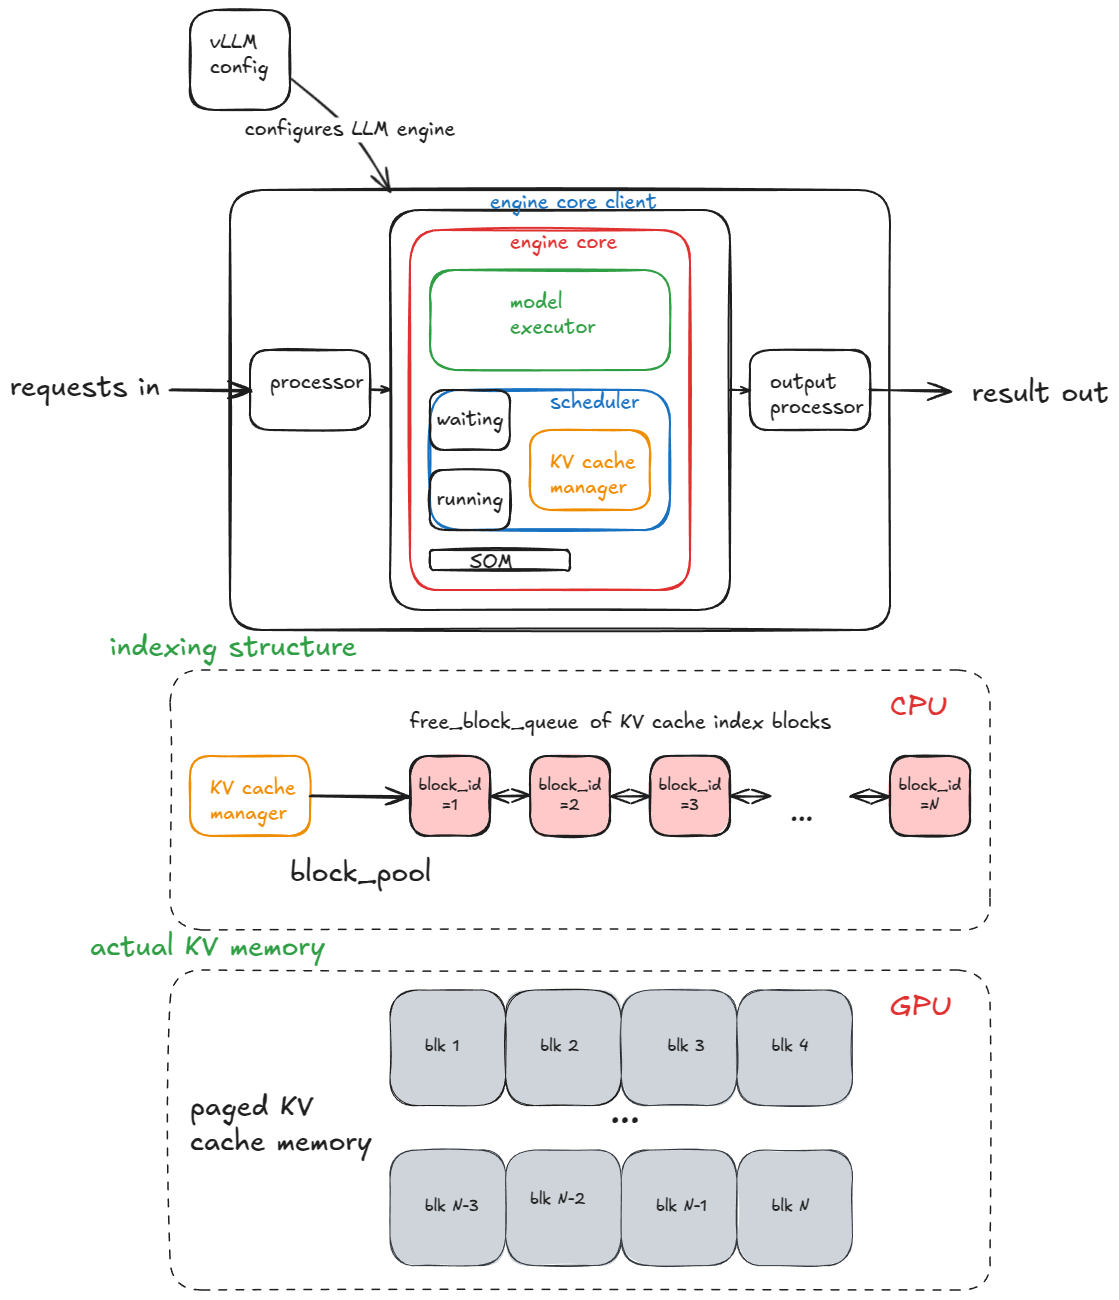
The heart of vLLM's high-throughput capability lies in its Engine Core. This component serves as the fundamental building block of the system, enabling high-performance inference. The core architecture is defined by several critical systems: scheduling, PagedAttention, and continuous batching. These elements work together to manage how requests are processed and how memory is allocated during the inference cycle.
In its basic form, the LLM engine is designed for offline settings. This is illustrated by the system's ability to handle inference tasks using local scripts, where users define prompts and sampling parameters—such as temperature and top_p—to generate outputs. While the engine core provides the necessary throughput, it represents the first layer of a more complex system required for production-level deployment.
Advanced Features and System Scaling
Beyond the fundamental engine core, vLLM incorporates a suite of advanced features aimed at optimizing modern LLM workloads. These include chunked prefill and prefix caching, which improve the handling of input sequences, as well as guided and speculative decoding to refine and accelerate the generation process. The architecture also introduces disaggregated P/D (Prefill/Decoding), a method to separate the initial processing of tokens from the subsequent generation phase to maximize resource efficiency.
As requirements grow, the system scales from single-GPU execution to multi-GPU configurations. This scaling is vital for supporting larger models and increasing total system capacity. The transition from a local engine to a full-scale service is managed by the Serving Layer, which provides the distributed and concurrent web scaffolding necessary to serve models to external users. This layer ensures that the high-throughput capabilities of the core engine are accessible in a real-world, multi-user environment.
Benchmarks and Performance Tuning
A critical aspect of the vLLM anatomy is the focus on Benchmarks and auto-tuning. To ensure the system operates at peak efficiency, it includes tools for measuring latency and throughput. Auto-tuning allows the system to adapt to different hardware and workloads, providing a data-driven approach to performance optimization. This analysis, based on the V1 engine (commit 42172ad from August 2025), reflects the ongoing evolution of the project toward a more robust and scalable inference solution.
Industry Impact
The architecture of vLLM has significant implications for the AI industry, particularly for organizations seeking to deploy Large Language Models at scale. By standardizing high-throughput components like PagedAttention, vLLM provides a blueprint for efficient inference that influences other projects such as SGLang. The move toward disaggregated prefill/decoding and multi-GPU scaling addresses the growing demand for cost-effective and high-performance AI infrastructure. As LLM applications become more prevalent, the ability to serve models with high concurrency and low latency remains a competitive necessity for developers and enterprises alike.
Frequently Asked Questions
What is the primary difference between vLLM V0 and V1?
While the V0 engine is now deprecated, it provided the evolutionary context for the project. The V1 engine is the current focus for state-of-the-art inference, incorporating advanced features and refined scheduling, though many core concepts from the earlier version still carry over.
How does vLLM transition from offline to online serving?
vLLM uses a dedicated Serving Layer that adds distributed and concurrent web scaffolding to the core LLM engine. This allows the system to move from processing local, offline snippets to handling live web requests from multiple users simultaneously.
What are the core components of the vLLM Engine Core?
The Engine Core is composed of fundamental systems including the scheduler, PagedAttention for memory management, and continuous batching, which collectively enable the system to achieve high-throughput inference.

