
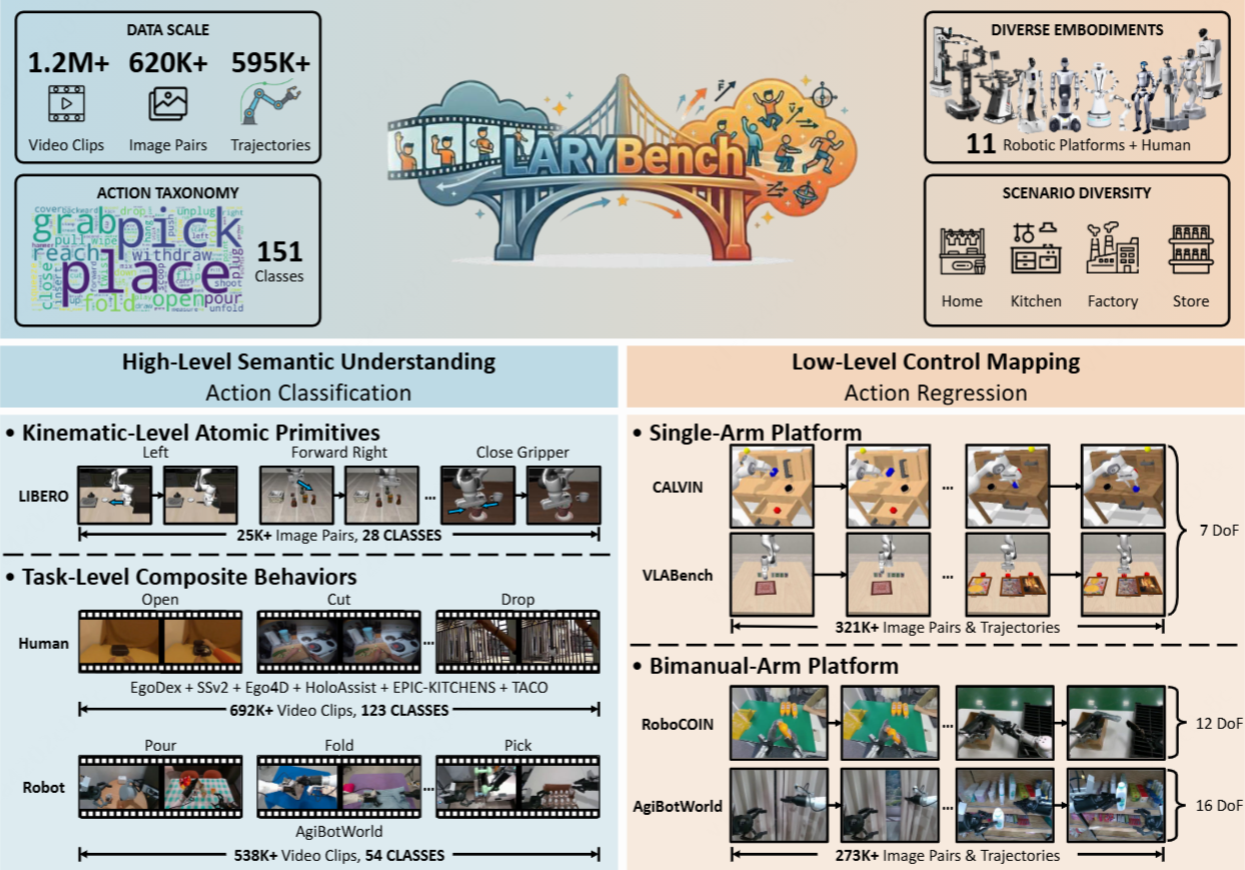
Meituan Technical Team Launches LARYBench: A Systematic Benchmark for Latent Action Representation in Embodied AI
The Meituan Technical Team has introduced LARYBench (Latent Action Representation Yielding Benchmark), a groundbreaking systematic evaluation framework designed to guide the learning of general latent action representations from large-scale visual data. Positioned as a potential 'ImageNet' for the embodied AI field, LARYBench provides the first standardized measurement for generalized representations learned from human videos. Experimental findings indicate a significant shift in the industry: general vision models are now outperforming specialized embodied AI expert models in both action generalization and control precision. This research confirms that sophisticated embodied action representations can effectively emerge from massive human video datasets, offering a new trajectory for the development of autonomous robotic systems and general-purpose artificial intelligence.
Key Takeaways
- Introduction of LARYBench: A new systematic benchmark designed to evaluate latent action representations learned from large-scale visual data.
- Superiority of General Models: General vision models demonstrate significantly better performance in action generalization and control precision compared to specialized expert models.
- Emergence from Human Data: The benchmark proves that embodied action representations can emerge naturally from large-scale human video datasets.
- Standardizing Evaluation: LARYBench serves as a foundational metric, similar to ImageNet, for the field of embodied AI and robotic control.
In-Depth Analysis
Defining the 'ImageNet' for Embodied AI
The release of LARYBench (Latent Action Representation Yielding Benchmark) by the Meituan Technical Team marks a pivotal moment in the evolution of embodied AI. For years, the field has lacked a unified, systematic benchmark to measure how well models learn to represent actions from visual inputs. LARYBench fills this gap by providing a framework that guides the learning of general latent action representations from vast amounts of visual data. By establishing a standardized set of metrics, LARYBench allows researchers to quantify the effectiveness of different models in a way that was previously difficult to achieve. This systematic approach is essential for transitioning from task-specific robotic behaviors to more versatile, general-purpose embodied agents.
General Vision Models vs. Specialized Experts
One of the most striking revelations from the LARYBench experiments is the performance gap between general vision models and specialized embodied AI expert models. Traditionally, the industry has leaned toward developing 'expert' models—systems specifically trained on narrow, embodied datasets to perform specific tasks. However, the data from LARYBench suggests that general vision models, which are trained on broader and more diverse visual information, possess a superior ability to generalize actions and maintain control precision. This finding challenges the prevailing wisdom that specialized training is always superior for high-precision tasks. Instead, it suggests that the broad features learned by general vision models provide a more robust foundation for understanding the physical world and the actions within it.
The Power of Human Video Data
LARYBench provides the first concrete measurement of how embodied representations can be derived from human video data. The benchmark demonstrates that by observing large-scale human videos, AI models can 'emerge' with latent action representations that are applicable to robotic control. This is a significant breakthrough because human video data is far more abundant and easier to collect than specialized robotic trajectory data. The ability to learn from human behavior at scale means that embodied AI can potentially bypass the data bottleneck that has historically slowed the development of complex robotic skills. The emergence of these representations suggests that the underlying logic of human movement and interaction can be distilled into a format that machines can use to navigate and manipulate their environments.
Industry Impact
The introduction of LARYBench is likely to have a profound impact on the AI and robotics industries. By proving that general vision models are more effective than specialized experts, it encourages a shift in research focus toward large-scale pre-training and the utilization of diverse visual datasets. This could lead to a more rapid advancement in the capabilities of general-purpose robots, as developers can now leverage existing vision models and human video archives to improve action generalization. Furthermore, as a standardized benchmark, LARYBench will likely become a critical tool for benchmarking progress, fostering competition, and accelerating the path toward truly intelligent embodied systems that can operate in complex, real-world scenarios.
Frequently Asked Questions
Question: What is the primary purpose of LARYBench?
LARYBench is a systematic benchmark designed to evaluate and guide the learning of general latent action representations from large-scale visual data, specifically focusing on embodied AI applications.
Question: Why did general vision models outperform specialized expert models in the LARYBench tests?
According to the experimental results, general vision models showed superior action generalization and control precision, likely because their broad pre-training allows for a more comprehensive understanding of visual and physical contexts compared to the narrow focus of specialized expert models.
Question: Can AI learn robotic actions just by watching human videos?
Yes, the LARYBench research confirms that embodied action representations can emerge from large-scale human video data, allowing models to learn generalized action patterns that are applicable to control tasks without relying solely on robotic-specific data.