Meituan LongCat Team Unveils WBench: A Systematic Multi-Round Evaluation Benchmark for Interactive Video World Models
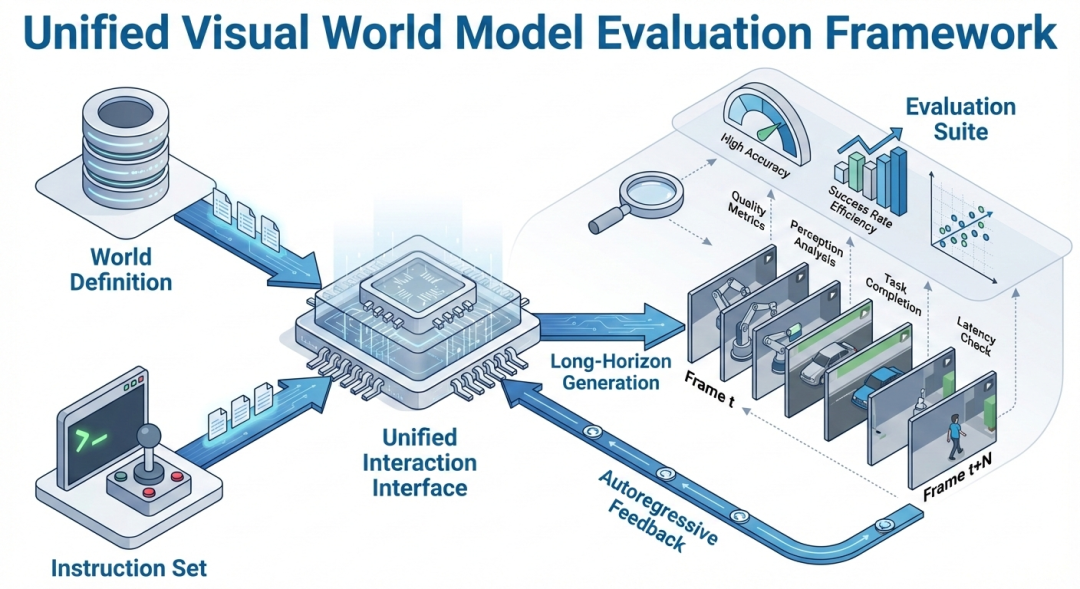
The Meituan LongCat team has introduced WBench, the first systematic multi-round evaluation benchmark specifically designed for interactive video world models. Functioning as a diagnostic "CT scanner," WBench is engineered to identify the specific technical bottlenecks that occur as AI models transition from passive video observation to active, multi-round interaction. By evaluating models across diverse scenarios—ranging from lunar explorations to futuristic cyber cities—the benchmark provides a structured framework to assess how well these systems handle complex, interactive environments. This open-source tool marks a significant advancement in AI research, offering a standardized method to measure the boundaries of current world models and their ability to maintain consistency through iterative engagement.
Key Takeaways
- First Systematic Benchmark: WBench is the first evaluation framework focused on multi-round interaction for video world models.
- Diagnostic Precision: The tool acts as a "CT scanner" to pinpoint exactly where models fail during the transition from passive viewing to active interaction.
- Open-Source Contribution: Developed by Meituan's LongCat team, the benchmark is open-sourced to support the broader AI research community.
- Diverse Testing Scenarios: Evaluation covers a wide range of environments, including lunar landscapes and cybernetic urban settings.
- Focus on Interaction: The benchmark shifts the focus from simple video generation to the complexities of interactive world modeling.
In-Depth Analysis
Bridging the Gap Between Passive Observation and Active Interaction
The emergence of WBench by the Meituan LongCat team addresses a critical gap in the current development of artificial intelligence: the transition from "passive viewing" to "active interaction." Historically, video generation models have been evaluated based on their ability to produce visually coherent sequences from a static prompt. However, the concept of a "world model" implies a deeper level of engagement where the AI can respond to dynamic inputs and maintain a consistent internal logic over time.
WBench serves as a systematic diagnostic tool, described metaphorically as a "CT scanner." This suggests that the benchmark does not merely provide a pass/fail grade but instead offers a granular look at the internal mechanics of a model's performance. By testing how a model handles the shift toward interactivity, WBench can identify the specific "stuck points"—whether they relate to physical consistency, temporal logic, or the ability to process multi-round feedback. This level of detail is essential for researchers looking to move beyond simple generative AI toward systems that can simulate and interact with complex environments.
Systematic Multi-Round Evaluation Framework
A defining feature of WBench is its emphasis on multi-round evaluation. In a standard generative task, a model might only need to produce a single output. In contrast, an interactive world model must sustain its performance across multiple iterations of input and response. WBench tests this capability by simulating scenarios that require the model to maintain state and logic through successive rounds of interaction.
The benchmark utilizes a variety of complex settings, from the low-gravity environment of a "moonwalk" to the dense, neon-lit complexity of a "cyber city." These diverse scenarios are not just for visual variety; they represent different sets of physical and logical rules that a world model must navigate. By standardizing these tests, WBench allows for a direct comparison between different modeling approaches, highlighting which architectures are most effective at preserving world-state across extended interactions. The open-sourcing of this tool ensures that these standards can be adopted and refined by the global AI community, fostering a more collaborative approach to solving the challenges of world modeling.
Industry Impact
The introduction of WBench is poised to have a significant impact on the AI industry by providing a much-needed standard for the evaluation of world models. As the field moves toward more sophisticated applications—such as autonomous robotics, advanced simulations, and interactive digital twins—the ability to accurately measure a model's interactive capabilities becomes paramount.
By open-sourcing WBench, Meituan is not only providing a tool but also establishing a methodology for future research. This helps to move the industry away from subjective assessments of video quality and toward objective, data-driven evaluations of interactive logic. Furthermore, the "CT scanner" approach encourages a more transparent development process, where researchers can share insights into specific failure modes and work collectively to overcome the boundaries of current world model technology. This could accelerate the development of AI systems that are truly capable of understanding and interacting with the physical and digital worlds in a human-like manner.
Frequently Asked Questions
Question: What makes WBench different from existing video evaluation benchmarks?
Unlike traditional benchmarks that focus on the visual quality of a single video output, WBench is the first systematic benchmark designed for multi-round interaction. It evaluates how a world model responds to continuous inputs and maintains consistency over time, rather than just assessing a one-off generation.
Question: Why does the Meituan LongCat team refer to WBench as a "CT scanner"?
The term "CT scanner" is used as a metaphor for the benchmark's ability to provide a deep, diagnostic look at a model's performance. It is designed to precisely locate the technical bottlenecks and specific areas where a model struggles during the transition from passive observation to active interaction.
Question: Is WBench available for public use?
Yes, the Meituan LongCat team has open-sourced WBench, making it available for the global research community to use, evaluate, and build upon for the development of interactive video world models.