Meituan Technical Team Releases LARYBench: A New Standard for Evaluating Latent Action Representations in Embodied AI
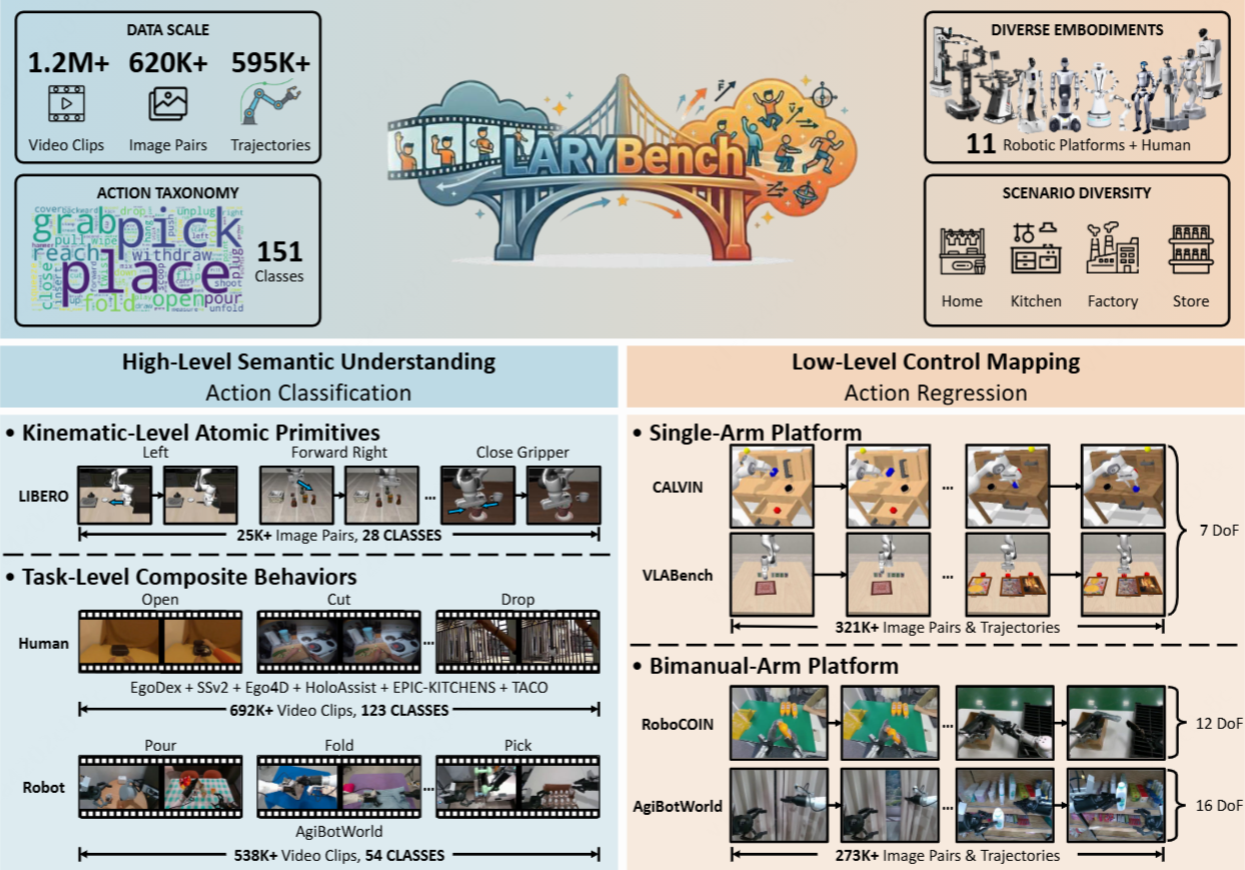
The Meituan Technical Team has officially introduced LARYBench (Latent Action Representation Yielding Benchmark), a systematic evaluation framework designed to guide the learning of universal latent action representations from large-scale visual data. This benchmark represents a significant step in embodied AI, often compared to the 'ImageNet' for action representation. Experimental results released alongside the benchmark reveal that general-purpose vision models significantly outperform specialized embodied AI expert models in both action generalization and control precision. Furthermore, the research demonstrates that embodied action representations can successfully emerge from large-scale human video data, suggesting that specialized datasets may not be the only path toward developing sophisticated robotic control systems.
Key Takeaways
- Introduction of LARYBench: A systematic benchmark designed to evaluate universal latent action representations derived from large-scale visual data.
- Superiority of General Models: General-purpose vision models demonstrate significantly better performance in action generalization and control precision compared to specialized embodied AI expert models.
- Emergence from Human Video: The research proves that embodied action representations can emerge naturally from training on large-scale human video datasets.
- A New Evaluation Standard: LARYBench aims to provide a systematic way to measure how well models learn actions from visual inputs, filling a critical gap in embodied AI research.
In-Depth Analysis
Defining the LARYBench Framework
The Meituan Technical Team has developed LARYBench (Latent Action Representation Yielding Benchmark) to address a fundamental challenge in the field of embodied AI: how to effectively learn and evaluate universal latent action representations. In the context of robotics and AI, a "latent action representation" refers to the underlying mathematical or conceptual understanding of movement and interaction that an AI derives from visual information. By creating a systematic evaluation benchmark, LARYBench provides a standardized environment to test how well different models can interpret visual data and translate it into actionable representations. This benchmark is positioned as a foundational tool, similar to how ImageNet revolutionized visual recognition, but specifically tailored for the complexities of embodied movement and action.
General Vision Models vs. Specialized Experts
One of the most striking findings revealed through LARYBench is the performance gap between general-purpose vision models and specialized embodied AI action expert models. Traditionally, the industry has leaned toward developing "expert" models—AI systems trained specifically on robotic data or narrow embodied tasks—under the assumption that specialization leads to higher precision. However, the experimental results from LARYBench indicate the opposite. General vision models, which are trained on broader and more diverse visual datasets, exhibit significantly higher levels of action generalization. This means they are better at applying learned actions to new, unseen scenarios. Furthermore, these general models also showed superior control precision, suggesting that the breadth of visual understanding inherent in general models provides a more robust foundation for physical control than the narrow focus of specialized experts.
The Role of Large-Scale Human Video Data
A critical discovery highlighted by the LARYBench experiments is the emergence of embodied action representations from large-scale human video data. Previously, it was often debated whether models needed to be trained on first-person robotic data to understand physical actions. The LARYBench results confirm that by observing human movements in vast quantities of video data, AI models can internalize the principles of action and motion. This emergence suggests that the wealth of existing human video content can serve as a primary training ground for embodied AI, allowing models to learn universal representations of action without requiring exhaustive, specialized robotic datasets for every task. This finding validates the potential for scaling embodied AI by leveraging the massive amounts of visual data already available in the digital world.
Industry Impact
The release of LARYBench and its accompanying findings have several major implications for the AI and robotics industries:
- Shift in Training Paradigms: The industry may move away from a reliance on small, specialized embodied datasets toward utilizing massive, general-purpose visual datasets and human video archives. This could significantly lower the barrier to entry for developing capable robotic systems.
- Standardization of Evaluation: LARYBench provides a much-needed metric for measuring progress in latent action representation. This allows researchers to compare different architectures and training methods on a level playing field, accelerating the pace of innovation in embodied AI.
- Validation of Generalist AI: The superior performance of general vision models reinforces the trend toward "foundation models" in AI. It suggests that the path to high-precision robotic control lies in broader visual intelligence rather than narrow task-specific training.
Frequently Asked Questions
Question: What is the primary purpose of LARYBench?
LARYBench is a systematic evaluation benchmark designed to measure and guide the learning of universal latent action representations from large-scale visual data. It serves as a standardized tool for assessing how well AI models can understand and represent actions for embodied intelligence.
Question: Why did general vision models outperform specialized expert models in the tests?
According to the experimental results, general vision models demonstrated better action generalization and control precision. This suggests that the diverse and broad visual information processed by general models allows them to develop a more flexible and accurate understanding of actions compared to models trained only on narrow, specialized datasets.
Question: Can AI learn how to control robots just by watching human videos?
The findings from LARYBench indicate that embodied action representations can indeed emerge from large-scale human video data. This means that models can learn the fundamental principles of action and motion by observing humans, which can then be applied to embodied AI and robotic control tasks.