
Meituan LongCat Team Unveils LongCat-AudioDiT: Revolutionizing Zero-Shot Voice Cloning via Waveform Latent Space Diffusion
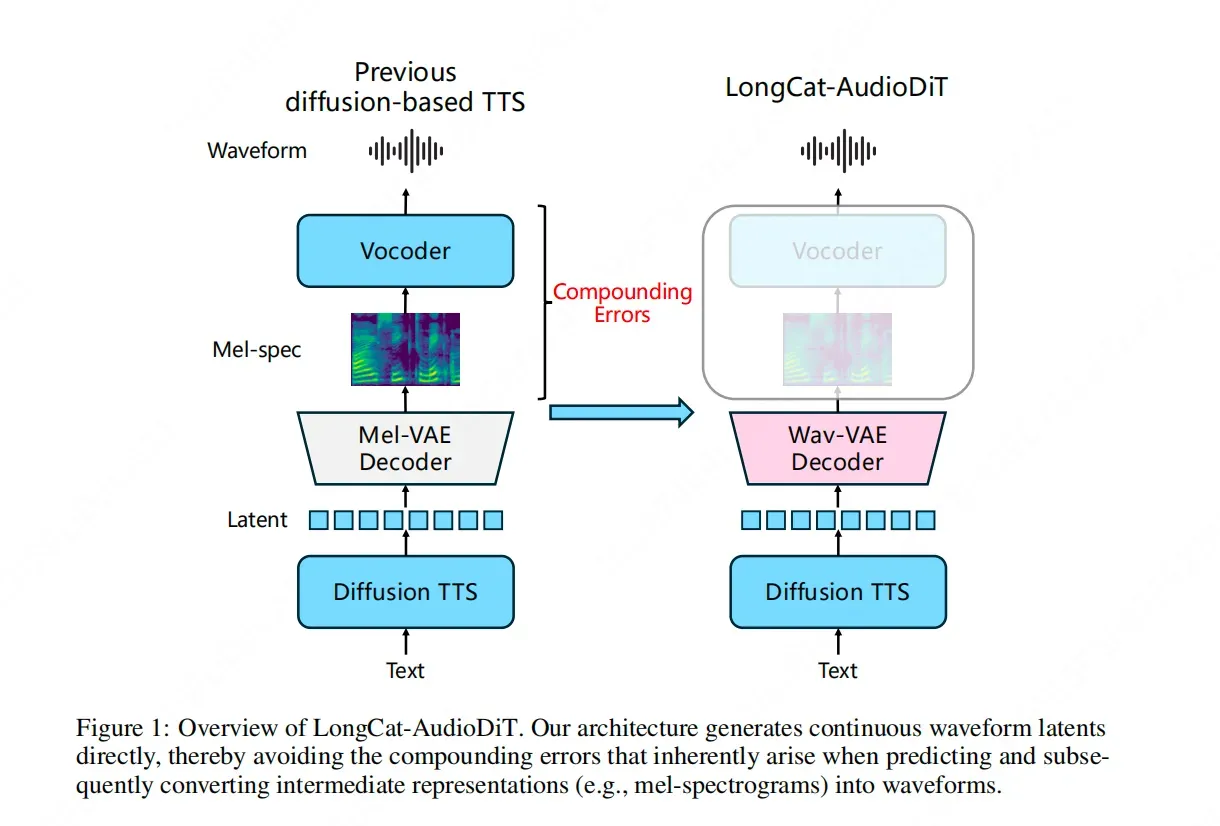
The Meituan LongCat team has introduced LongCat-AudioDiT, a breakthrough model designed to push the boundaries of zero-shot Text-to-Speech (TTS) voice cloning. By fundamentally changing the traditional synthesis pipeline, the model bypasses intermediate representations such as Mel-spectrograms. Instead, it operates directly within the waveform latent space using a diffusion-based approach. This strategic shift aims to eliminate cascade errors typically introduced during data conversion processes. By allowing the AI to learn the inherent patterns of sound directly, LongCat-AudioDiT offers a more streamlined and accurate method for replicating voices without prior training on specific target speakers, marking a significant advancement in audio synthesis technology and addressing long-standing technical bottlenecks in the field of AI-generated speech.
Key Takeaways
- Elimination of Intermediate Representations: LongCat-AudioDiT completely abandons traditional components like Mel-spectrograms to simplify the synthesis process.
- Direct Waveform Latent Space Processing: The model operates within the waveform latent space, allowing the AI to learn the fundamental laws of sound directly.
- Diffusion Model Integration: It utilizes a diffusion-based framework for Text-to-Speech (TTS) tasks to enhance the quality of voice cloning.
- Reduction of Cascade Errors: By removing intermediate conversion steps, the model prevents the accumulation of errors that typically degrade audio quality in multi-stage systems.
- Zero-Shot Capability: The architecture is specifically designed to break the performance ceiling of zero-shot voice cloning, enabling high-fidelity replication without speaker-specific training.
In-Depth Analysis
Bypassing Traditional Mel-Spectrogram Pipelines
In the evolution of Text-to-Speech (TTS) technology, the reliance on intermediate representations has long been a standard practice. Most traditional systems convert text into a Mel-spectrogram—a visual representation of the spectrum of frequencies—before a separate vocoder transforms that spectrogram back into audible speech. However, the Meituan LongCat team identifies this multi-step process as a primary source of technical bottlenecks. LongCat-AudioDiT represents a radical departure from this norm by "completely abandoning" the Mel-spectrogram phase.
The significance of this shift lies in the reduction of what the researchers call "cascade errors." In a traditional pipeline, any inaccuracy in the text-to-spectrogram phase is carried over and often amplified during the spectrogram-to-waveform phase. By removing these intermediate steps, LongCat-AudioDiT creates a more direct path from text input to audio output. This streamlined approach ensures that the AI focuses on the "laws of sound itself," rather than trying to interpret and reconstruct a proxy representation of that sound. This directness is essential for achieving the high level of fidelity required for convincing zero-shot voice cloning, where the model must replicate a voice it has never encountered during its primary training phase.
Diffusion Models in the Waveform Latent Space
At the core of LongCat-AudioDiT's architecture is the use of diffusion models operating within the waveform latent space. Diffusion models have gained prominence for their ability to generate high-quality data by iteratively refining noise into a structured output. By applying this logic directly to the waveform latent space, the LongCat team allows the model to capture the intricate nuances of human speech at a more granular level than traditional methods allow.
Operating in the latent space of the waveform means the model is working with a compressed, yet highly informative, representation of the actual sound wave. This allows the AI to learn the underlying patterns and regularities of audio signals without the computational overhead of processing raw, high-resolution audio files directly, while still avoiding the loss of information inherent in Mel-spectrograms. The result is a system that can synthesize speech that sounds more natural and maintains the unique characteristics of a target voice with greater precision. This focus on the "root" of sound generation is what allows LongCat-AudioDiT to push the upper limits of what is currently possible in zero-shot voice cloning, providing a more robust solution for real-time and high-fidelity audio applications.
Industry Impact
The introduction of LongCat-AudioDiT by Meituan's LongCat team signals a pivotal shift in the AI audio synthesis industry. By demonstrating that intermediate representations like Mel-spectrograms can be bypassed entirely, this research challenges the existing architectural standards for TTS systems. For the broader AI industry, this move toward direct waveform latent space synthesis suggests a future where audio generation is more efficient and less prone to the artifacts caused by multi-stage processing.
Furthermore, the focus on zero-shot voice cloning has significant implications for personalized AI interactions. As the "upper limit" of this technology is pushed higher, the ability to create highly accurate digital voice clones from minimal data becomes more accessible. This could transform various sectors, including digital entertainment, personalized virtual assistants, and accessibility tools, by providing more realistic and expressive synthetic voices. LongCat-AudioDiT sets a new technical benchmark, encouraging other players in the field to explore direct-to-waveform diffusion methods to overcome the inherent limitations of traditional cascade-based synthesis models.
Frequently Asked Questions
Question: What makes LongCat-AudioDiT different from traditional TTS models?
Unlike traditional models that rely on intermediate steps like Mel-spectrograms to bridge the gap between text and sound, LongCat-AudioDiT operates directly in the waveform latent space. This allows it to skip the conversion steps that often introduce errors, leading to a more accurate replication of sound patterns.
Question: How does LongCat-AudioDiT solve the problem of cascade errors?
Cascade errors occur when mistakes in one stage of a multi-step process are passed on and magnified in subsequent stages. LongCat-AudioDiT eliminates these by using a diffusion model to generate speech directly in the waveform latent space, effectively "blocking" the source of these errors at the root of the synthesis process.
Question: What is the benefit of using a diffusion model in this context?
Diffusion models are highly effective at generating complex data by refining noise into a clear signal. In LongCat-AudioDiT, the diffusion model is used to learn the fundamental laws of sound within a latent space, which results in higher-quality audio and more precise voice cloning capabilities compared to older synthesis techniques.