LARYBench Released: Defining the ImageNet for Embodied Action Representation and Measuring Generalization from Human Videos
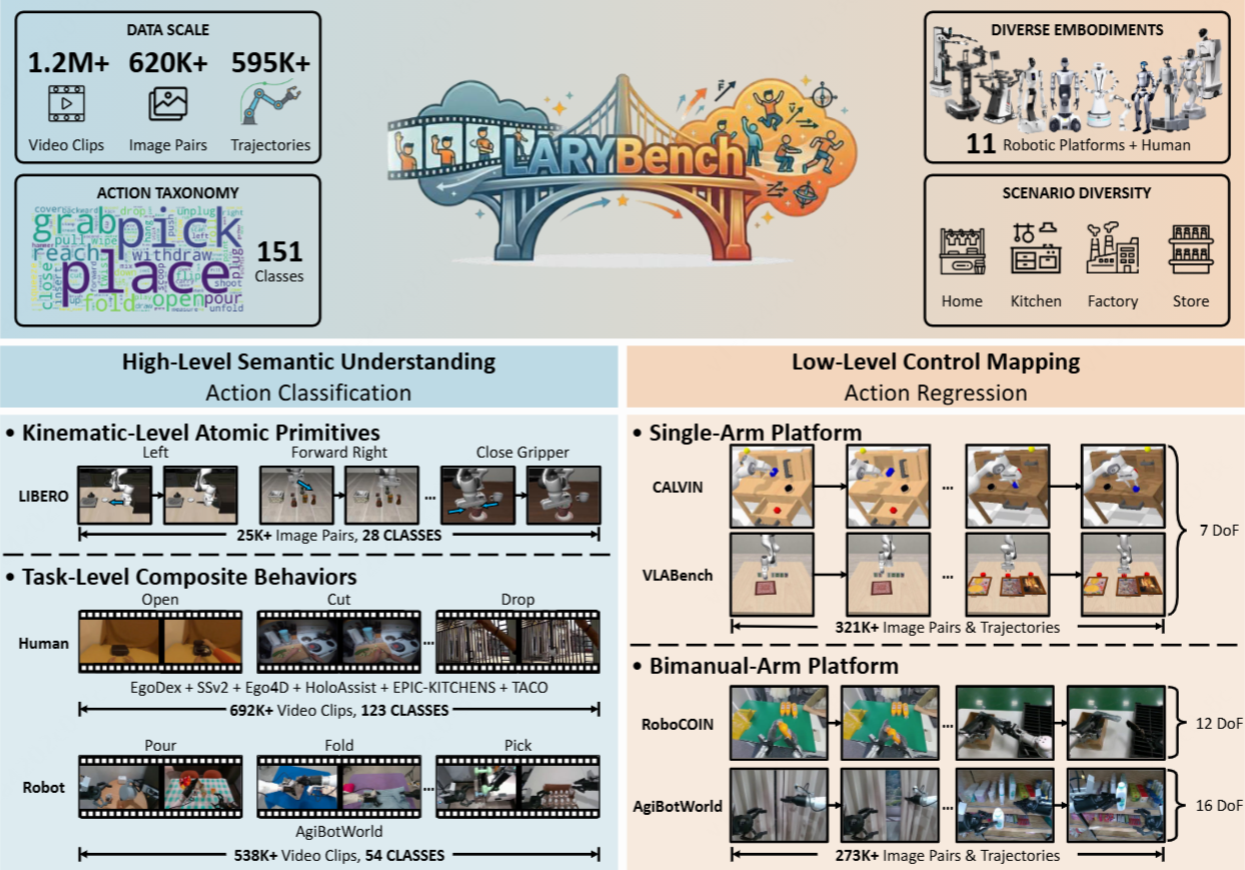
The Meituan Technical Team has officially released LARYBench (Latent Action Representation Yielding Benchmark), a systematic evaluation framework designed to advance the development of general latent action representations. Positioned as the 'ImageNet' for the field of embodied AI, LARYBench provides a standardized methodology for learning from large-scale visual data. The benchmark's initial experimental results reveal a significant shift in AI performance: general vision models consistently outperform specialized embodied AI expert models in both action generalization and control precision. Crucially, the research demonstrates that sophisticated embodied action representations can emerge naturally from large-scale human video data, suggesting a new path for training robots and autonomous systems without relying solely on specialized, task-specific datasets.
Key Takeaways
- Introduction of LARYBench: A systematic benchmark designed to evaluate and guide the learning of general latent action representations from massive visual datasets.
- General Models Outperform Experts: Experimental data shows that general-purpose vision models achieve higher control precision and better action generalization than models specifically designed for embodied AI tasks.
- Emergent Representations: The benchmark proves that embodied action capabilities can emerge from training on large-scale human video data, rather than requiring exclusive robotic execution data.
- Standardizing Embodied AI: LARYBench aims to serve as the 'ImageNet' for embodied action, providing a foundational metric for the industry to measure progress in latent representation learning.
In-Depth Analysis
LARYBench: The Systematic Framework for Latent Action
The release of LARYBench (Latent Action Representation Yielding Benchmark) by the Meituan Technical Team marks a pivotal moment in the evolution of embodied AI. For years, the industry has struggled with the lack of a unified, systematic benchmark to measure how well an AI model understands and represents physical actions. LARYBench addresses this gap by providing a structured environment to evaluate latent action representations. By focusing on 'latent' actions—the underlying mathematical representations of physical movements—the benchmark allows researchers to assess how well a model can translate visual information into actionable intelligence. This systematic approach is essential for moving beyond ad-hoc testing and toward a standardized development cycle similar to what ImageNet provided for computer vision.
The Superiority of General Vision Models
One of the most striking findings revealed through LARYBench is the performance gap between general vision models and specialized embodied action expert models. Traditionally, the industry assumed that 'expert' models, trained specifically on robotic or task-oriented data, would naturally lead in control precision and generalization. However, LARYBench experiments demonstrate the opposite: general vision models, which are trained on broader and more diverse visual datasets, exhibit significantly better performance. This suggests that the diverse features learned by general models provide a more robust foundation for understanding complex physical interactions. These models are not only more precise in their control outputs but also show a superior ability to generalize those actions to new, unseen scenarios—a critical requirement for real-world robotic applications.
Emergence from Human Video Data
Perhaps the most significant theoretical contribution of LARYBench is the validation that embodied action representations can emerge from large-scale human video data. This challenges the notion that robots must be trained primarily on data collected from physical robot hardware. The benchmark shows that by observing human movements at scale, AI models can internalize the latent structures of action and physics. This 'emergence' indicates that the visual patterns found in human activities contain sufficient information to teach a model the fundamentals of embodied movement. This discovery opens the door to utilizing the vast repositories of human video available online to train the next generation of embodied AI, potentially solving the data scarcity problem that has long hindered the field.
Industry Impact
The introduction of LARYBench is expected to have a profound impact on the AI and robotics industries. By establishing a 'ImageNet-like' standard, it provides a clear target for researchers and developers, likely accelerating the pace of innovation in embodied intelligence. The shift in focus from specialized expert models to general vision models could lead to more versatile and cost-effective AI systems, as developers can leverage existing large-scale vision models for physical tasks. Furthermore, the ability to learn from human video data significantly lowers the barrier to entry for training embodied models, as it reduces the dependency on expensive and slow-to-collect robotic execution data. This benchmark sets the stage for a future where general-purpose AI can seamlessly transition from digital understanding to physical action.
Frequently Asked Questions
Question: What is the primary purpose of LARYBench?
LARYBench is a systematic evaluation benchmark designed to measure and guide the learning of general latent action representations from large-scale visual data, serving as a foundational standard for embodied AI.
Question: Why do general vision models perform better than specialized expert models in this benchmark?
According to the experimental results, general vision models demonstrate superior action generalization and control precision because the broad visual knowledge they acquire from diverse datasets allows for a more robust understanding of physical actions compared to models trained on narrow, task-specific data.
Question: Can AI learn to move just by watching videos of humans?
Yes, LARYBench demonstrates that embodied action representations can emerge from large-scale human video data, meaning models can learn the latent structures of physical movement without needing to be trained exclusively on robotic data.