
Meituan LongCat Team Unveils LongCat-AudioDiT: Advancing Zero-Shot TTS Voice Cloning via Waveform Latent Space Diffusion
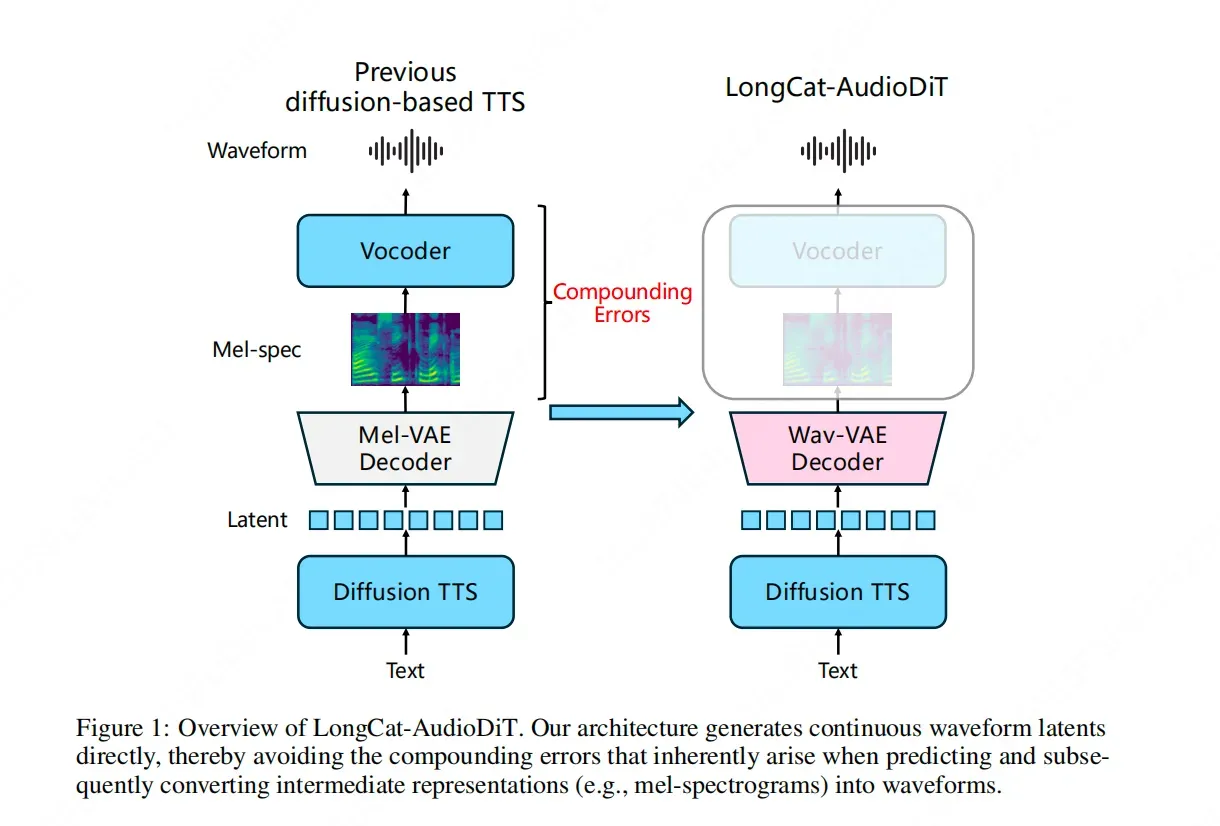
The Meituan LongCat team has officially announced the release of LongCat-AudioDiT, a specialized model designed to push the boundaries of zero-shot Text-to-Speech (TTS) voice cloning. By fundamentally rethinking the audio synthesis pipeline, the team has moved away from traditional intermediate representations such as Mel-spectrograms. Instead, LongCat-AudioDiT operates directly within the waveform latent space using a diffusion-based framework. This strategic shift is intended to eliminate the cascade errors that typically arise during multi-stage data conversion processes in conventional TTS systems. By allowing the AI to learn the inherent patterns of sound directly, the model aims to achieve a higher level of fidelity and accuracy in voice cloning, representing a significant technical breakthrough in the field of generative audio.
Key Takeaways
- Breakthrough in Zero-Shot Cloning: Meituan's LongCat team has launched LongCat-AudioDiT to overcome existing limitations in zero-shot voice cloning technology.
- Elimination of Intermediate Steps: The model completely abandons the use of Mel-spectrograms and other intermediate representations in the synthesis process.
- Waveform Latent Space Diffusion: LongCat-AudioDiT performs text-to-speech generation directly within the waveform latent space using diffusion models.
- Reduction of Cascade Errors: By bypassing traditional conversion stages, the architecture prevents the accumulation of errors that often degrade audio quality.
- Direct Pattern Learning: The system is designed to help AI learn the underlying laws of sound directly, rather than relying on proxy representations.
In-Depth Analysis
Overcoming the Bottlenecks of Traditional TTS
In the evolution of Text-to-Speech (TTS) technology, achieving high-quality zero-shot voice cloning—where a model replicates a voice based on a very short sample without prior training on that specific speaker—has remained a significant challenge. The Meituan LongCat team identified that a primary technical bottleneck lies in the reliance on intermediate representations. Traditionally, TTS systems convert text into a Mel-spectrogram before a separate vocoder transforms that spectrogram into an audible waveform.
LongCat-AudioDiT addresses this by "skipping the middleman." According to the Meituan technical team, the model is designed to let the AI directly learn the inherent laws and patterns of sound itself. By removing the intermediate stages, the team aims to break the current performance ceiling of zero-shot voice cloning, providing a more seamless and integrated approach to audio generation.
The Shift to Waveform Latent Space Diffusion
The core innovation of LongCat-AudioDiT lies in its use of the waveform latent space. Most contemporary diffusion-based TTS models operate on Mel-spectrograms, which are compressed visual representations of audio frequencies. While effective, the conversion between text, Mel-spectrograms, and final waveforms often introduces "cascade errors"—small inaccuracies at each stage that compound to reduce the final output's clarity and resemblance to the target voice.
By implementing a diffusion model (AudioDiT) directly in the waveform latent space, Meituan's approach ensures that the generation process remains closer to the raw audio data. This method blocks the source of data conversion errors at the root. The model focuses on the latent characteristics of the waveform, allowing for a more precise reconstruction of the target voice's unique timbre and prosody. This direct-to-waveform approach represents a fundamental shift in how generative AI handles the complexities of human speech.
Industry Impact
The release of LongCat-AudioDiT marks a pivotal moment for the AI audio industry, particularly in the realm of personalized voice synthesis. By demonstrating that intermediate representations like Mel-spectrograms can be successfully bypassed, Meituan is setting a new architectural standard for high-fidelity voice cloning.
For the broader AI industry, this research highlights the importance of reducing architectural complexity to minimize error propagation. As zero-shot TTS becomes more accurate and easier to deploy, we can expect significant advancements in areas such as digital assistants, content creation, and real-time translation, where the ability to clone a voice accurately and instantly is paramount. LongCat-AudioDiT proves that moving closer to the raw data source—the waveform itself—is a viable and superior path for the next generation of audio AI.
Frequently Asked Questions
Question: What is the main difference between LongCat-AudioDiT and traditional TTS models?
Traditional TTS models usually rely on intermediate representations like Mel-spectrograms to bridge the gap between text and audio. LongCat-AudioDiT abandons these intermediate steps, performing diffusion-based generation directly in the waveform latent space to avoid data conversion errors.
Question: How does LongCat-AudioDiT improve the quality of voice cloning?
By operating directly in the waveform latent space, the model eliminates "cascade errors"—the cumulative inaccuracies that occur when moving between different data formats. This allows the AI to capture the natural laws of sound more accurately, resulting in higher-fidelity zero-shot voice clones.
Question: Who developed LongCat-AudioDiT and what is its primary goal?
LongCat-AudioDiT was developed by the Meituan LongCat technical team. Its primary goal is to break the current technical limits of zero-shot voice cloning and provide a more direct, error-resistant method for high-quality speech synthesis.

