Jagged Intelligence in AI: Why Olympiad Math Success Can Coexist With Everyday Failures
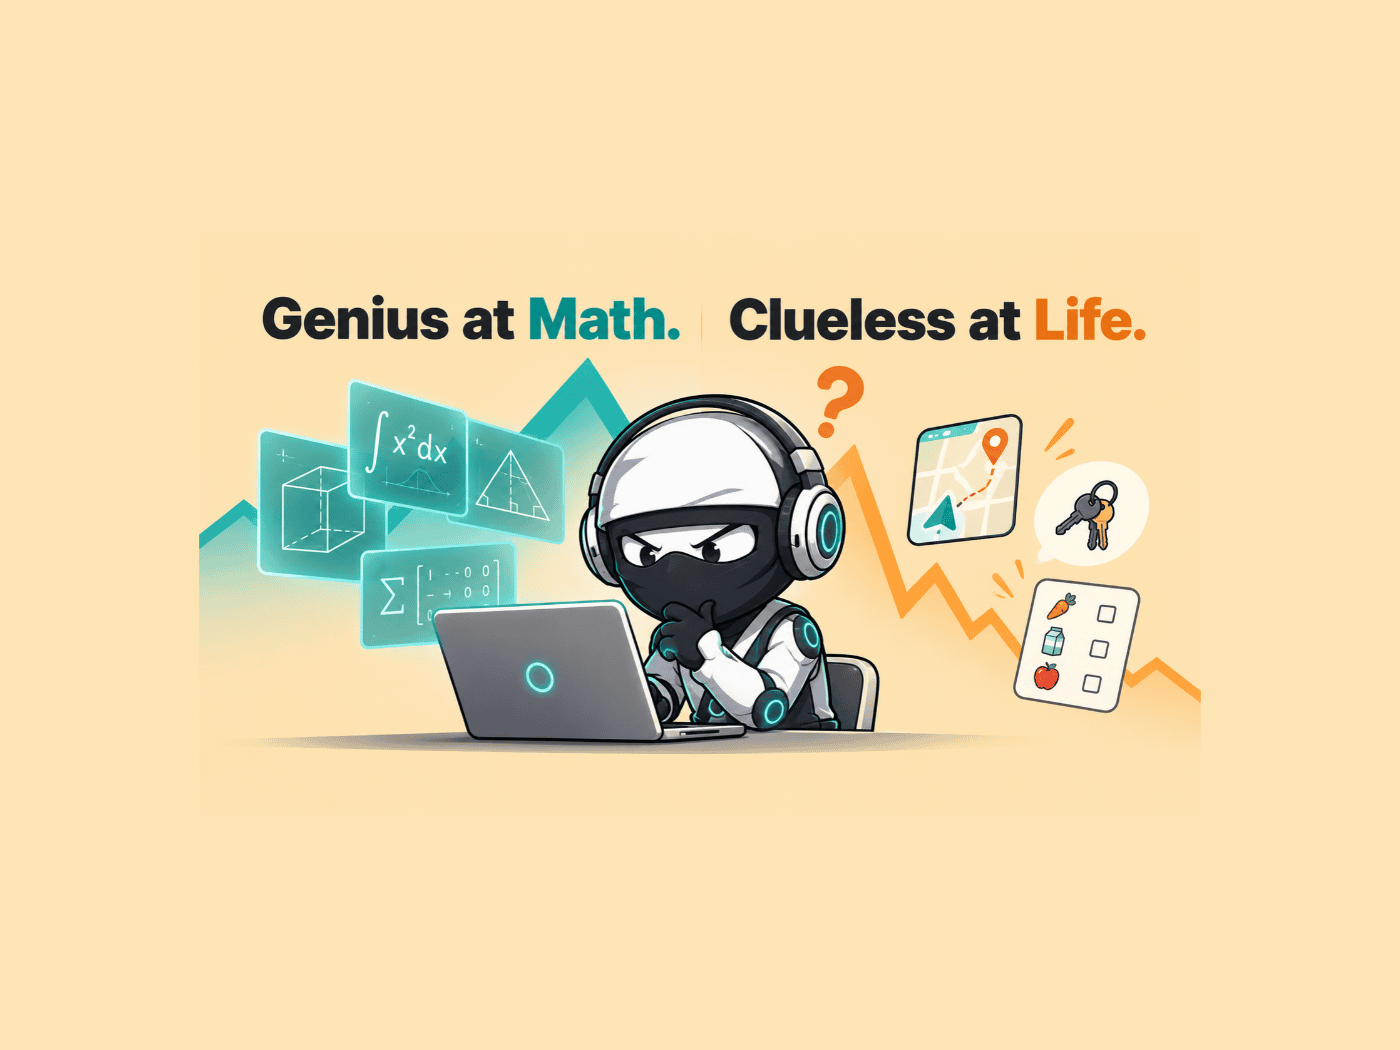
In a KDnuggets article, Nate Rosidi introduces jagged intelligence through a contrast: AI models can excel at Olympiad math and still stumble on simple everyday tasks. The point is not that one result contradicts the other, but that strong performance on a difficult task does not tell readers how the same model will perform on a different kind of task. The title captures that mismatch with the image of AI appearing brilliant one minute and clueless the next. The supplied excerpt establishes the contrast but does not name specific models, give examples of everyday failures, or explain what causes the gap. It supports a discussion of uneven performance, not a conclusion about how often it occurs.
Key Takeaways
- Jagged intelligence is the article’s label for the contrast between impressive AI performance on one kind of task and poor performance on another.
- The original excerpt pairs success at Olympiad math with difficulty on simple everyday tasks.
- Strong performance in one setting and weak performance in another can both be accurate descriptions of the same model.
- The supplied material does not identify specific models, math problems, everyday tasks, or causes for the difference.
In-Depth Analysis
The contrast at the heart of jagged intelligence
Nate Rosidi’s KDnuggets article frames jagged intelligence with a deliberately sharp comparison: models can ace Olympiad math and still fumble simple everyday tasks. The contrast depends on the apparent difficulty of the two categories. Olympiad math is presented as the demanding task, while the everyday tasks are described as simple. If performance followed that ordering, success at the harder task might seem like a reason to expect success at the easier one. The excerpt challenges that expectation without disputing either result. An impressive math performance remains impressive, and a failure on an everyday task remains a failure. What changes is the conclusion a reader can draw from the first result. Doing well on one task is evidence of doing well on that task; it is not, by itself, evidence of doing well on the other. In that sense, the contrast is not a contradiction in the model’s performance. It is a mismatch between the two performances and the expectation that skill on a difficult problem should carry over to a simpler one.
What the headline’s “one minute” framing conveys
The headline describes AI as brilliant one minute and clueless the next. Read alongside the excerpt, that phrasing captures a shift in how a model can appear when the task changes. “Brilliant” reflects the impression created by success at Olympiad math; “clueless” reflects the impression created by a stumble on an everyday task. Neither description needs to be treated as a judgment about the model as a whole. If readers see only the math result, they may miss the weakness illustrated by the everyday-task contrast. If they see only the everyday failure, they may miss the capability illustrated by the math result. Putting the two side by side is what makes the idea of jagged intelligence useful here. The excerpt does not provide a timed sequence or describe a model alternating between success and failure at a particular rate. The headline’s emphasis is on how abruptly the impression of capability can change across tasks, not on an interval the article excerpt has measured.
What the source establishes—and what it leaves open
The supplied excerpt identifies the pattern the article sets out to discuss, but it does not provide enough detail to explain it. It does not name a model, identify an Olympiad problem, specify an everyday task, or say how performance was judged. It also does not say whether the difference is typical, occasional, or concentrated in any particular kind of everyday task. Those distinctions matter because the statement that a model can show this contrast is narrower than the statement that models routinely do so. Likewise, naming the contrast is different from identifying its cause. The article’s title asks why the mismatch occurs, but the supplied excerpt gives no causal account. The supported reading is therefore specific: strong mathematical performance and weak everyday performance can coexist. The excerpt does not establish how large the gap is, what produces it, or which models are most likely to show it.
Industry Impact
For the AI industry, the implication of the contrast is about how model capability is described. A strong result on Olympiad math can be meaningful without settling whether a model handles simple everyday tasks well. The reverse is also true: a failure on an everyday task does not erase the mathematical performance. When either result becomes shorthand for the model’s overall intelligence, the description loses the distinction the article is drawing. The more informative comparison keeps the task attached to the result, so readers can tell what was demonstrated and what remains an open question.
That distinction also matters when the task someone cares about differs from the task used to illustrate a model’s strengths. If the question is whether a model handles a particular everyday task, a math result does not answer it. It may still be an impressive result, but it addresses a different capability. This is an implication of the comparison, not a report of an industry response: the excerpt does not describe any company decisions, changes in evaluation practices, or measured effects on AI products. Its contribution is to show why a single example of success or failure is too narrow a basis for a broad judgment.
Frequently Asked Questions
What does jagged intelligence mean in this article?
It refers to uneven AI performance across tasks. The example is a model performing strongly at Olympiad math while still struggling with simple everyday tasks. The term describes the contrast rather than explaining what causes it.
Does success at Olympiad math show that a model will handle everyday tasks well?
Not by itself. The article’s central point is that success at Olympiad math can coexist with difficulty on everyday tasks. A result in one category does not establish performance in the other.
Does the supplied excerpt explain why models show this contrast?
No. The headline raises the question and the excerpt states the contrast, but the supplied material does not explain its cause or provide specific model results.