BenchMIRT: Decoding the True Utility and Validity of Large Language Model Benchmarks
AllenAI has introduced BenchMIRT on the Hugging Face Blog, a framework designed to scrutinize the effectiveness of current Large Language Model (LLM) evaluation methods. By posing the fundamental question, "What are LLM benchmarks actually measuring?", the project highlights a growing crisis in AI research: the reliance on aggregate scores that may not accurately reflect a model's true capabilities or reasoning depth. BenchMIRT leverages Multidimensional Item Response Theory (MIRT) to move beyond simple accuracy metrics, offering a more granular look at how models interact with individual test items. This initiative marks a significant shift toward psychometric rigor in the AI industry, aiming to solve issues like benchmark saturation and the lack of transparency in model performance comparisons.
Key Takeaways
- Questioning Benchmark Validity: BenchMIRT challenges the industry's reliance on traditional, aggregate scoring systems for LLMs, suggesting they may not capture the full picture of model intelligence.
- Introduction of MIRT: The framework utilizes Multidimensional Item Response Theory (MIRT) to provide a more nuanced, item-level analysis of model performance.
- Addressing Saturation: By analyzing what benchmarks actually measure, BenchMIRT aims to distinguish between genuine model improvement and simple pattern matching or data contamination.
- Collaborative Research: Published via the Hugging Face Blog by AllenAI, the project encourages the AI community to adopt more rigorous psychometric standards for evaluation.
In-Depth Analysis
The Crisis of Confidence in LLM Evaluation
The title of AllenAI’s latest initiative, "BenchMIRT: What are LLM benchmarks actually measuring?", strikes at the heart of a major dilemma in modern artificial intelligence. As Large Language Models (LLMs) become increasingly sophisticated, the benchmarks used to evaluate them—such as MMLU, GSM8K, and HumanEval—are facing a crisis of confidence. The core problem is that a single percentage score often masks the underlying behavior of a model. Researchers are beginning to realize that high scores do not always equate to high reasoning capability; instead, they may reflect a model's ability to memorize training data or exploit specific formatting cues within the test items.
BenchMIRT addresses this by shifting the focus from the "what" (the final score) to the "how" (the relationship between the model and the specific items). This transition is essential because, in the current landscape, many top-tier models are performing within a few percentage points of each other. Without a deeper understanding of what these benchmarks are actually testing, it becomes nearly impossible for developers and users to determine which model is truly superior for specific real-world applications.
Leveraging Multidimensional Item Response Theory (MIRT)
The "MIRT" in BenchMIRT stands for Multidimensional Item Response Theory, a psychometric framework traditionally used in educational testing and psychological assessment. By applying this to LLMs, AllenAI is introducing a level of statistical rigor that has been largely absent from the AI field. Unlike traditional scoring, which treats every question as having equal weight and measuring the same latent trait, MIRT allows for the evaluation of multiple traits simultaneously. It considers the difficulty of an item, the discrimination power of an item (how well it distinguishes between high and low ability models), and the probability of a model guessing the correct answer.
This approach allows BenchMIRT to decompose a benchmark into its constituent parts. For example, instead of saying a model is "80% accurate in mathematics," a MIRT-based analysis could reveal that the model is highly proficient in algebraic logic but struggles with multi-step arithmetic, or that its success is highly dependent on the specific phrasing of the prompt. This granularity is vital for identifying the specific strengths and weaknesses of different architectures, such as Transformers versus newer state-space models.
Beyond Accuracy: The Search for Latent Traits
The fundamental inquiry of BenchMIRT—what is being measured—suggests that benchmarks may be capturing "latent traits" that researchers didn't intend to test. These could include the model's familiarity with specific datasets, its sensitivity to prompt templates, or its ability to follow instructions rather than its actual knowledge of the subject matter. By using the BenchMIRT framework, the AI community can begin to map these latent traits and understand how they contribute to the observed performance.
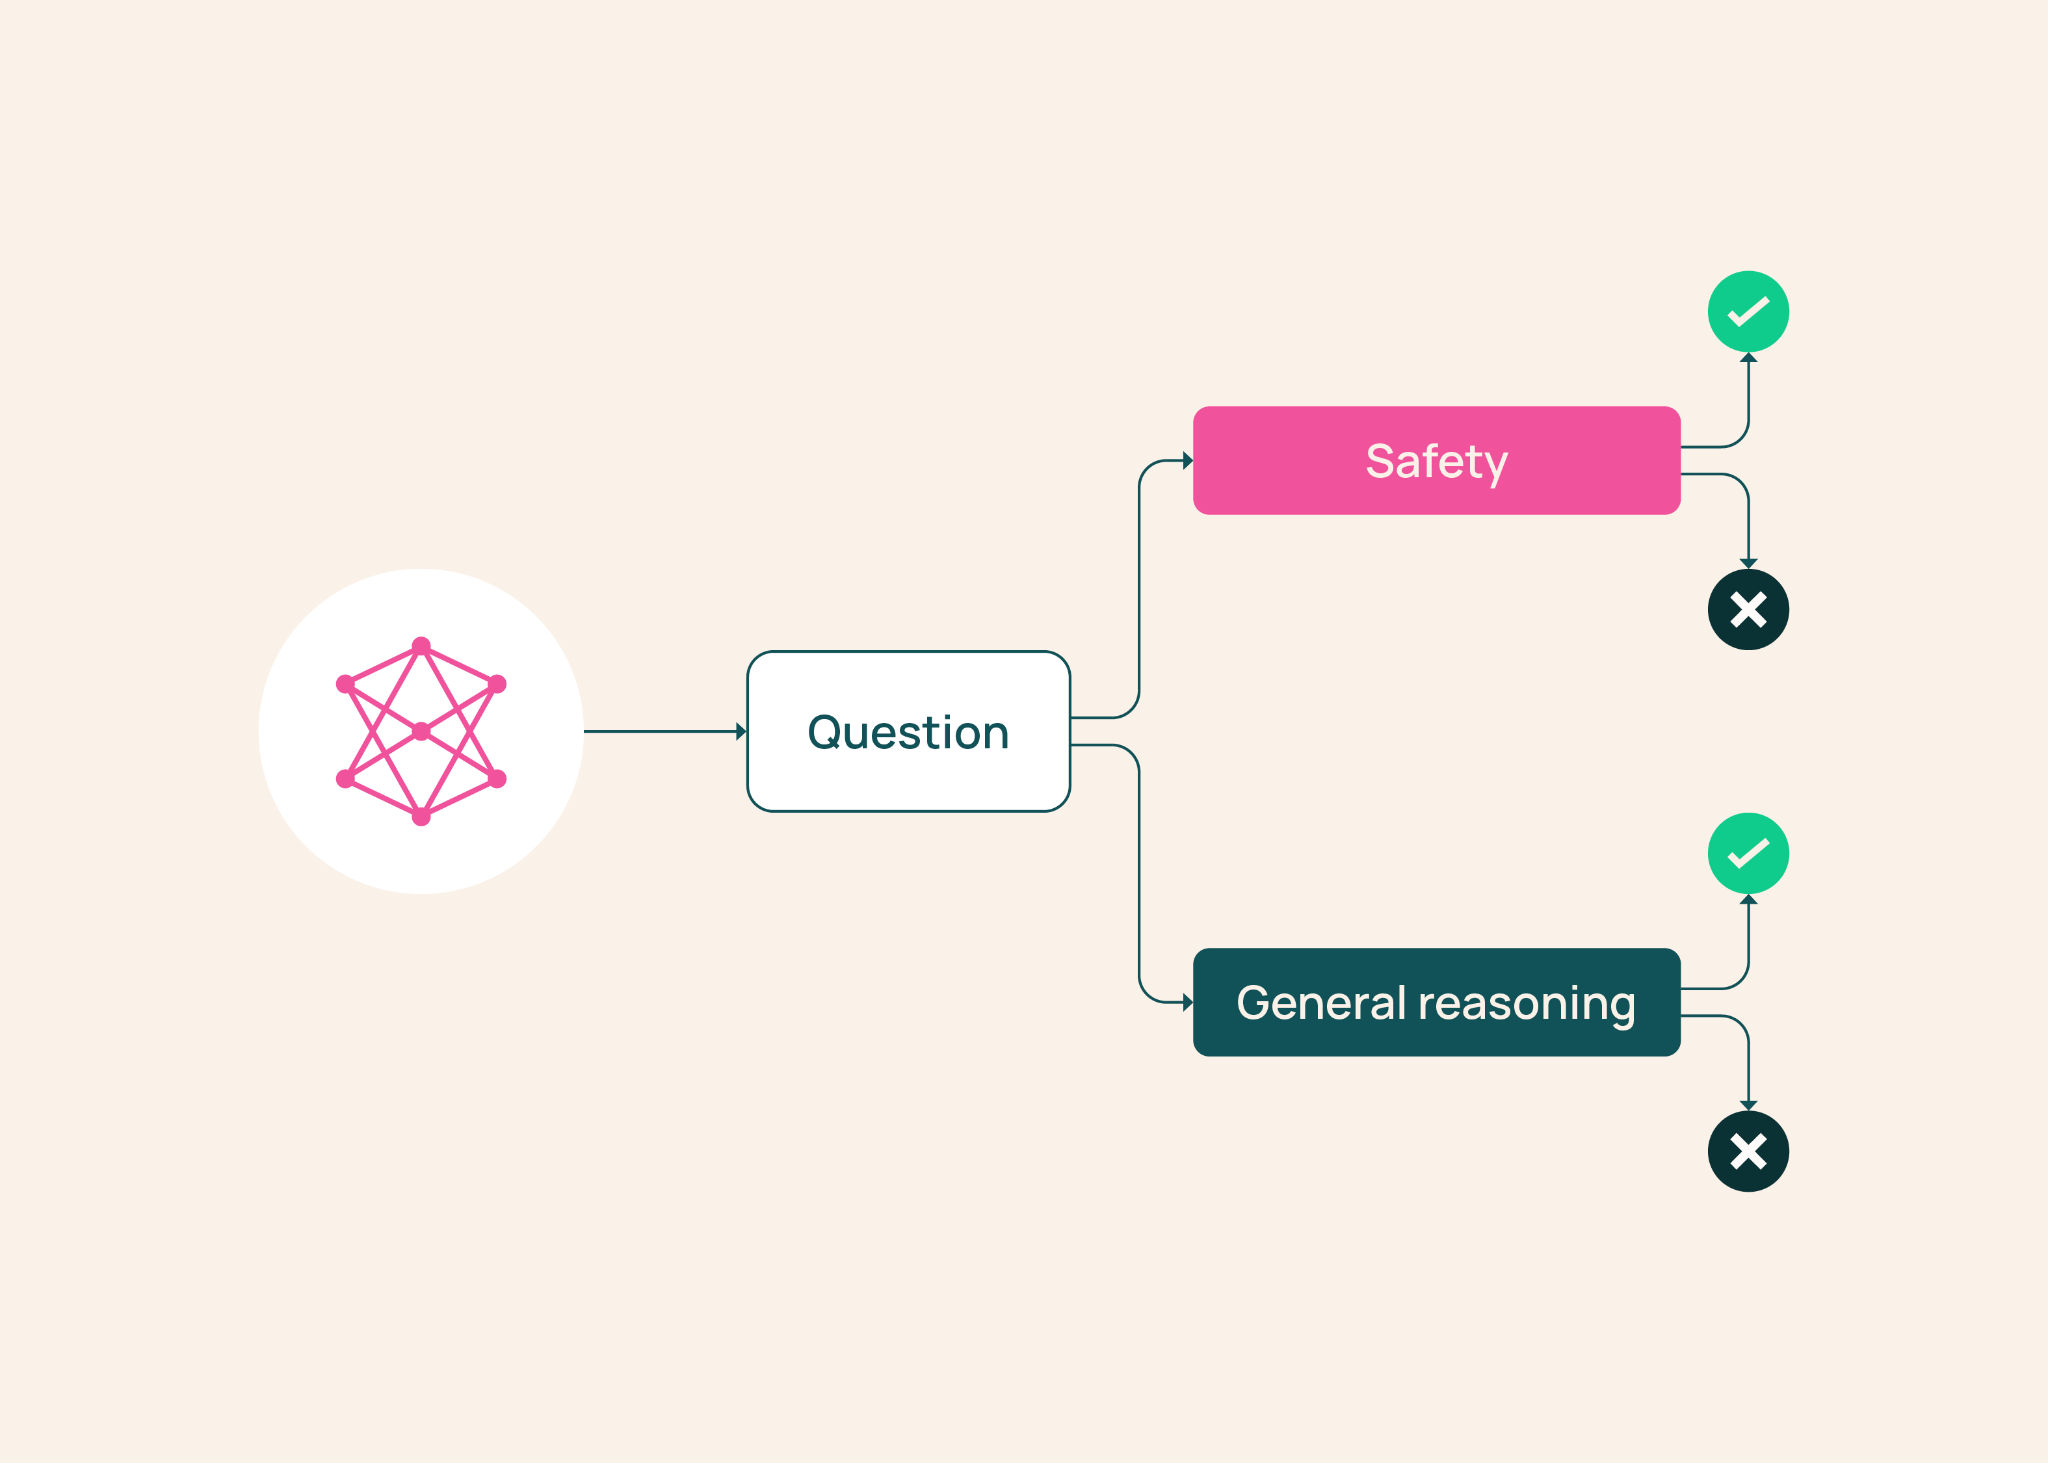
This deeper level of analysis is particularly important for safety and alignment. If a benchmark is supposed to measure a model's ethical reasoning but is actually measuring its tendency to provide "safe-sounding" boilerplate responses, the benchmark is failing its primary purpose. BenchMIRT provides the mathematical tools to identify these discrepancies, ensuring that when a model improves on a benchmark, it is improving for the right reasons.
Industry Impact
The introduction of BenchMIRT by AllenAI on the Hugging Face platform is likely to have a profound impact on how AI models are developed and marketed. First, it sets a new standard for transparency. As the industry moves away from "leaderboard chasing," developers will be pressured to provide more detailed psychometric profiles of their models. This will benefit enterprise users who need to know exactly how a model will perform in specialized domains where general benchmarks are insufficient.
Second, BenchMIRT could lead to the creation of more efficient and robust benchmarks. By identifying which items in a test are redundant or non-discriminatory, researchers can create smaller, more effective evaluation sets that provide higher signal-to-noise ratios. This reduces the computational cost of evaluation and speeds up the development cycle.
Finally, this framework encourages a more scientific approach to AI. By borrowing proven methodologies from psychometrics, the AI field can move past the "black box" era of evaluation and toward a future where model capabilities are understood with mathematical precision. This is a crucial step toward building trustworthy and reliable AI systems that can be deployed in critical infrastructure and professional services.
Frequently Asked Questions
Question: What is the main goal of the BenchMIRT framework?
The main goal of BenchMIRT is to provide a deeper, psychometric analysis of LLM benchmarks. It aims to move beyond simple accuracy scores to understand the specific traits and item-level interactions that determine a model's performance, effectively answering what these benchmarks are actually measuring.
Question: Why is Item Response Theory (IRT) better than traditional scoring?
Traditional scoring often treats all questions as equal and provides only a surface-level view of performance. IRT (and specifically MIRT) accounts for item difficulty, the ability of a question to discriminate between models, and the multidimensional nature of intelligence, providing a much more accurate and granular assessment of a model's true capabilities.
Question: How does BenchMIRT help with the problem of benchmark saturation?
Benchmark saturation occurs when many models achieve near-perfect scores, making it hard to distinguish between them. BenchMIRT helps by identifying which specific items are still challenging for models and by revealing whether high scores are due to actual capability or other factors like data contamination, allowing for a more rigorous comparison of top-tier models.