Optimizing Large Language Models: A Guide to Quantization and Pruning for Efficiency
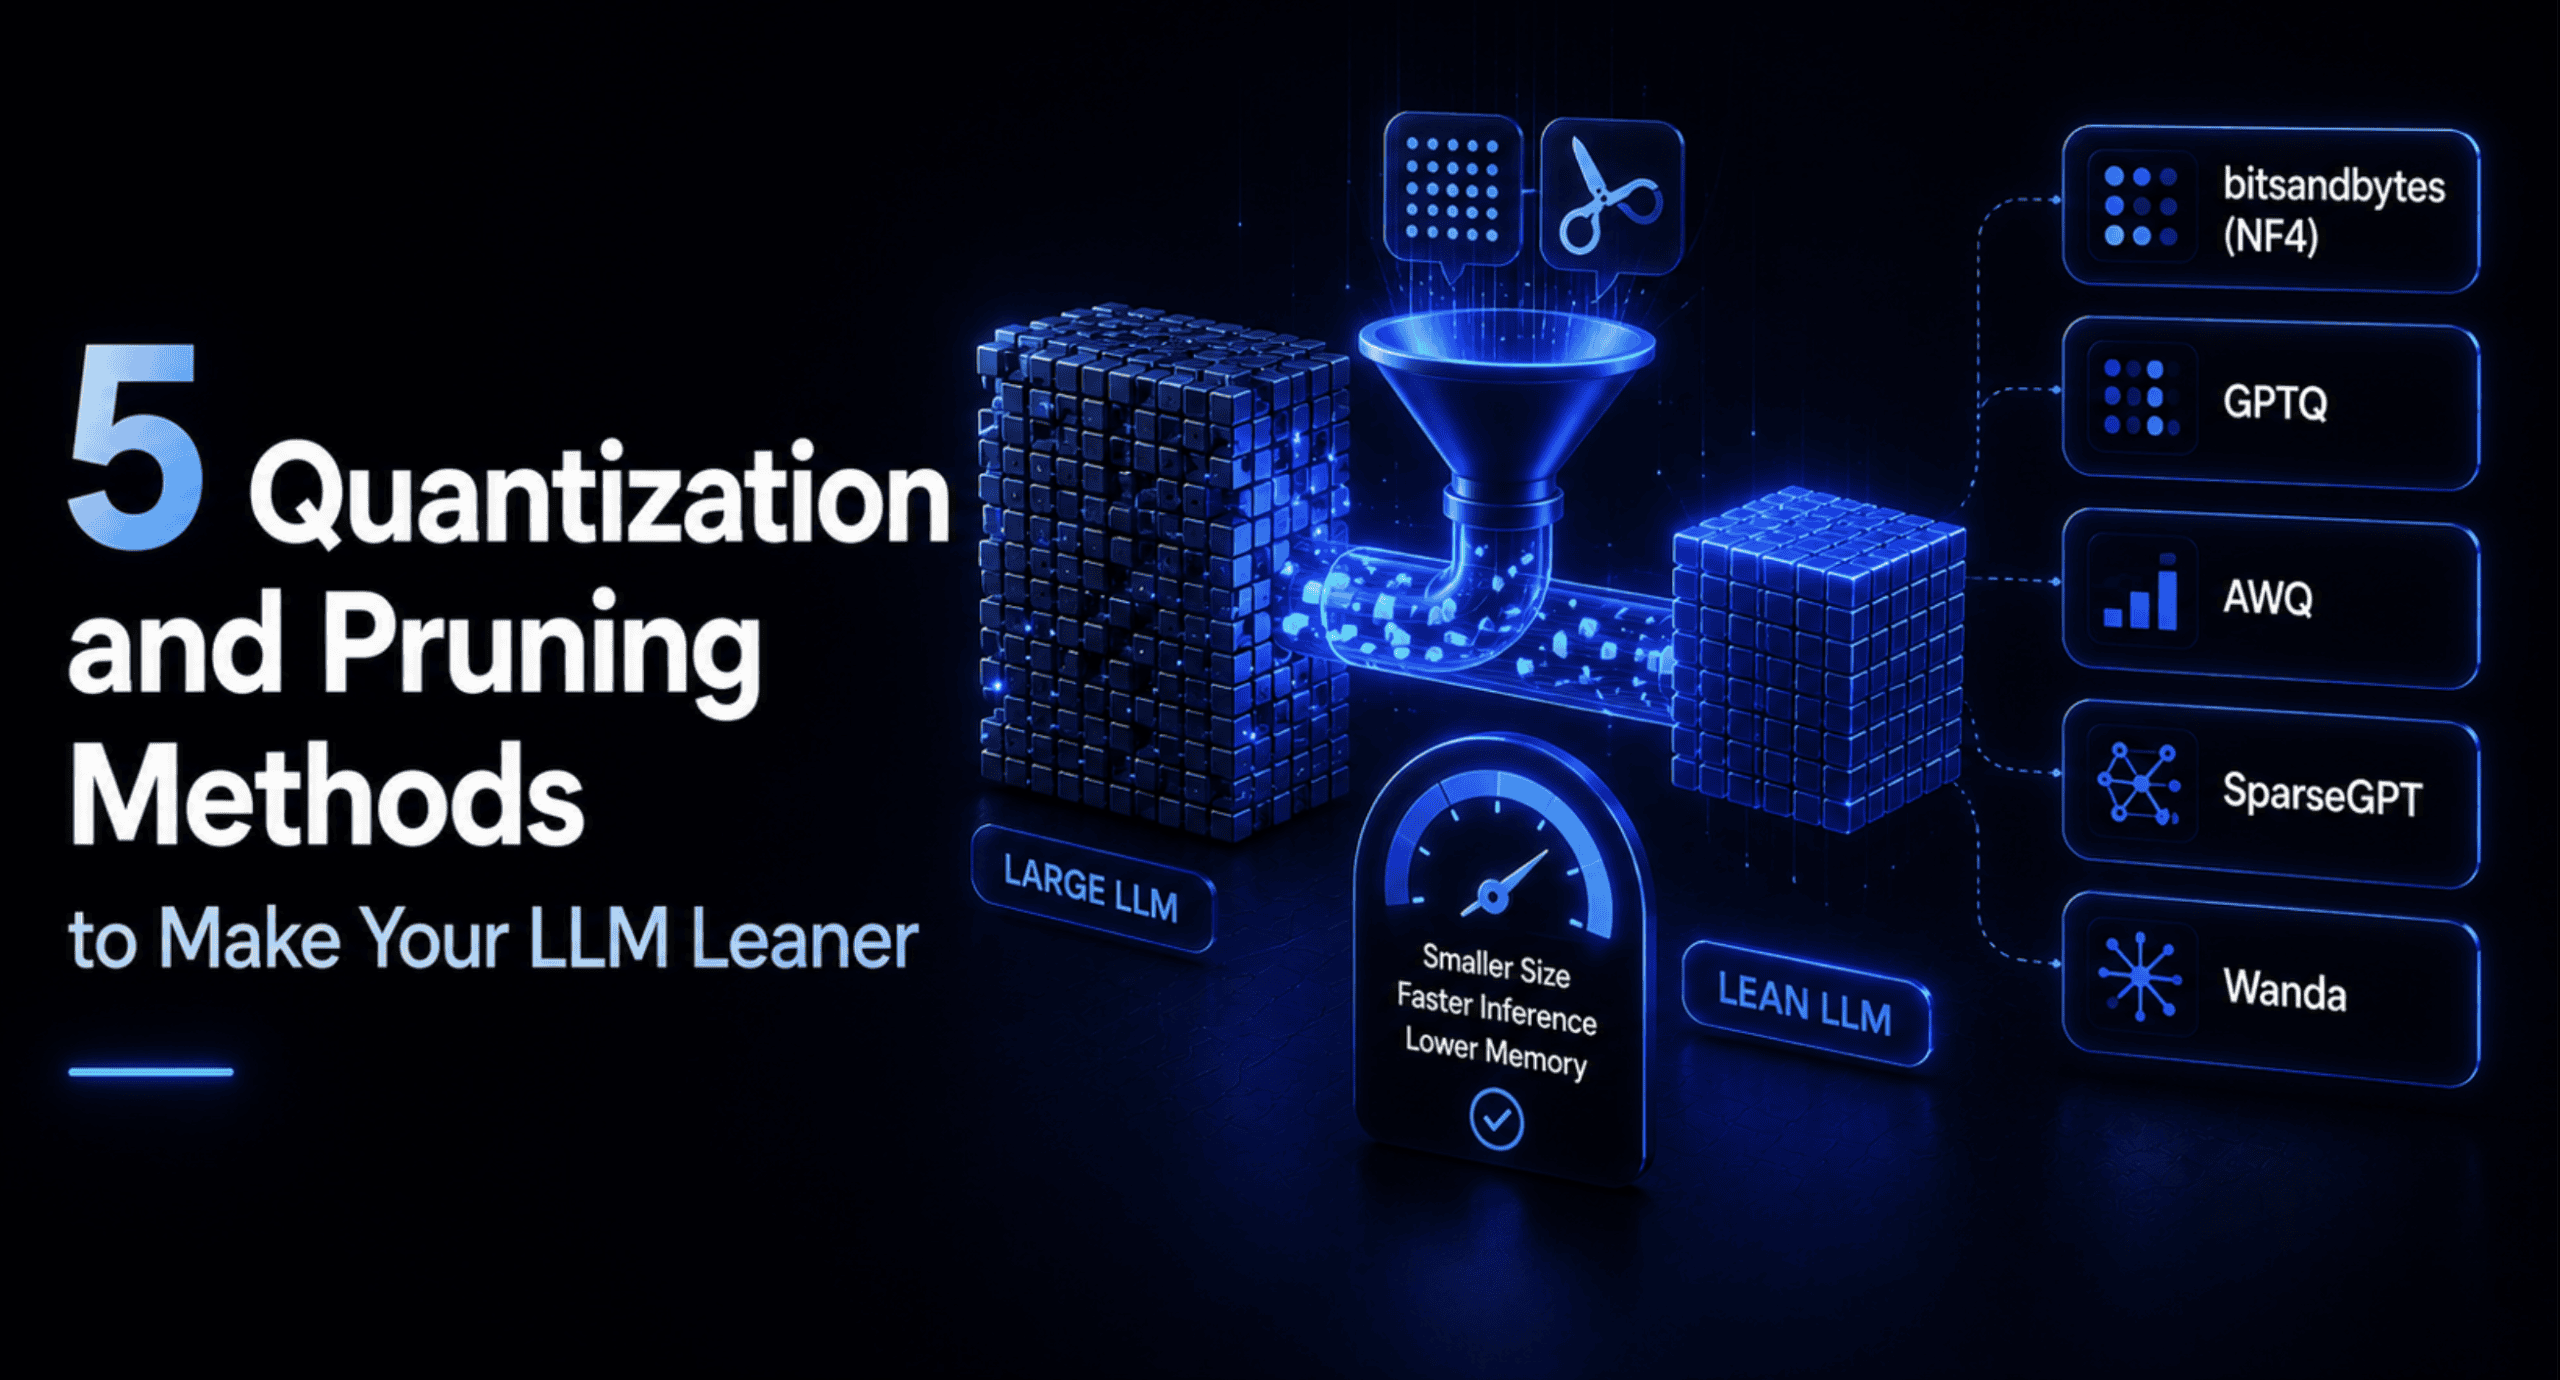
This analysis explores essential techniques for streamlining Large Language Models (LLMs) as detailed in a recent guide by Shittu Olumide for KDnuggets. The core focus is on quantization and pruning—two methodologies designed to make LLMs leaner and more efficient. The article emphasizes that neglecting these optimization steps leads to substantial real-world consequences, specifically regarding increased operational costs and higher latency. By examining five specific methods currently utilized in production environments, the guide provides a practical framework for developers to enhance model performance without sacrificing functional integrity. This structured overview highlights the critical balance between model size and computational efficiency in modern AI deployment.
Key Takeaways
- Optimization is Essential: Implementing quantization and pruning is no longer optional for organizations looking to deploy LLMs efficiently.
- Cost and Latency Penalties: Skipping these optimization techniques results in measurable increases in latency and significant financial overhead.
- Production-Ready Solutions: There are at least five specific, hands-on methods currently being used in production to make LLMs leaner.
- Functional Understanding: Success requires a deep dive into what each technique does and how they impact the model's architecture.
In-Depth Analysis
The Economic and Performance Impact of Model Optimization
In the current landscape of artificial intelligence, the deployment of Large Language Models (LLMs) often faces hurdles related to hardware requirements and operational expenses. The original report by Shittu Olumide highlights a critical reality for AI practitioners: failing to optimize models through quantization and pruning is a costly mistake. These techniques are not merely theoretical improvements but are essential for reducing the 'real money' spent on cloud resources and computational power.
When models remain unoptimized, they suffer from high latency, which directly affects user experience and system responsiveness. In production environments where milliseconds matter, the latency cost of an unoptimized LLM can lead to decreased user engagement and higher churn. By making models 'leaner,' developers can ensure that their applications remain competitive and cost-effective, addressing the dual challenges of performance bottlenecks and budget constraints.
Practical Implementation: Quantization and Pruning Methods
The transition from a standard model to a production-ready, lean LLM involves specific methodologies that alter how the model handles data and weights. Quantization typically involves reducing the precision of the numbers representing model weights, while pruning involves removing unnecessary parameters that do not significantly contribute to the model's output.
The guide focuses on five specific methods that are currently being run in production. This hands-on approach suggests that the industry is moving away from experimental optimization toward standardized, reliable techniques. By walking through what each technique actually does, the analysis provides a roadmap for developers to move beyond default configurations. Understanding the mechanics behind these five methods allows teams to select the right optimization strategy based on their specific hardware constraints and performance goals, ensuring that the 'leaner' version of the model maintains its required accuracy while operating at peak efficiency.
Industry Impact
The shift toward leaner LLMs through quantization and pruning has profound implications for the AI industry. As models continue to grow in size and complexity, the ability to compress these models without losing significant performance is becoming a primary competitive advantage. This trend democratizes access to high-performance AI, allowing smaller organizations to run sophisticated models on less expensive hardware. Furthermore, the emphasis on reducing latency and cost aligns with the industry's broader goal of sustainable and scalable AI deployment. As production-ready methods become more widely documented and adopted, we can expect a standard shift where optimization is integrated into the initial stages of the model deployment lifecycle rather than being treated as an afterthought.
Frequently Asked Questions
Question: Why are quantization and pruning considered critical for LLM deployment?
According to the original content, these techniques are critical because skipping them leads to real-world costs in terms of both money and latency. They are essential for making LLMs leaner and more suitable for production environments where efficiency is paramount.
Question: How many specific methods are currently highlighted for production use?
The guide identifies five specific methods that are currently being utilized in production environments to optimize LLMs, providing a hands-on approach for developers to follow.
Question: What are the primary risks of ignoring model optimization techniques?
The primary risks include increased operational latency and higher financial costs. Without these techniques, models remain bulky and inefficient, which can negatively impact the overall performance and sustainability of AI-driven applications.