
LiquidAI Announces LFM2.5-DSpark: Achieving Up to 3.2x Faster Inference Performance
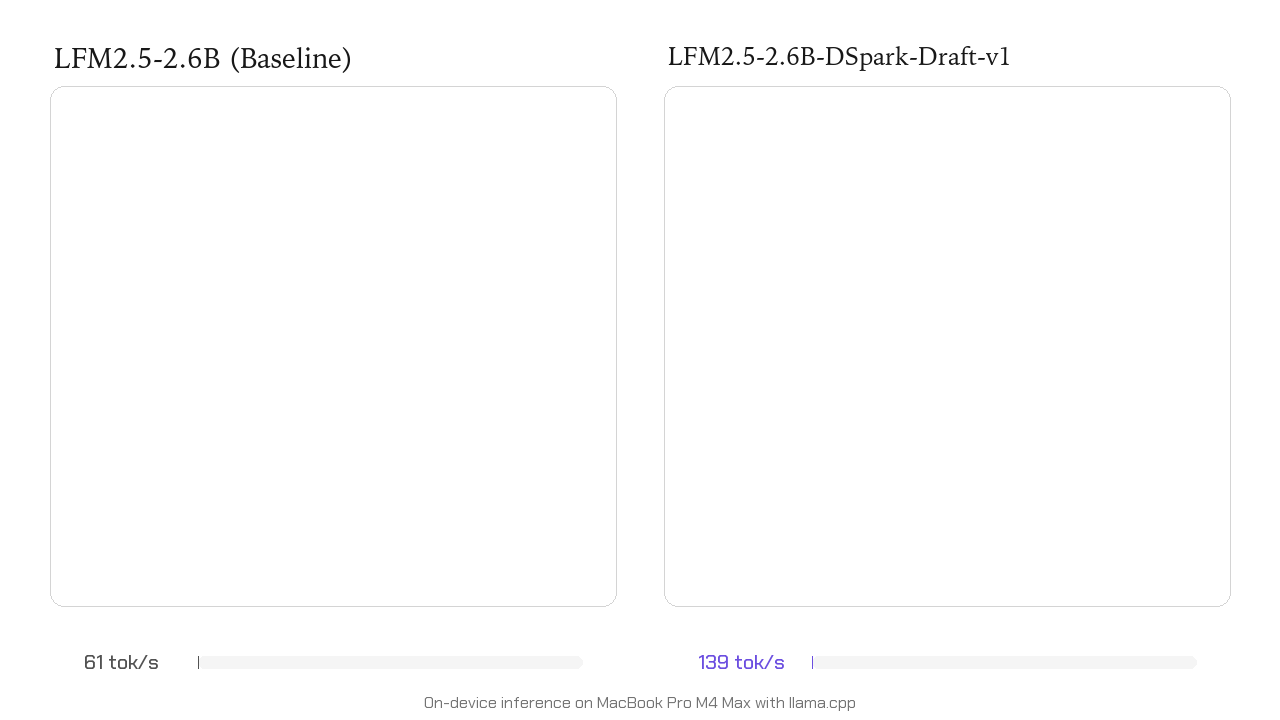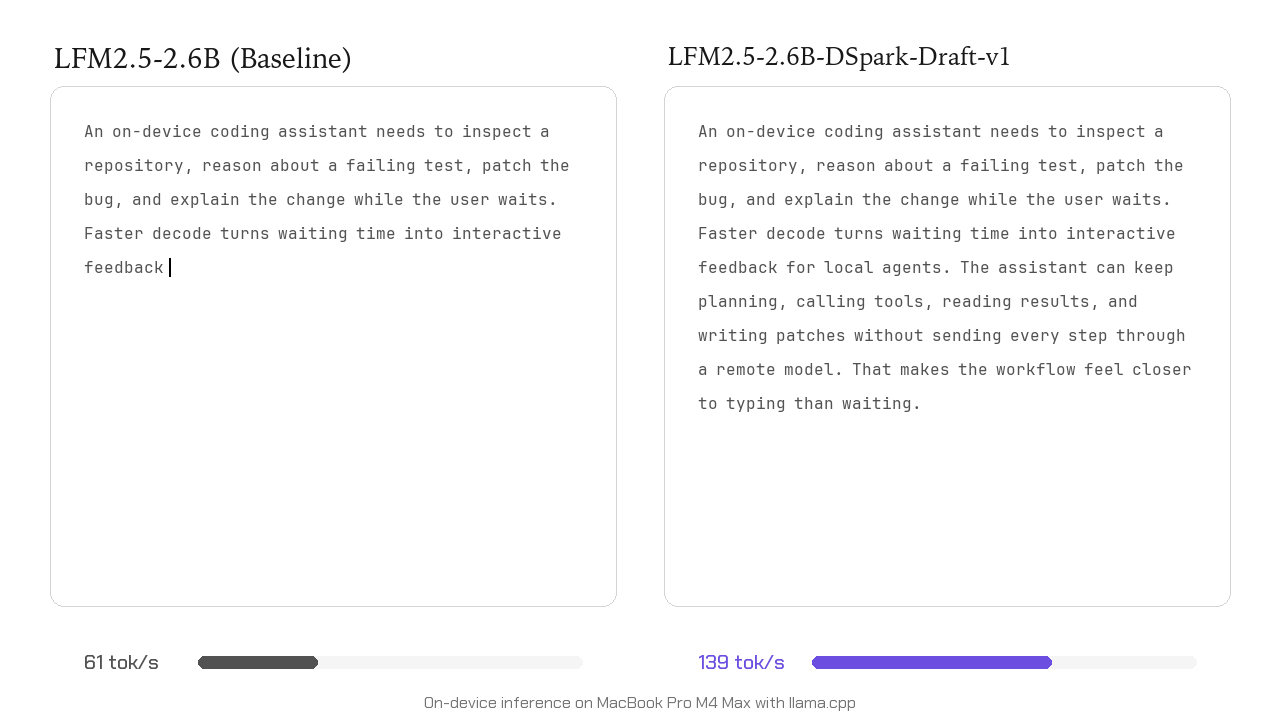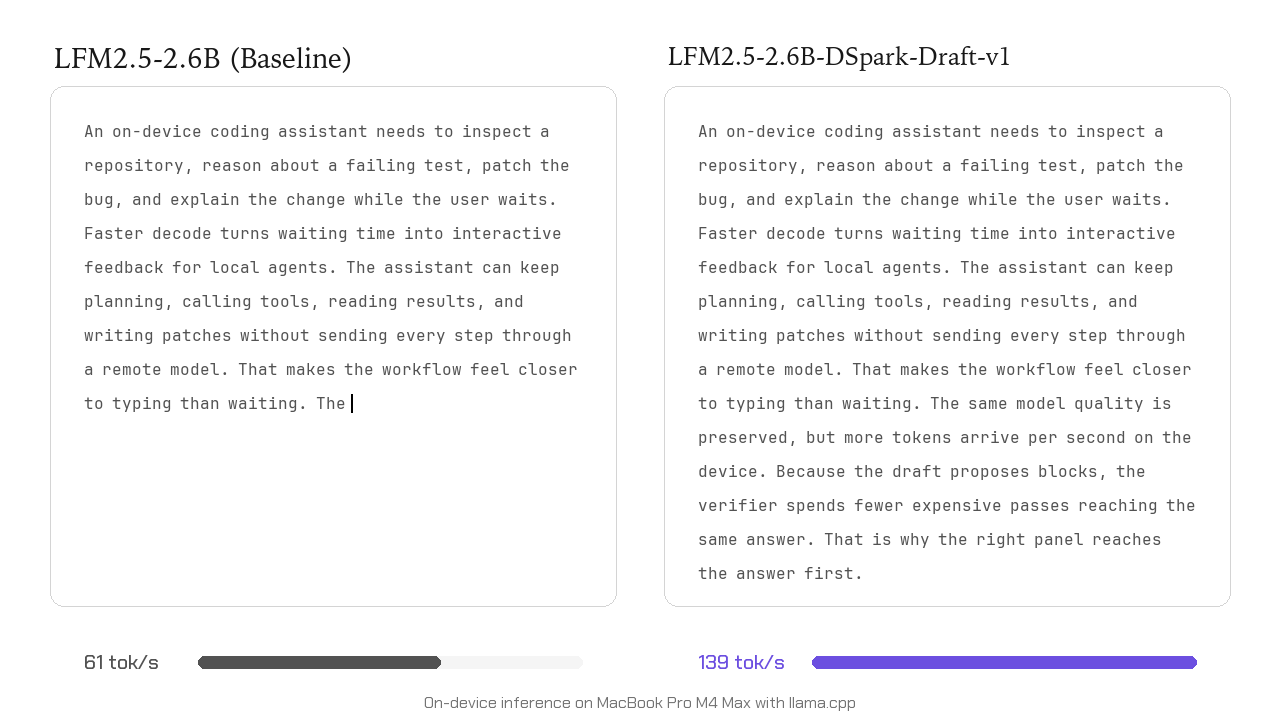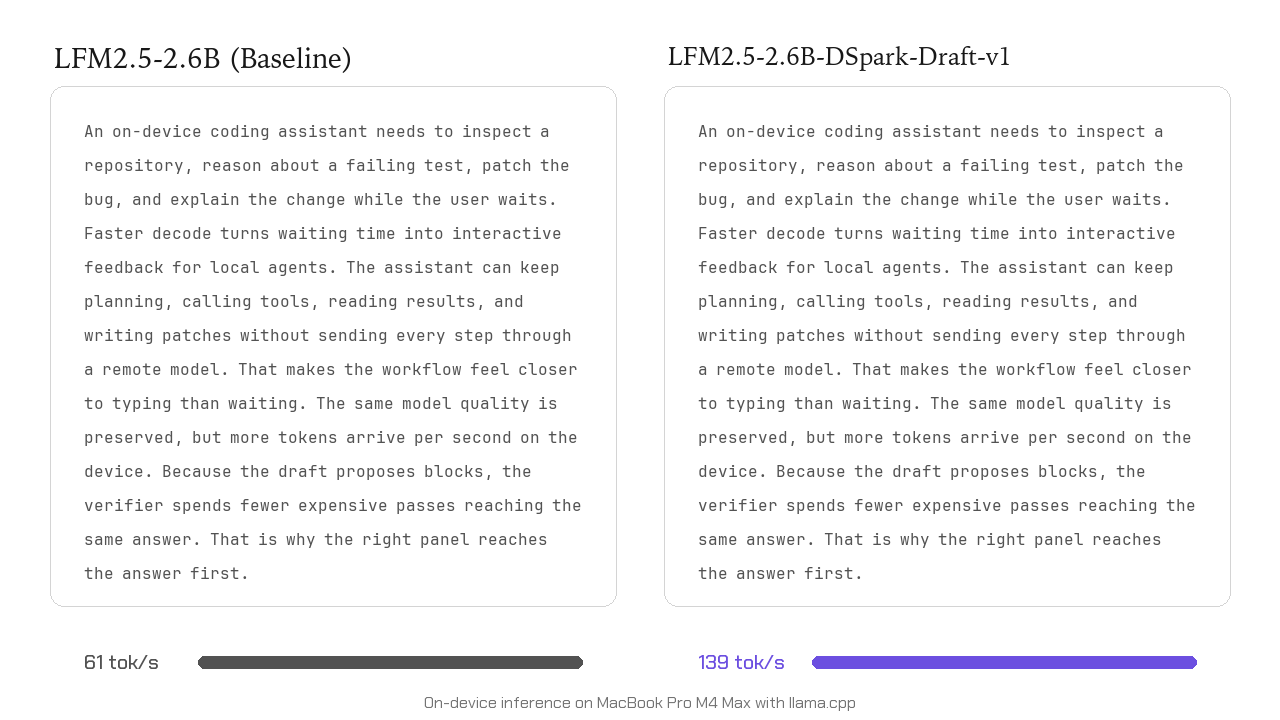
LiquidAI has unveiled LFM2.5-DSpark, a significant update to its Liquid Foundation Model (LFM) series. The announcement, published via the Hugging Face Blog, highlights a major technical milestone: inference speeds that are up to 3.2 times faster than previous iterations. This performance leap is designed to enhance the efficiency of AI deployments, particularly for real-time applications where low latency is a critical requirement. By focusing on inference optimization, LFM2.5-DSpark addresses the growing industry demand for high-throughput AI solutions that can scale effectively within existing computational constraints. This release underscores LiquidAI's commitment to advancing the performance capabilities of foundation models within the Hugging Face ecosystem.
Key Takeaways
- Significant Performance Boost: The LFM2.5-DSpark model achieves up to 3.2x faster inference speeds compared to earlier versions in the series.
- Model Iteration: This release marks the transition to the 2.5 version of Liquid Foundation Models (LFM), indicating rapid development in the architecture.
- Platform Integration: The announcement and associated technical insights are hosted on the Hugging Face Blog, ensuring accessibility for the global AI developer community.
- Efficiency Focus: The "DSpark" designation highlights a specific focus on computational optimization and high-speed execution for foundation models.
In-Depth Analysis
The 3.2x Inference Breakthrough
The primary focus of the LFM2.5-DSpark announcement is the substantial increase in inference speed. In the current landscape of artificial intelligence, inference speed—the time it takes for a model to process an input and generate a response—is often the most significant bottleneck for production-grade applications. A 3.2x speedup represents a transformative shift, allowing for near-instantaneous responses in user-facing applications and significantly higher throughput for batch processing tasks.
While the original announcement focuses on the performance metric, the implications for hardware utilization are profound. Achieving a three-fold increase in speed typically suggests optimizations at the architectural or kernel level. For enterprises, this means that the same hardware infrastructure can now support three times the user load, or conversely, that operational costs can be reduced by utilizing fewer resources to achieve the same performance levels. This focus on efficiency over raw parameter count reflects a maturing AI industry that prioritizes deployability and cost-effectiveness.
Evolution of the Liquid Foundation Model Series
The jump to version 2.5 of the Liquid Foundation Model (LFM) series indicates a focused iteration cycle by LiquidAI. The LFM architecture is known for its distinct approach to modeling data sequences, and the introduction of the "DSpark" variant suggests a specialized optimization layer or a refined processing engine designed to accelerate data flow during the inference phase. By releasing this update through the Hugging Face Blog, LiquidAI leverages a platform that is central to modern AI research and deployment, ensuring that the performance gains are visible to practitioners who are actively looking for optimized alternatives to standard transformer architectures.
Furthermore, the 3.2x metric serves as a competitive benchmark. As the market for foundation models becomes increasingly crowded, performance differentiators like inference speed become critical for adoption. LiquidAI’s ability to deliver such a significant gain in a point-release (v2.5) suggests that there is still considerable room for optimization within the LFM framework, potentially positioning it as a high-efficiency alternative for edge computing and real-time enterprise AI.
The Role of Optimization in Modern AI
The release of LFM2.5-DSpark highlights a broader trend in the AI industry: the shift from training-centric development to inference-centric optimization. For several years, the primary goal of AI research was to build larger models with more parameters. However, as these models move into production, the focus has shifted to how they can be run more efficiently. Optimization techniques, whether they involve quantization, pruning, or architectural refinements like those seen in the DSpark variant, are now at the forefront of AI innovation.
By achieving a 3.2x speedup, LiquidAI is addressing the "last mile" problem of AI—making powerful models practical for everyday use. This is especially important for industries like finance, healthcare, and autonomous systems, where milliseconds of latency can have significant consequences. The LFM2.5-DSpark release demonstrates that architectural innovation can lead to performance gains that are just as impactful as scaling up model size.
Industry Impact
The introduction of LFM2.5-DSpark has several implications for the broader AI industry. First, it sets a new benchmark for inference optimization within the foundation model space. As organizations look to scale their AI capabilities while managing rising cloud computing costs, metrics like "inference-per-second" are becoming the primary KPIs for enterprise AI. A 3.2x improvement is a compelling argument for organizations to consider the LFM architecture for their high-scale needs.
Second, the focus on "Liquid" models suggests a move toward more dynamic and adaptable AI systems. If LFM2.5-DSpark can maintain high accuracy while delivering such significant speed gains, it may encourage other developers to explore non-transformer architectures or specialized optimization techniques. This could lead to a more diverse and efficient ecosystem of foundation models tailored for specific hardware or use cases, moving away from the one-size-fits-all approach that has dominated the industry.
Frequently Asked Questions
What is the main improvement in LFM2.5-DSpark?
The main improvement is a significant increase in inference speed. According to the announcement, LFM2.5-DSpark performs up to 3.2 times faster than previous versions in the Liquid Foundation Model series.
Where can I find the official announcement for LFM2.5-DSpark?
The official announcement and technical details regarding the LFM2.5-DSpark release are hosted on the Hugging Face Blog, authored by the LiquidAI team.
What does the "3.2x faster inference" mean for developers?
For developers, a 3.2x faster inference speed means that applications will have lower latency and can handle more concurrent requests on the same hardware, leading to better user experiences and reduced infrastructure costs.

