
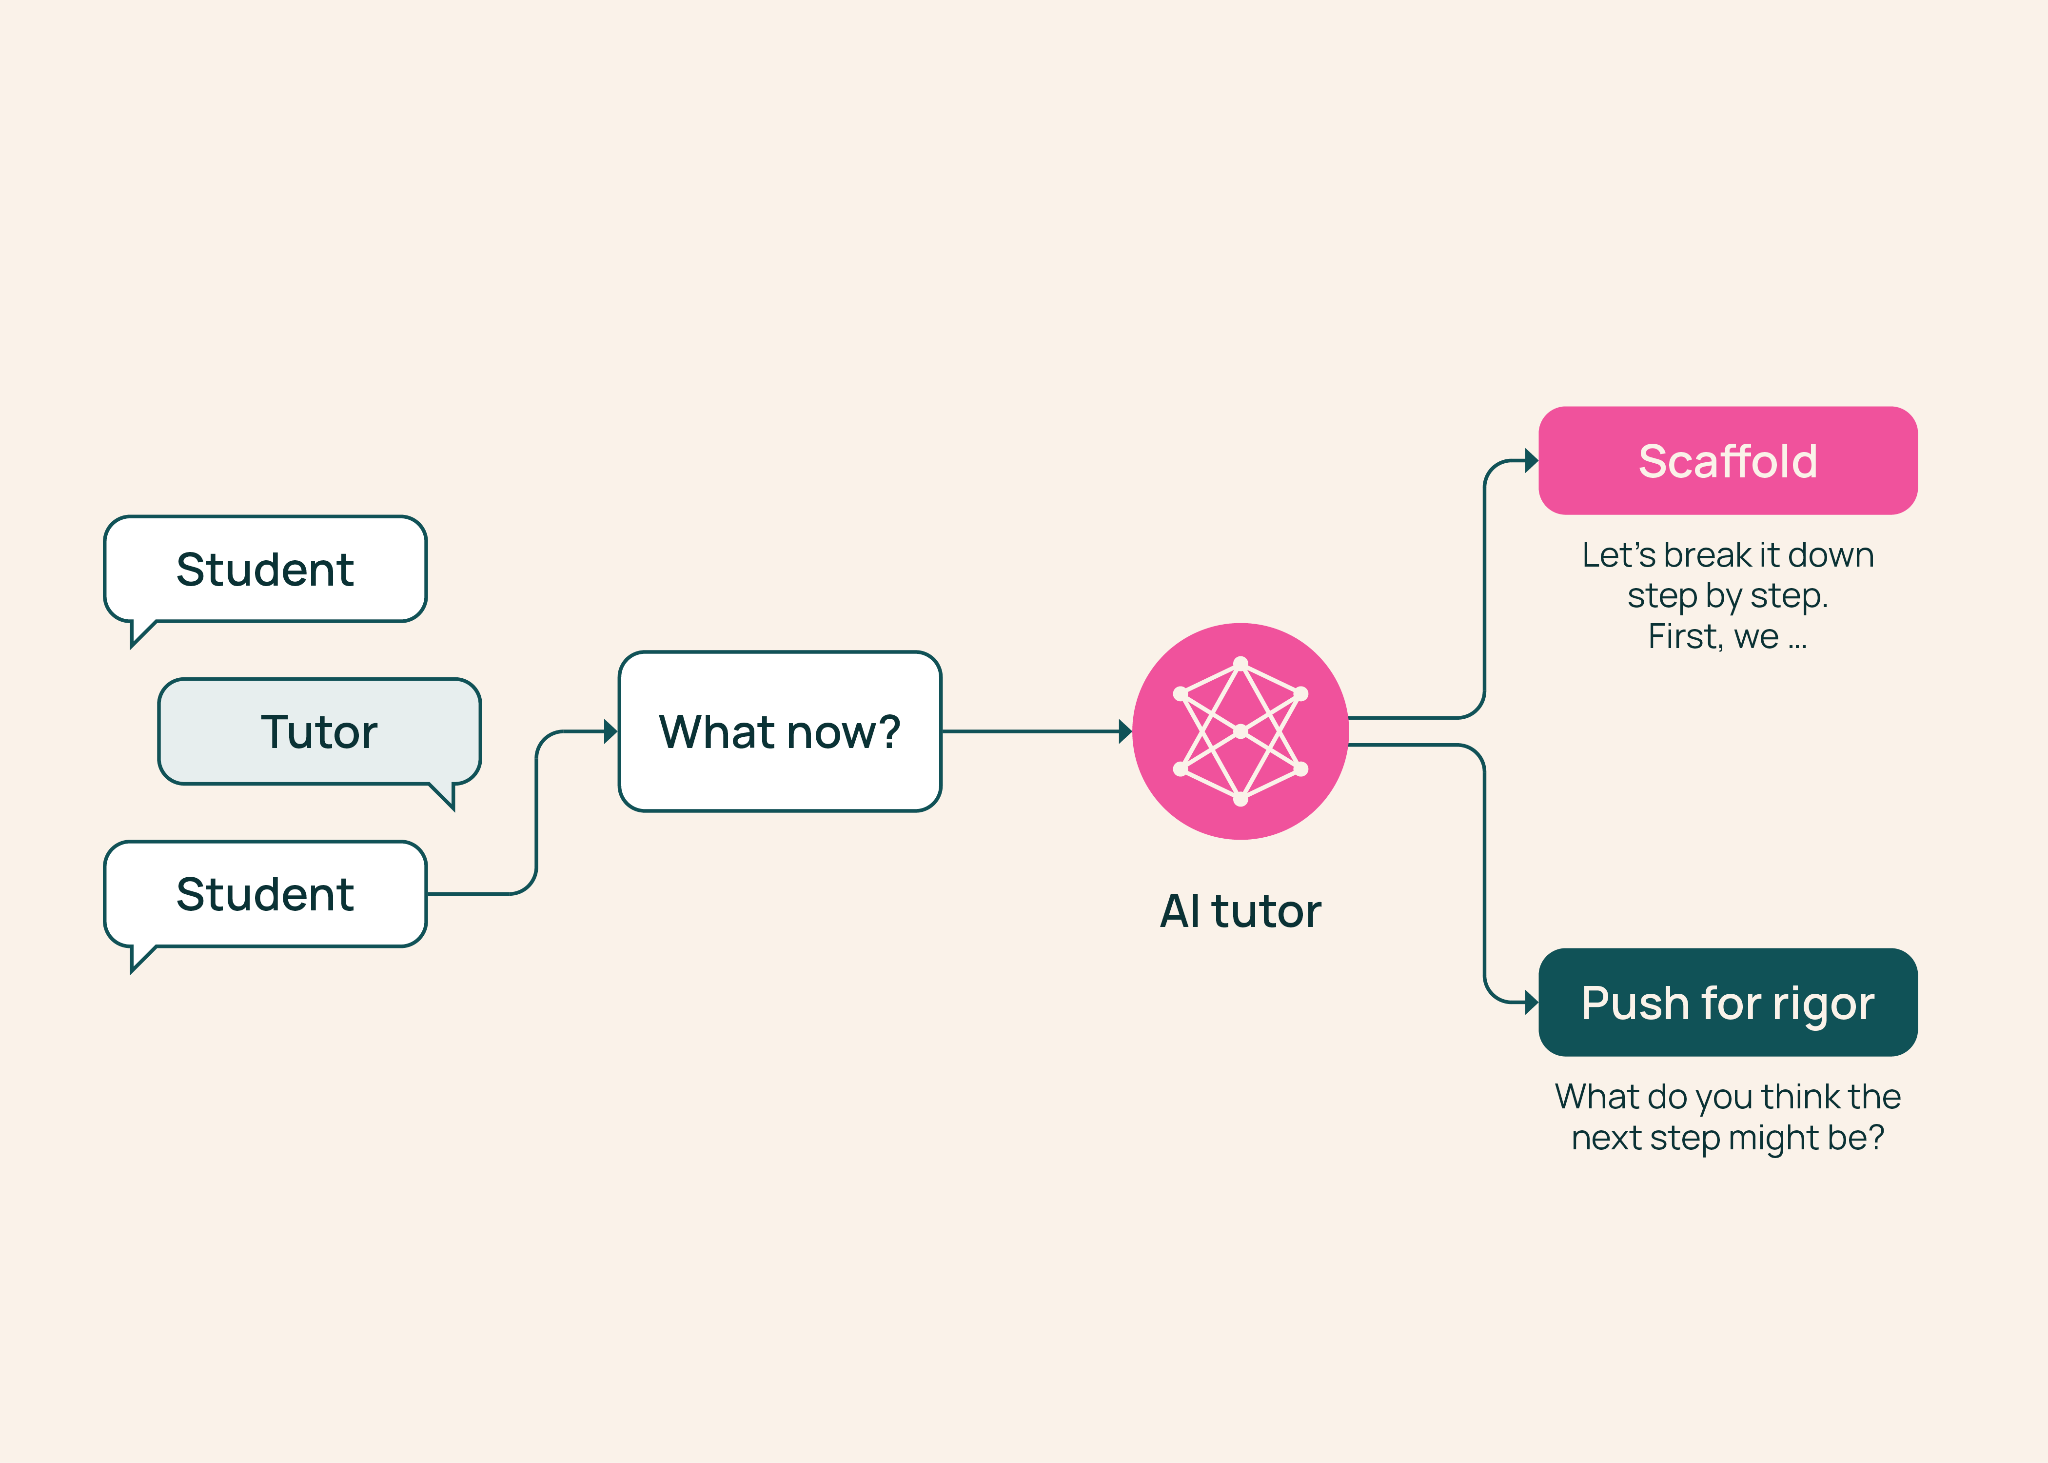
AI Tutoring and the 'TutorMoments' Challenge: When Should AI Help or Hold Back?
The emergence of 'TutorMoments,' a project by the Allen Institute for AI (AllenAI) hosted on Hugging Face, highlights a critical frontier in educational technology: the timing of AI intervention. While modern Large Language Models (LLMs) are optimized for immediate helpfulness, effective pedagogy often requires 'holding back' to allow for productive struggle. This analysis explores the core question posed by the TutorMoments initiative: whether AI tutors can discern the optimal moments to provide assistance versus when to remain silent to foster independent problem-solving. By examining the tension between being a 'helpful assistant' and a 'transformative educator,' we delve into the technical and pedagogical implications of this research for the future of personalized, AI-driven learning environments and the shift toward more sophisticated, Socratic digital tutoring systems.
Key Takeaways
- The Intervention Dilemma: The core challenge for AI tutors is balancing immediate assistance with the pedagogical need for students to work through difficulties independently.
- TutorMoments Framework: Originating from AllenAI and hosted on Hugging Face, this project focuses on identifying the specific 'moments' where a tutor's decision to help or wait is most impactful.
- Beyond Helpfulness: Current AI models are often 'too helpful,' potentially hindering the learning process by providing answers rather than guidance.
- Open Research Significance: The publication of this work on Hugging Face signals a move toward standardized, open-source benchmarks for evaluating the pedagogical intelligence of AI models.
In-Depth Analysis
The Paradox of the Helpful Assistant
The title of the AllenAI project, "TutorMoments: Do AI tutors know when to help and when to hold back?", strikes at the heart of a fundamental conflict in current AI development. Most Large Language Models (LLMs) are fine-tuned using Reinforcement Learning from Human Feedback (RLHF) to be as helpful, harmless, and honest as possible. In a general context, 'helpfulness' equates to providing the most direct and accurate answer to a user's query in the shortest amount of time. However, in an educational setting, this definition of helpfulness is often counterproductive.
Effective tutoring is built on the concept of 'scaffolding'—providing just enough support to allow a student to complete a task they could not do alone, and then gradually removing that support. If an AI tutor identifies a student's struggle and immediately provides the solution, it robs the student of the 'productive struggle' necessary for long-term retention and cognitive development. The TutorMoments initiative suggests that the next generation of AI tutors must be trained not just to know the answer, but to understand the student's cognitive state and determine if an intervention will facilitate learning or merely complete the task for them.
Defining and Identifying 'Tutor Moments'
The concept of a 'Tutor Moment' refers to a critical juncture in the learning process where a tutor must make a strategic choice. These moments are often subtle. For instance, if a student makes a syntax error in a coding exercise, should the AI immediately point it out, or should it wait to see if the student catches it during a test run? If a student is stuck on a math problem, should the AI provide a hint about the next step, or ask a leading question about the previous one?
By framing the research around these specific moments, AllenAI is likely looking at the temporal and contextual data that informs a human tutor's intuition. This involves analyzing student behavior patterns, the frequency of errors, and the 'latency' of student responses. The challenge for AI is to replicate this intuition through data-driven models. The 'TutorMoments' project on Hugging Face likely serves as a repository or a benchmark to test whether models can correctly classify these moments and choose the pedagogically sound action over the most 'helpful' one.
The Technical Challenge of 'Holding Back'
Teaching an AI to 'hold back' is technically more complex than teaching it to provide answers. It requires the model to have a theory of mind regarding the learner's knowledge gap. The AI must evaluate the 'Zone of Proximal Development' (ZPD)—the difference between what a learner can do without help and what they can do with help.
To achieve this, researchers must move beyond standard prompt engineering. It requires specialized datasets where the 'ground truth' isn't the correct answer to a math problem, but the correct instructional move. This might involve training models on transcripts of expert human tutors who intentionally withhold information to prompt student reflection. The inclusion of this project on the Hugging Face Blog suggests that the community is beginning to prioritize these nuanced instructional behaviors as a distinct metric of AI capability, moving away from simple accuracy scores on standardized tests.
Industry Impact
The implications of the TutorMoments research for the AI industry, particularly the EdTech sector, are profound. Currently, many AI tutoring tools act as sophisticated 'answer engines.' If the industry shifts toward models that understand the nuances of intervention timing, we will see a transition from 'AI Assistants' to 'AI Mentors.'
For companies developing educational products, this research provides a roadmap for creating more effective learning tools that can actually improve learning outcomes rather than just helping students finish homework faster. Furthermore, by hosting this on Hugging Face, AllenAI is encouraging a standardized approach to 'Pedagogical AI,' which could lead to the development of specialized LLMs designed specifically for teaching, characterized by their ability to guide, hint, and wait, rather than just respond.
Frequently Asked Questions
Question: What is the main goal of the TutorMoments project?
The main goal is to investigate and improve the ability of AI tutors to determine the correct timing for interventions—specifically, knowing when to provide a student with help and when to allow them to work through a problem independently to enhance learning.
Question: Why is 'holding back' considered a skill for an AI tutor?
In pedagogy, 'holding back' allows for productive struggle, which is essential for deep learning. If an AI provides answers too quickly, the student may become dependent on the tool and fail to develop their own problem-solving skills. 'Holding back' is a sign of a sophisticated understanding of the learning process.
Question: How does this research differ from standard AI development?
Standard AI development usually focuses on maximizing the accuracy and speed of an answer. This research focuses on the process of interaction, prioritizing the long-term educational benefit of the user over the immediate completion of a task.

