Accelerating Gemini Nano Models on Pixel Devices via Frozen Multi-Token Prediction Techniques
Google Research has announced a technical breakthrough in the efficiency of on-device AI, specifically focusing on the acceleration of Gemini Nano models on Pixel hardware. By leveraging a method known as 'frozen Multi-Token Prediction' (MTP), researchers have optimized how these compact large language models process information. This development, categorized under Machine Intelligence, represents a significant step forward in making high-performance AI more accessible and responsive on mobile devices. The approach focuses on increasing inference speed without compromising the model's core architecture, ensuring that Pixel users can benefit from faster, more efficient AI-driven features directly on their hardware.
Key Takeaways
- Enhanced Performance: Google Research has successfully accelerated Gemini Nano models specifically for the Pixel device ecosystem.
- Technical Innovation: The acceleration is achieved through the implementation of 'frozen Multi-Token Prediction' (MTP).
- On-Device Focus: This breakthrough emphasizes Google's commitment to improving Machine Intelligence directly on mobile hardware.
- Efficiency Gains: The method focuses on optimizing inference speed, allowing for more responsive AI interactions on-device.
In-Depth Analysis
The Evolution of Gemini Nano on Pixel Hardware
The recent announcement from Google Research highlights a pivotal shift in how Machine Intelligence is deployed on consumer hardware. Gemini Nano, designed as the most efficient version of Google's Gemini model family for on-device tasks, has undergone a significant performance upgrade. By focusing on the Pixel series, Google is tightening the integration between its custom silicon and its most advanced compact models. This acceleration is not merely a software patch but a fundamental optimization of how the model interacts with the device's processing units.
The focus on Gemini Nano underscores the industry's move toward decentralized AI. By running models locally on Pixel devices, users benefit from increased privacy, reduced latency, and offline functionality. The challenge has always been the computational constraints of mobile processors compared to cloud-based TPUs. The latest research indicates that these constraints are being systematically addressed through architectural refinements that allow the model to run faster while maintaining the high standards of output expected from the Gemini suite.
Understanding Frozen Multi-Token Prediction
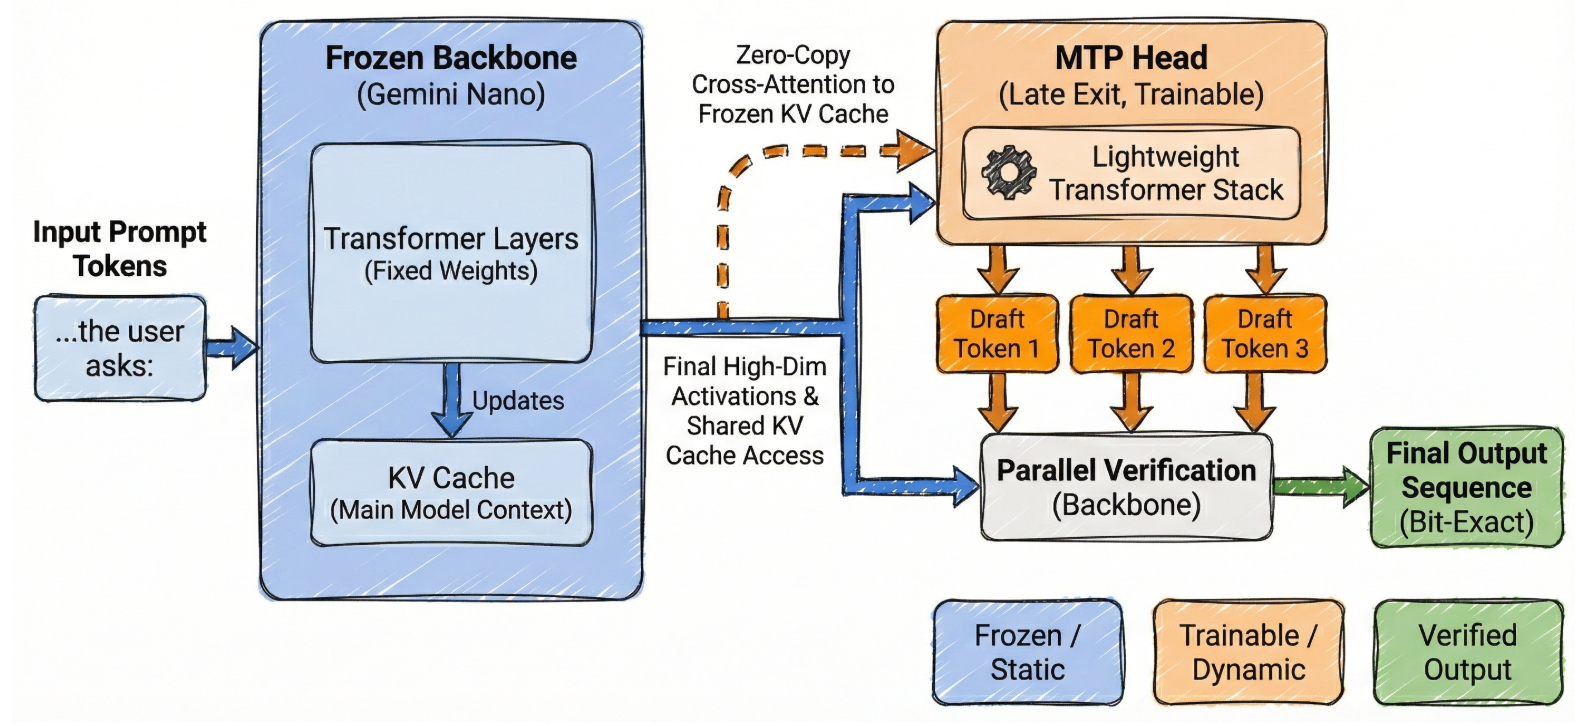
At the heart of this acceleration is the concept of 'frozen Multi-Token Prediction.' In traditional autoregressive language models, tokens are generated one by one, which can be a bottleneck for performance on mobile devices. Multi-Token Prediction (MTP) changes this paradigm by allowing the model to predict multiple future tokens simultaneously during a single inference step. This effectively increases the throughput of the model, leading to faster text generation and more fluid user experiences.
The 'frozen' aspect of this implementation is particularly noteworthy. In the context of Machine Intelligence research, 'frozen' typically refers to keeping certain layers or parameters of a model static during a specific optimization or fine-tuning process. By applying MTP in a 'frozen' state, Google Research appears to be enhancing the model's speed without requiring a complete overhaul of the base Gemini Nano weights. This allows for a more stable deployment and ensures that the core logic and safety guardrails of the original model remain intact while the delivery mechanism is streamlined for the Pixel's hardware architecture.
Industry Impact
Setting a New Standard for Mobile AI
The acceleration of Gemini Nano using frozen Multi-Token Prediction sets a new benchmark for the mobile industry. As AI becomes a central selling point for smartphones, the ability to run sophisticated models locally with high velocity is a major competitive advantage. This development suggests that the gap between cloud-based AI performance and on-device capabilities is narrowing, potentially leading to a future where complex reasoning and generative tasks are handled entirely on the user's handset.
Implications for the Machine Intelligence Ecosystem
For the broader AI research community, Google's success with frozen MTP provides a roadmap for optimizing large language models (LLMs) for edge computing. It demonstrates that architectural efficiency can be achieved through clever prediction strategies rather than just increasing raw compute power. This could lead to a surge in research into multi-token architectures and 'frozen' optimization techniques across the industry, as developers seek to bring the power of Machine Intelligence to a wider array of low-power devices beyond just flagship smartphones.
Frequently Asked Questions
Question: What is Gemini Nano?
Gemini Nano is the most efficient version of Google's Gemini family of large language models, specifically optimized for running locally on devices like the Pixel smartphone to handle on-device AI tasks with high privacy and low latency.
Question: How does Multi-Token Prediction (MTP) speed up AI?
Multi-Token Prediction allows an AI model to predict and generate multiple words or tokens at the same time, rather than one by one. This reduces the number of processing cycles required to generate a response, leading to significantly faster performance.
Question: Why is the 'frozen' aspect of this research important?
The 'frozen' designation implies that the core parameters of the model remain unchanged during this optimization. This ensures that the model's established intelligence and safety features are preserved while the system is tuned for better speed and efficiency on specific hardware like the Pixel.