
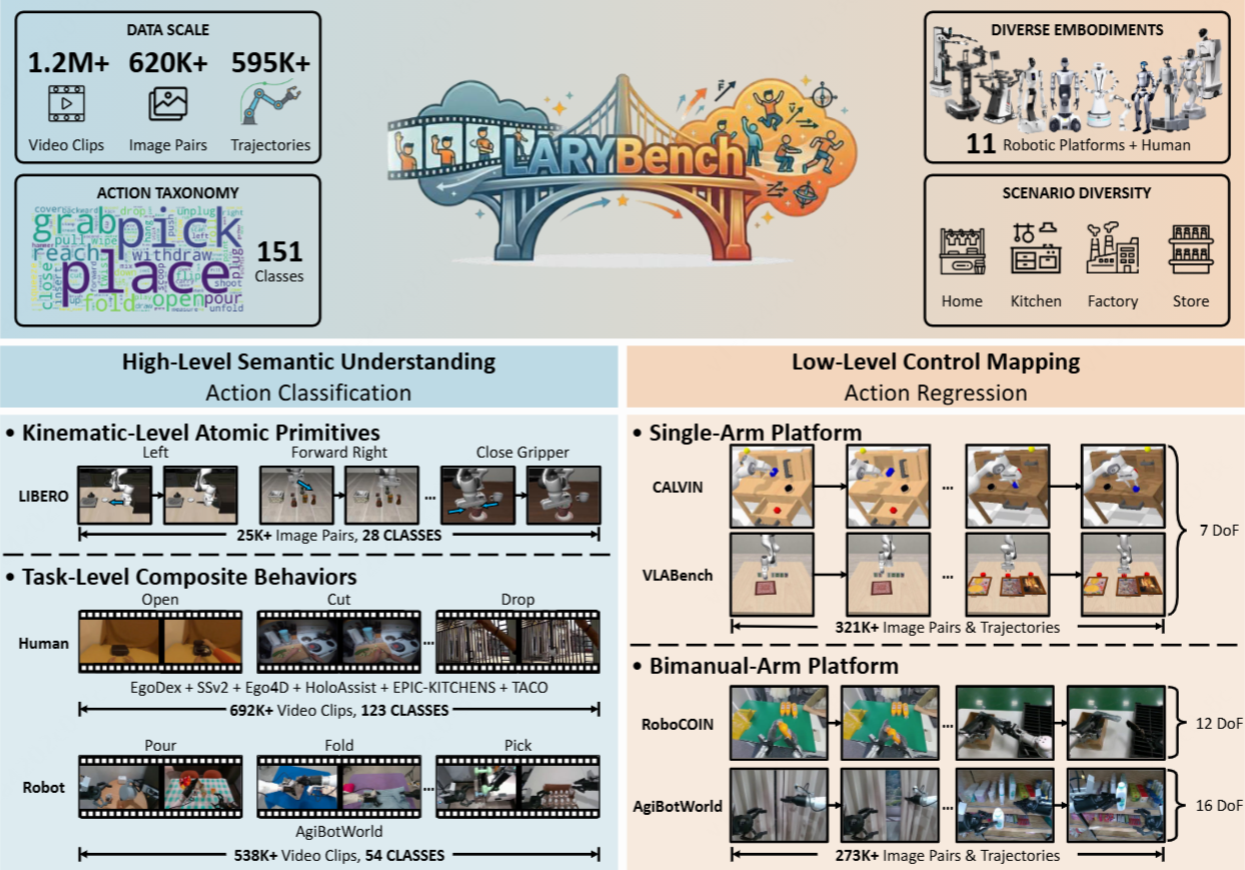
Meituan Technical Team Unveils LARYBench: A New Systematic Benchmark for Latent Action Representation in Embodied AI
The Meituan Technical Team has introduced LARYBench (Latent Action Representation Yielding Benchmark), a comprehensive system designed to evaluate and guide the learning of general latent action representations from large-scale visual data. This benchmark marks a significant milestone in embodied AI by establishing a standardized metric, often compared to an "ImageNet" for action representation. The experimental findings released alongside the benchmark reveal that general-purpose vision models significantly outperform specialized embodied AI expert models in both action generalization and control precision. Most notably, the research confirms that embodied action representations can emerge naturally from large-scale human video data, suggesting that specialized robotic datasets may not be the only path toward achieving sophisticated robotic control.
Key Takeaways
- Introduction of LARYBench: A systematic evaluation benchmark designed to facilitate the learning of general latent action representations from massive visual datasets.
- Superiority of General Models: Experimental results indicate that general vision models exceed the performance of specialized embodied AI action expert models in generalization and precision.
- Emergence from Human Data: The benchmark demonstrates that embodied action representations can successfully emerge from large-scale human video data.
- Standardizing Action Representation: LARYBench aims to serve as the "ImageNet" for the field of embodied action, providing a first-of-its-kind measurement for learning from human videos.
In-Depth Analysis
The Framework of LARYBench
LARYBench, which stands for Latent Action Representation Yielding Benchmark, has been developed by the Meituan Technical Team to address a critical gap in the development of embodied AI. The system is designed to provide a systematic evaluation of how well models can learn latent action representations—the underlying mathematical descriptions of movement—from vast amounts of visual information. By creating a structured environment for measurement, LARYBench allows researchers to quantify the effectiveness of different modeling approaches in a way that was previously unstandardized. This benchmark acts as a guiding framework, steering the industry toward the creation of more versatile and capable embodied agents that can interpret visual cues into actionable movements.
General Vision Models vs. Specialized Experts
One of the most significant findings presented by the Meituan Technical Team is the performance gap between general vision models and specialized embodied AI action expert models. Traditionally, the industry has leaned toward developing "expert" models specifically trained for robotic tasks. However, LARYBench's experimental data shows that general vision models—those trained on broader, non-specific visual data—actually exhibit superior capabilities in two critical areas: action generalization and control precision.
Action generalization refers to the model's ability to apply learned movements to new, unseen scenarios, while control precision relates to the accuracy of the executed actions. The fact that general models outperform specialized ones suggests that the broad features learned by general-purpose vision systems provide a more robust foundation for embodied intelligence than the narrow focus of current expert models. This shift in performance metrics could redefine how researchers prioritize model training and architecture design in the future.
Learning from Human Video Data
Perhaps the most transformative aspect of the LARYBench release is the evidence that embodied action representations can emerge from large-scale human video data. Historically, training embodied AI often required labor-intensive, robot-specific datasets or simulated environments. The findings from LARYBench suggest that the sheer scale and variety of human actions captured in standard video data contain sufficient information for a model to derive generalizable action representations. This "emergence" of action capability from human-centric data provides a scalable pathway for training robots, as it leverages the nearly infinite supply of human video content available globally. It bridges the gap between passive observation and active execution, proving that a model can learn the "how" of movement by watching humans interact with the world.
Industry Impact
The introduction of LARYBench is poised to have a profound impact on the AI and robotics industries. By defining a "ImageNet" for embodied action, Meituan has provided the community with a common yardstick to measure progress. This standardization is likely to accelerate the development of general-purpose robots that can function in diverse environments.
Furthermore, the discovery that general vision models and human video data are highly effective for learning action representations lowers the barrier to entry for developing sophisticated embodied AI. Companies and researchers may no longer need to rely solely on expensive, specialized robotic hardware for data collection, instead utilizing existing video repositories to train the next generation of AI agents. This could lead to a rapid expansion in the versatility of embodied AI, moving it from controlled laboratory settings into more complex, real-world applications such as logistics, service industries, and domestic assistance.
Frequently Asked Questions
Question: What is the primary purpose of LARYBench?
LARYBench is a systematic evaluation benchmark created to guide and measure the learning of general latent action representations from large-scale visual data, serving as a standard for the embodied AI field.
Question: Why are general vision models performing better than specialized expert models?
According to the LARYBench results, general vision models show significantly better performance in action generalization and control precision, suggesting that broad visual training provides a more adaptable and precise foundation for movement than narrow, task-specific training.
Question: Can robots learn to move just by watching videos of humans?
The research associated with LARYBench indicates that embodied action representations can indeed emerge from large-scale human video data, allowing models to learn generalized movement patterns from human observation.

