Meituan LongCat Team Unveils WBench: The First Systematic Multi-Round Benchmark for Interactive Video World Models
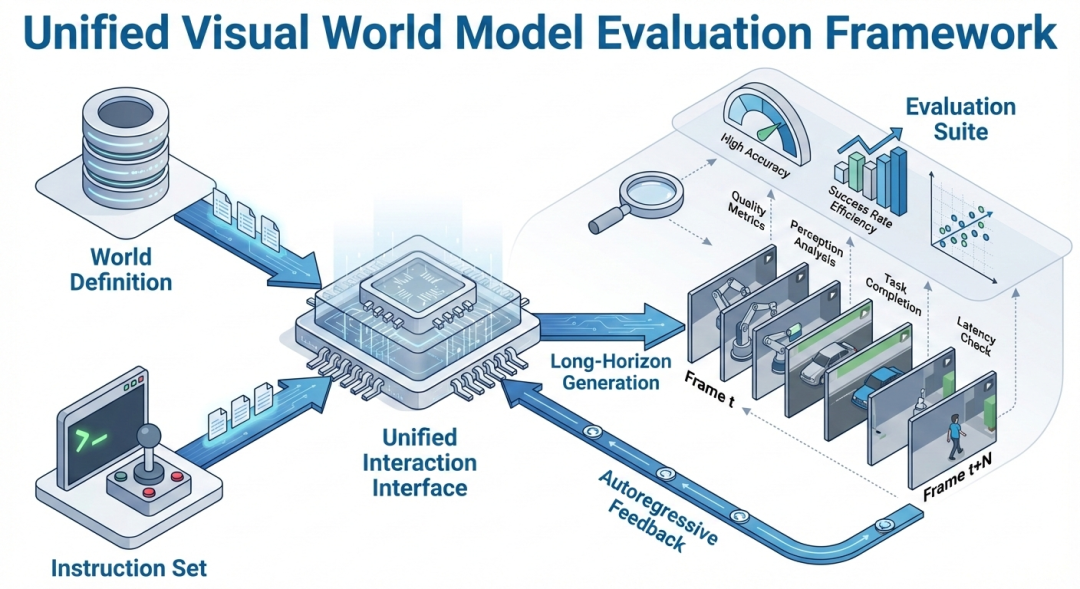
The Meituan LongCat team has announced the open-sourcing of WBench, a groundbreaking evaluation framework designed to measure the performance of interactive video world models. As the first systematic multi-round benchmark in this field, WBench serves as a diagnostic tool—likened to a 'CT scanner'—to identify the technical bottlenecks encountered when AI transitions from passive video generation to active, multi-turn interaction. By testing models across diverse scenarios ranging from lunar environments to futuristic urban settings, WBench aims to define the current boundaries of world models and provide a clear roadmap for future development in interactive artificial intelligence.
Key Takeaways
- Introduction of WBench: Meituan's LongCat team has developed and open-sourced WBench, the first systematic benchmark for evaluating interactive video world models.
- Focus on Interaction: Unlike previous benchmarks that focus on passive viewing, WBench evaluates the model's ability to handle active, multi-round interactions.
- Diagnostic Capabilities: The tool is described as a 'CT scanner' for AI, capable of precisely locating where models fail during the transition from observation to interaction.
- Open-Source Contribution: By making WBench public, the Meituan LongCat team provides the industry with a standardized method to measure the boundaries of world model capabilities.
In-Depth Analysis
Bridging the Gap Between Observation and Interaction
The development of world models has traditionally focused on the generation of realistic video content, often resulting in systems that are excellent at 'passive viewing' but struggle when required to engage in 'active interaction.' The Meituan LongCat team identifies this transition as a critical frontier in AI research. WBench is specifically engineered to address this gap. By implementing a systematic multi-round evaluation process, the benchmark tests how a model maintains consistency, logic, and responsiveness over several layers of interaction. This shift is essential for moving toward AI that can not only depict a world but also function within it dynamically.
The 'CT Scanner' Approach to AI Evaluation
One of the most significant aspects of WBench is its diagnostic nature. The LongCat team utilizes the metaphor of a 'CT scanner' to describe the benchmark's functionality. In the context of complex world models—which may involve intricate physics, spatial reasoning, and temporal consistency—identifying the exact point of failure is often difficult. WBench provides the granularity needed to pinpoint these 'stuck' points. Whether the model fails in maintaining environmental persistence during a 'moonwalk' scenario or loses architectural coherence in a 'cyber city' setting, WBench offers a structured way to visualize and analyze these limitations. This precision allows developers to move beyond general performance metrics and focus on specific algorithmic improvements.
Defining the Boundaries of Simulated Worlds
The scope of WBench is broad, covering a variety of simulated environments to ensure a comprehensive evaluation. The mention of scenarios ranging from 'moonwalks' to 'cyber cities' suggests that the benchmark tests models against both low-gravity physical simulations and complex, high-density urban environments. By testing the boundaries of these world models, WBench establishes a baseline for what current technology can achieve and highlights the remaining hurdles in creating truly interactive, high-fidelity digital universes. This systematic approach ensures that as world models evolve, their progress can be measured against a consistent and rigorous set of interactive standards.
Industry Impact
The release of WBench by the Meituan LongCat team is poised to have a significant impact on the AI research community. By providing the first systematic multi-round evaluation benchmark, Meituan is filling a critical void in the current AI ecosystem. Standardized evaluation is often a precursor to rapid innovation; just as ImageNet accelerated computer vision, WBench could accelerate the development of interactive world models by providing a common language for performance. Furthermore, the decision to open-source the tool encourages collaborative improvement and transparency, allowing researchers worldwide to test their models against the same 'CT scanner' and collectively push the boundaries of what interactive AI can achieve.
Frequently Asked Questions
Question: What makes WBench different from existing video evaluation benchmarks?
Unlike traditional benchmarks that primarily evaluate the visual quality or coherence of a single generated video (passive viewing), WBench is the first to systematically measure multi-round interactions. It focuses on how a model responds to active inputs over time, making it a unique tool for evaluating 'interactive' world models.
Question: Why does the Meituan LongCat team refer to WBench as a 'CT scanner'?
The term 'CT scanner' is used to highlight the benchmark's ability to perform a deep, diagnostic analysis of a model. It doesn't just give a pass/fail grade; it identifies the specific technical areas where a world model 'gets stuck' or fails to maintain interaction logic, allowing for more targeted research and development.
Question: Is WBench available for public use?
Yes, the Meituan LongCat team has open-sourced WBench, making it available for the global AI research community to use, evaluate, and build upon to advance the field of interactive world models.