
Meituan Technical Team Explores New Generation BI Architecture via Metric Platforms and Enhanced Computing Engines
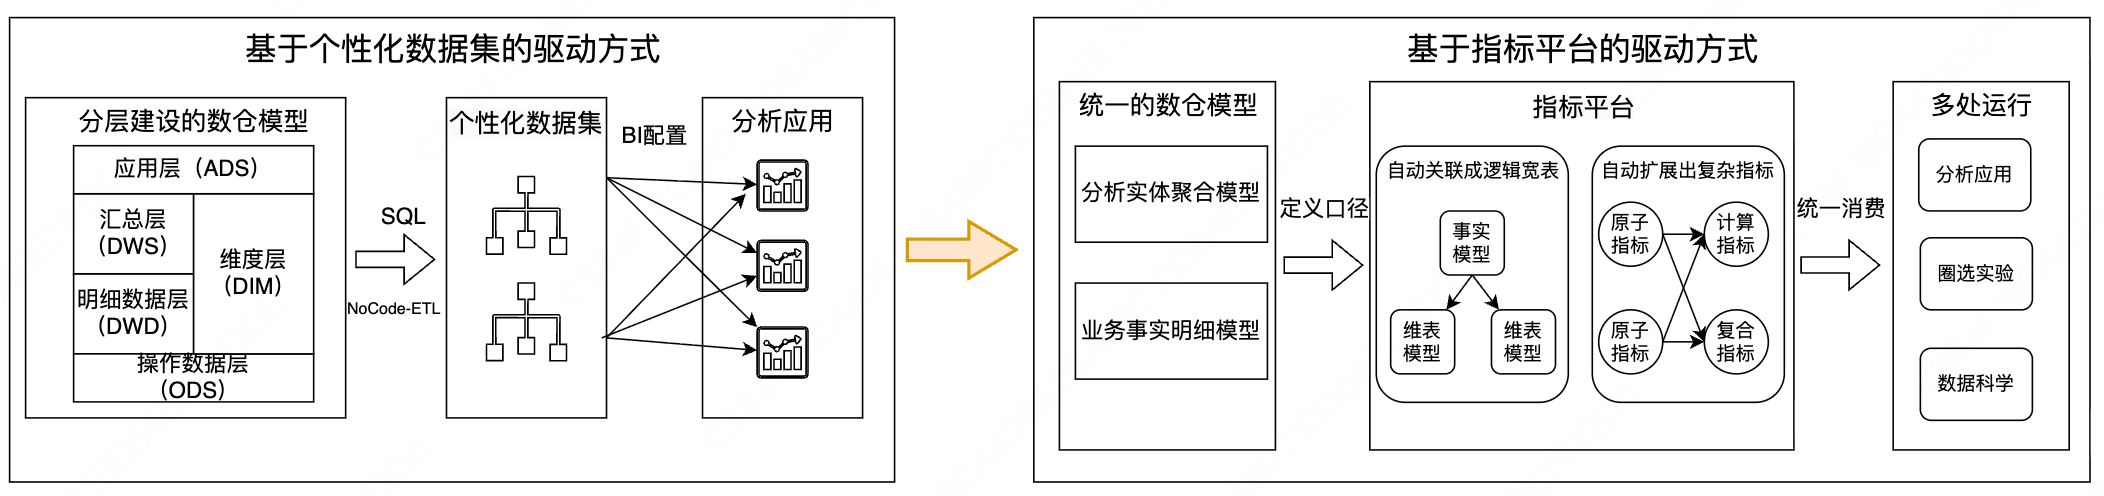
Meituan's data platform team has unveiled a transformative approach to Business Intelligence (BI) by constructing a new generation architecture centered on a unified Metric Platform. This initiative specifically targets the systemic failures of traditional BI frameworks, which often suffer from inconsistent data definitions—referred to as data caliber confusion—and degraded query performance when handling diverse, personalized datasets. By implementing two core technical pillars, "Automatic Semantics" and "Enhanced Computing," Meituan has successfully streamlined its data operations. This shift ensures that business logic is centralized and computational efficiency is maximized, providing a robust foundation for high-concurrency and high-precision data analysis across the organization's expansive ecosystem.
Key Takeaways
- Metric-Centric Evolution: Meituan has transitioned from traditional dataset-driven BI to a centralized Metric Platform architecture to ensure a single source of truth.
- Solving Data Inconsistency: The implementation of "Automatic Semantics" directly addresses the issue of "data caliber confusion" caused by fragmented, personalized datasets.
- Performance Optimization: Through "Enhanced Computing" capabilities, Meituan has mitigated the poor query performance typically associated with complex BI environments.
- Architectural Innovation: The new system balances the need for personalized data exploration with the necessity of standardized organizational metrics.
In-Depth Analysis
The Transition to a Metric-Centric BI Framework
Traditional Business Intelligence environments have long been plagued by the proliferation of personalized datasets. In such legacy systems, different departments or individual analysts often create their own data subsets, leading to a phenomenon Meituan identifies as "data caliber confusion." This occurs when the same metric—such as "daily active users" or "gross merchandise value"—is calculated using slightly different logic across various reports, resulting in conflicting insights that undermine executive decision-making.
Meituan’s solution involves the construction of a next-generation BI architecture that places a "Metric Platform" at its core. By decoupling the metric definition from the visualization layer, Meituan ensures that business logic is defined once and reused everywhere. This centralized approach allows the data platform to maintain strict control over data semantics, ensuring that every user, regardless of their specific business unit, is pulling from the same standardized definitions. This structural shift represents a move toward the "Headless BI" or "Metric Layer" trend currently gaining traction in the global data engineering community.
Overcoming Performance Barriers with Automatic Semantics and Enhanced Computing
Beyond data consistency, Meituan's exploration focuses heavily on the technical bottlenecks of query execution. Traditional BI platforms often struggle with performance as the volume of data and the complexity of joins increase, especially when users are allowed to drive analysis through highly customized datasets. Meituan addresses this through two primary technical innovations: Automatic Semantics and Enhanced Computing.
Automatic Semantics functions as a bridge between raw data structures and business-level questions. It allows the system to understand the relationship between different data entities automatically, reducing the manual overhead required to prepare data for analysis. This capability ensures that even as the underlying data schema evolves, the metric definitions remain stable and accessible.
Complementing this is Enhanced Computing, a suite of optimization techniques designed to accelerate the analysis engine. In a high-concurrency environment like Meituan's, where thousands of queries may be executed simultaneously, standard SQL engines often hit a ceiling. Enhanced Computing likely involves advanced caching strategies, materialized view management, or optimized execution plans tailored specifically for metric-based queries. By focusing on these two areas, Meituan has partially resolved the performance degradation that typically occurs when BI tools are scaled across a large enterprise with diverse data needs.
Industry Impact
Meituan's practice serves as a significant case study for the broader technology industry, particularly for large-scale internet companies dealing with massive data volumes. The shift toward a Metric Platform highlights a growing recognition that the "democratization of data" must be balanced with "governance of logic."
By solving the problem of data caliber confusion, Meituan demonstrates how organizations can reduce the operational cost of data reconciliation. Furthermore, the emphasis on analysis engines and enhanced computing underscores the industry's move toward real-time or near-real-time BI. As more companies look to move away from rigid, siloed reporting toward flexible, high-performance analytical frameworks, Meituan’s dual focus on semantics and computation provides a clear roadmap for building scalable data infrastructure.
Frequently Asked Questions
Question: What is the primary cause of "data caliber confusion" in traditional BI?
In traditional BI, data caliber confusion typically arises from the use of personalized, fragmented datasets. When different users define their own logic for metrics within isolated reports or datasets, it leads to inconsistent results for the same business indicators across the organization.
Question: How does Meituan's Metric Platform improve query performance?
Meituan improves performance through "Enhanced Computing" capabilities within its analysis engine. This involves optimizing how data is processed and retrieved, specifically addressing the inefficiencies that occur when traditional BI tools attempt to process complex, personalized data queries at scale.
Question: What role does "Automatic Semantics" play in the new architecture?
Automatic Semantics acts as a core capability that helps the system understand and manage the relationships between data points automatically. This ensures that the semantic meaning of metrics remains consistent and reduces the manual effort needed to maintain data definitions as business requirements change.

