
Meituan Unveils LongCat-AudioDiT: Advancing Zero-Shot Voice Cloning via Waveform Latent Space Diffusion
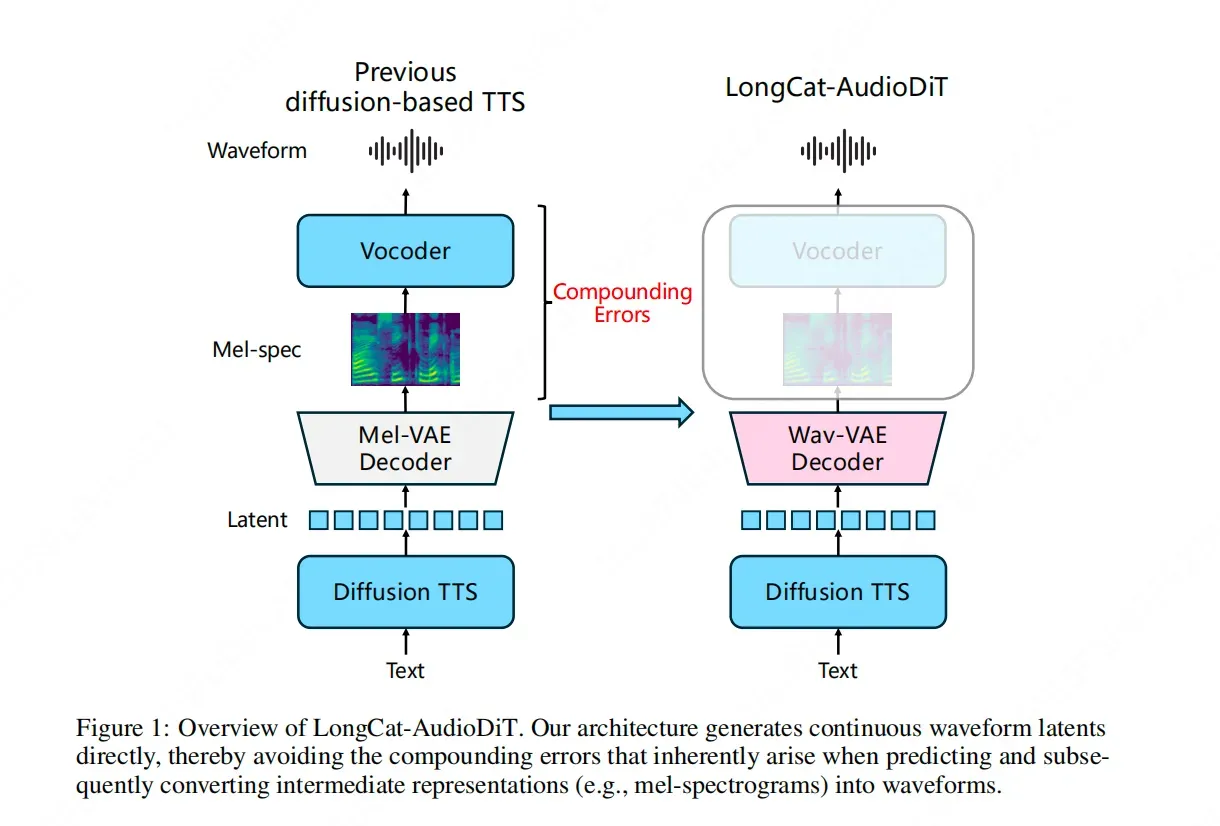
Meituan's LongCat team has officially released LongCat-AudioDiT, a pioneering model designed to push the boundaries of zero-shot Text-to-Speech (TTS) voice cloning. By fundamentally changing the architecture of audio synthesis, the model abandons traditional intermediate representations such as Mel-spectrograms. Instead, it utilizes a Diffusion Transformer (DiT) framework to operate directly within the waveform latent space. This strategic shift allows the AI to learn the inherent laws of sound directly from the source, effectively eliminating cascade errors typically introduced during data conversion processes. LongCat-AudioDiT represents a significant technical leap in achieving high-fidelity voice cloning without the need for intermediate processing steps, streamlining the path from text to authentic human-like audio.
Key Takeaways
- Elimination of Intermediate Steps: LongCat-AudioDiT removes the need for Mel-spectrograms, which have traditionally served as a bridge in TTS systems.
- Direct Waveform Latent Space: The model operates directly within the waveform latent space to capture the fundamental characteristics of sound.
- Diffusion Transformer (DiT) Architecture: It leverages a diffusion-based model to generate high-quality audio outputs.
- Reduction of Cascade Errors: By bypassing data conversion stages, the system prevents the accumulation of errors that often degrade voice quality.
- Zero-Shot Capability: The architecture is specifically optimized to enhance the limits of zero-shot voice cloning performance.
In-Depth Analysis
Breaking the Mel-Spectrogram Bottleneck
In traditional Text-to-Speech (TTS) architectures, the process of generating a voice is often divided into multiple stages. Typically, a model first converts text into an intermediate representation, most commonly a Mel-spectrogram, which is then processed by a vocoder to produce the final waveform. While effective, this multi-step approach introduces "cascade errors"—small inaccuracies in the first stage that are amplified during the second stage.
Meituan's LongCat team identified this as a primary technical bottleneck for high-fidelity voice cloning. With the introduction of LongCat-AudioDiT, the team has moved toward a more integrated approach. By abandoning Mel-spectrograms entirely, the model interacts with the waveform latent space. This allows the AI to learn the underlying patterns and "laws" of sound directly, ensuring that the nuances of a specific voice are preserved without being lost in translation between different data formats.
The Power of Diffusion in Waveform Latent Space
The core of LongCat-AudioDiT lies in its use of the Diffusion Transformer (DiT) architecture. Diffusion models have recently revolutionized image generation, and Meituan is applying this logic to the complexities of human speech. By operating in the latent space of the waveform, the model can iteratively refine audio signals from noise, guided by the input text and the target voice's characteristics.
This method is particularly potent for zero-shot voice cloning, where the model must replicate a voice it has never encountered during training based on a very short sample. Because LongCat-AudioDiT learns the direct relationship between text and sound waves, it can more accurately reconstruct the unique timbre and prosody of a speaker. The removal of intermediate representations means the model is not restricted by the resolution or frequency limitations inherent in Mel-spectrograms, leading to a more authentic and seamless voice reproduction.
Industry Impact
The release of LongCat-AudioDiT marks a significant shift in the AI audio synthesis industry. By demonstrating that intermediate representations are not only unnecessary but potentially detrimental to voice quality, Meituan is setting a new standard for TTS development.
For the broader AI industry, this move toward "direct learning" of sound laws suggests a future where voice cloning becomes more efficient and less prone to the mechanical artifacts often heard in synthetic speech. As zero-shot capabilities improve, the barriers to creating personalized AI assistants, high-quality dubbing, and realistic digital humans continue to lower. LongCat-AudioDiT provides a blueprint for reducing system complexity while simultaneously increasing the fidelity of the output, a dual-benefit that is highly sought after in commercial AI applications.
Frequently Asked Questions
Question: What makes LongCat-AudioDiT different from traditional TTS models?
Traditional models usually convert text to a Mel-spectrogram before generating sound. LongCat-AudioDiT skips this intermediate step and works directly in the waveform latent space using a diffusion model to avoid data conversion errors.
Question: How does this model improve zero-shot voice cloning?
By learning the laws of sound directly and eliminating the cascade errors associated with multi-stage data conversion, the model can more accurately replicate a speaker's unique voice profile from a limited sample without prior training on that specific voice.
Question: What is the benefit of using a Diffusion Transformer (DiT) in this context?
The DiT architecture allows the model to generate high-quality audio by refining noise into clear speech within the latent space, providing a robust framework for handling the complex nuances of human vocal patterns.