
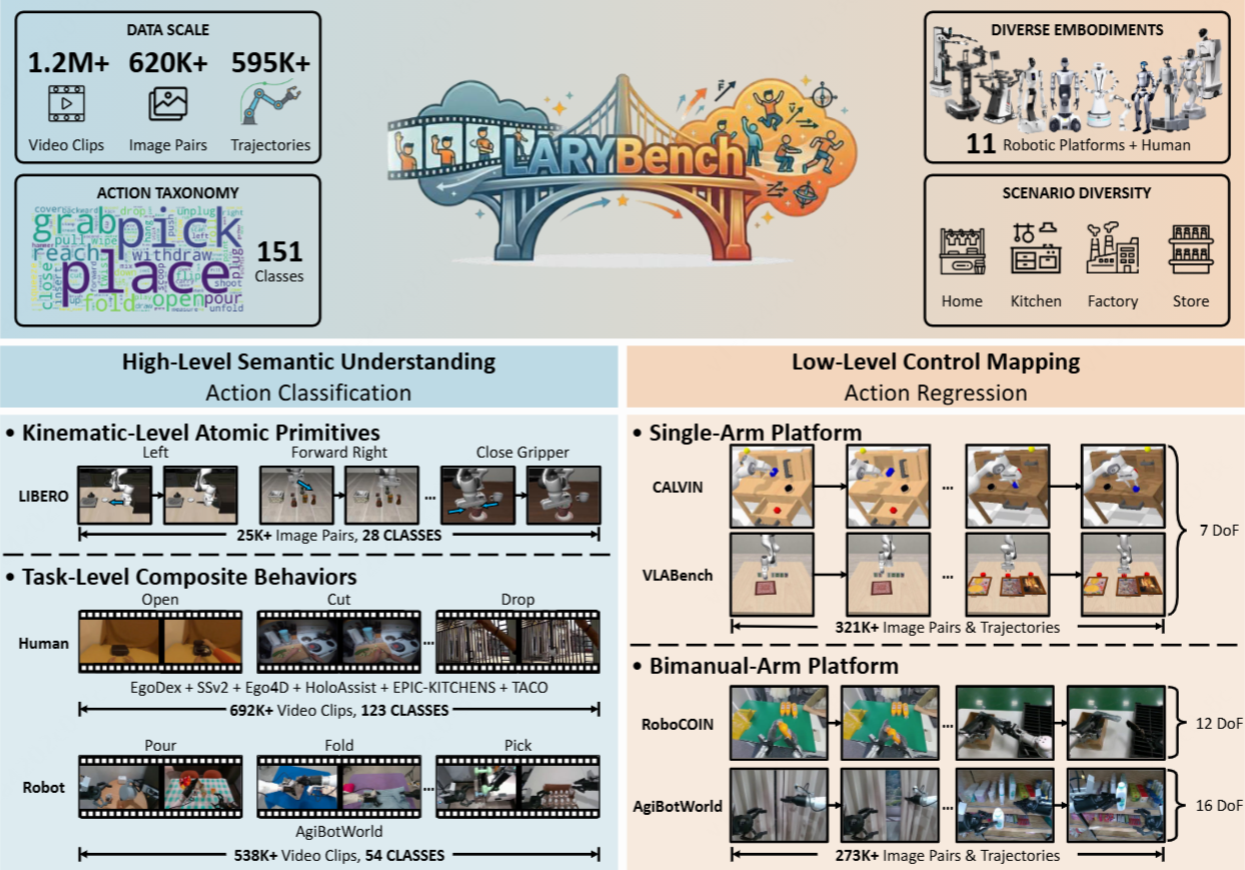
LARYBench Launch: Defining the ImageNet for Embodied Action Representation and Measuring Generalization from Human Video Data
The Meituan Technology Team has officially introduced LARYBench (Latent Action Representation Yielding Benchmark), a systematic evaluation framework designed to guide the learning of general latent action representations from large-scale visual data. This benchmark represents a significant milestone in the field of embodied AI, often compared to the 'ImageNet' moment for action representation. Experimental results provided by the team indicate that general vision models significantly outperform specialized embodied AI expert models in both action generalization and control precision. Crucially, the research demonstrates that embodied action representations can emerge naturally from extensive human video datasets, offering a new methodology for training robotic systems without relying solely on specialized, task-specific data.
Key Takeaways
- Introduction of LARYBench: A systematic benchmark designed to evaluate and guide the learning of general latent action representations from large-scale visual datasets.
- Superiority of General Models: General vision models demonstrate significantly better performance in action generalization and control precision compared to specialized embodied AI expert models.
- Emergence from Human Video: The research proves that embodied action representations can emerge from large-scale human video data, rather than requiring only robot-specific data.
- A New Industry Standard: LARYBench is positioned as the 'ImageNet' for embodied AI, providing a standardized way to measure how well models learn to represent actions.
In-Depth Analysis
The Shift from Specialized Experts to General Vision Models
One of the most striking findings from the LARYBench evaluation is the performance gap between general vision models and specialized embodied AI action expert models. Traditionally, the development of embodied AI has relied heavily on 'expert models'—systems specifically trained on narrow, task-oriented datasets to perform precise physical actions. However, the Meituan Technology Team's research reveals that general vision models, which are trained on much broader and more diverse visual data, exhibit superior capabilities in two critical areas: action generalization and control precision.
Action generalization refers to the ability of a model to apply learned representations to new, unseen scenarios or tasks. The fact that general models outperform specialized ones suggests that the features learned from diverse visual contexts are more robust and adaptable than those learned from narrow robotic demonstrations. Furthermore, the improvement in control precision indicates that these general representations are not just broad, but also sufficiently detailed to guide fine-grained physical movements. This discovery challenges the prevailing notion that embodied intelligence requires highly specialized architectures from the outset, suggesting instead that a foundation in general visual understanding may be more effective.
Human Video Data as a Source for Embodied Intelligence
A core contribution of the LARYBench framework is the demonstration that embodied action representations can emerge from large-scale human video data. This is a transformative concept for the industry because human video data is far more abundant and easier to collect than teleoperated robot demonstrations or simulated environments. By showing that models can learn the 'latent' or underlying structure of actions by observing humans, the research opens a path toward scaling embodied AI using the vast amount of video content available on the internet.
This 'emergence' suggests that the fundamental physics and logic of movement are embedded within human activities and can be captured by advanced vision models. When these models are evaluated through LARYBench, they show a surprising ability to translate 'watching' into 'understanding action.' This reduces the dependency on expensive and hard-to-scale robot-specific datasets, potentially accelerating the development of robots that can operate in diverse human environments.
Establishing a Systematic Evaluation Framework
Before LARYBench, the field of embodied AI lacked a systematic way to measure the quality of latent action representations. By defining what the Meituan team calls the 'ImageNet for embodied action representation,' LARYBench provides a standardized metric for the community. This allows researchers to compare different models and training techniques on a level playing field, focusing on how well they yield representations that are useful for physical control.
The benchmark focuses on the 'latent' aspect of action—the internal representation that sits between seeing an image and performing a movement. By measuring how these representations facilitate generalization and precision, LARYBench ensures that the AI industry can move beyond anecdotal success in specific tasks toward a more rigorous, scientific understanding of how machines learn to move.
Industry Impact
The launch of LARYBench is likely to have a profound impact on the AI and robotics industries. By proving that general vision models are more effective than specialized experts, it encourages a shift in research investment toward large-scale foundation models for robotics. Companies may pivot from collecting niche robotic data to leveraging massive human video datasets, significantly lowering the barrier to entry for developing capable embodied agents.
Furthermore, as a systematic benchmark, LARYBench will likely drive competition and innovation in model architecture. Much like how ImageNet catalyzed the deep learning revolution in computer vision, LARYBench provides the necessary infrastructure for the 'embodied AI revolution.' It sets a clear goal for the industry: the creation of models that don't just see the world, but understand the latent actions required to interact with it effectively.
Frequently Asked Questions
Question: What is LARYBench and why is it compared to ImageNet?
LARYBench stands for Latent Action Representation Yielding Benchmark. It is compared to ImageNet because it aims to provide a systematic, large-scale standard for evaluating how AI models represent actions, similar to how ImageNet standardized object recognition in computer vision.
Question: Why do general vision models perform better than specialized expert models in this benchmark?
According to the research, general vision models show superior action generalization and control precision. This is likely because the diverse data they are trained on allows them to develop more robust and adaptable representations of the world, which are more effective for complex embodied tasks than the narrow focus of specialized expert models.
Question: Can robots really learn to move just by watching human videos?
The LARYBench results indicate that embodied action representations can 'emerge' from large-scale human video data. This means that by analyzing how humans move and interact with the world in videos, AI models can learn the underlying principles of action, which can then be applied to robotic control.

