
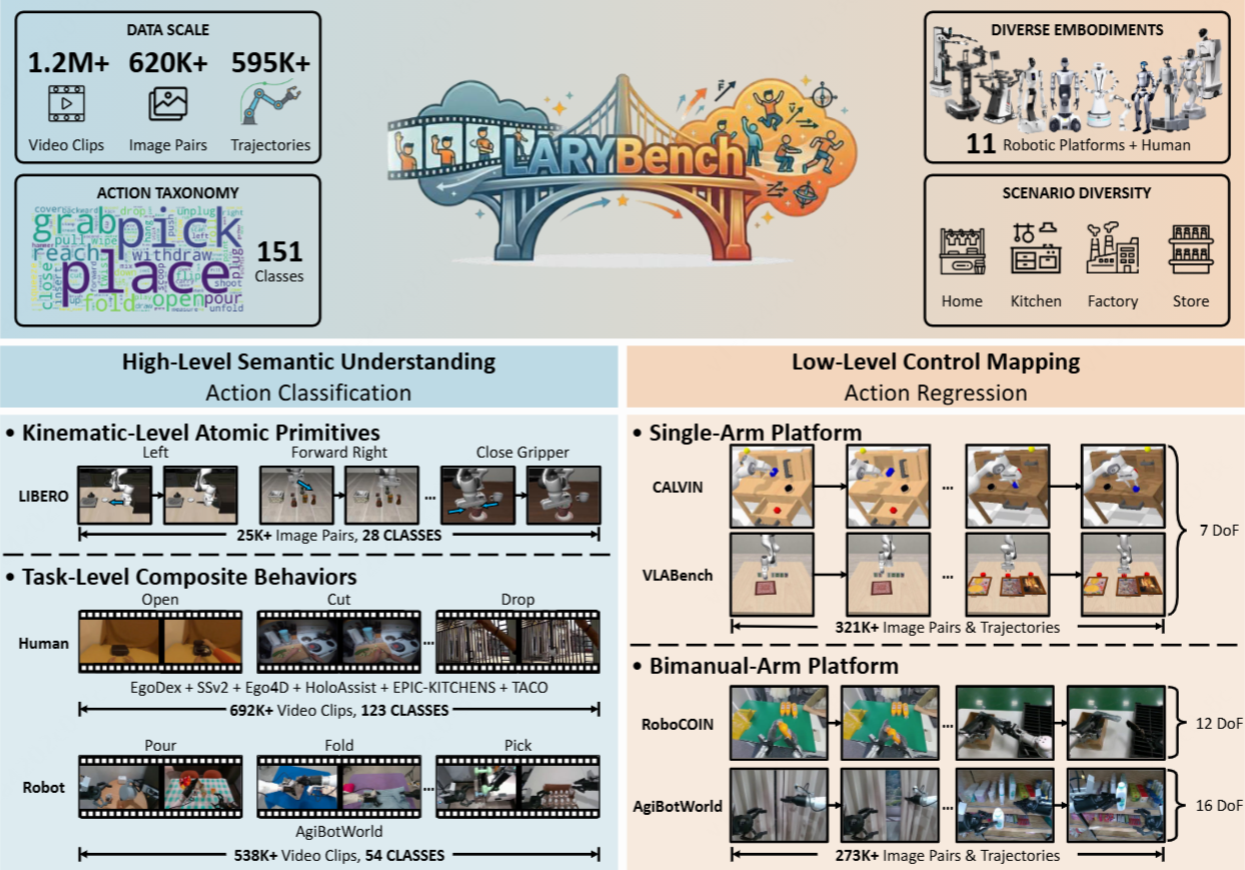
LARYBench: Defining the ImageNet for Embodied Action Representation and Generalization
The Meituan Technical Team has introduced LARYBench (Latent Action Representation Yielding Benchmark), a systematic evaluation framework designed to measure general latent action representations derived from large-scale visual data. This benchmark marks a significant milestone in embodied AI, often compared to the 'ImageNet' moment for action representation. Experimental findings reveal that general vision models significantly outperform specialized embodied AI expert models in both action generalization and control precision. Crucially, the research demonstrates that embodied action representations can effectively emerge from large-scale human video data, suggesting a new paradigm for training AI to understand and execute physical movements without relying solely on specialized robotic datasets.
Key Takeaways
- Introduction of LARYBench: A systematic benchmark designed to evaluate latent action representations learned from massive visual datasets.
- Superiority of General Models: General vision models demonstrate higher control precision and better action generalization than specialized embodied AI expert models.
- Emergence from Human Videos: The study proves that embodied action representations can emerge naturally from large-scale human video data.
- Standardizing Evaluation: LARYBench aims to serve as the 'ImageNet' for the field of embodied action representation, providing a unified metric for progress.
In-Depth Analysis
The LARYBench Framework: A New Standard for Embodied AI
The release of LARYBench (Latent Action Representation Yielding Benchmark) by the Meituan Technical Team addresses a critical gap in the development of embodied intelligence. While the field of computer vision has long benefited from standardized benchmarks like ImageNet, embodied AI has lacked a systematic way to measure how well models learn latent action representations from visual data. LARYBench provides the necessary infrastructure to evaluate how generalizable and precise these representations are when applied to physical tasks. By focusing on latent actions—the underlying patterns of movement that can be inferred from video—the benchmark allows researchers to quantify the effectiveness of models in a way that was previously fragmented.
General Vision Models vs. Specialized Action Experts
One of the most striking findings from the LARYBench experiments is the performance gap between general vision models and specialized embodied AI action expert models. Traditionally, the industry has leaned toward developing 'expert' models specifically trained on robotic or task-specific data to handle embodied movements. However, LARYBench results indicate that general vision models—those trained on broader, more diverse visual datasets—actually exhibit superior action generalization and control precision. This suggests that the features learned by general-purpose models are more robust and adaptable to the complexities of embodied tasks than the narrow features learned by specialized experts. This discovery could lead to a shift in how researchers approach model architecture for robotics and autonomous systems.
The Emergence of Action from Human Video Data
Perhaps the most significant theoretical contribution of LARYBench is the evidence that embodied action representations can emerge from large-scale human video data. This implies that AI does not necessarily need to be trained exclusively on robotic teleoperation data or simulated environments to understand physical action. Instead, by observing the vast amount of human activity captured in video, models can internalize the fundamental principles of movement and interaction. This 'emergence' indicates that the visual world contains enough structural information about physics and intent to inform embodied intelligence, potentially lowering the barrier to training sophisticated robotic controllers by leveraging existing internet-scale video content.
Industry Impact
The introduction of LARYBench is poised to influence the AI industry in several key ways. First, it provides a unified metric that allows different research teams to compare their models' performance in action representation, fostering faster innovation. Second, the finding that general vision models excel in this domain may encourage a convergence between the fields of Large Language Models (LLMs), General Vision Models, and Robotics. Companies may pivot their strategies toward pre-training on massive video datasets before fine-tuning for specific embodied tasks. Finally, the ability to learn from human videos reduces the reliance on expensive, hard-to-collect robotic data, potentially accelerating the deployment of embodied AI in real-world applications such as logistics, manufacturing, and domestic assistance.
Frequently Asked Questions
Question: What is LARYBench and why is it compared to ImageNet?
LARYBench stands for Latent Action Representation Yielding Benchmark. It is compared to ImageNet because it aims to provide a standardized, large-scale evaluation framework for embodied action representation, much like ImageNet did for object recognition in computer vision, setting a baseline for the entire industry.
Question: Why do general vision models perform better than specialized expert models in this benchmark?
According to the experimental results, general vision models possess better action generalization and control precision. This is likely because the diverse data they are trained on allows them to learn more flexible and robust representations of the world, which translate more effectively to varied embodied tasks than the narrow focus of specialized expert models.
Question: Can AI really learn how to move just by watching human videos?
Yes, the research associated with LARYBench demonstrates that embodied action representations can 'emerge' from large-scale human video data. This means that by analyzing how humans interact with the world in videos, AI can learn the latent structures of action required for embodied intelligence.

