Meituan LongCat Team Unveils LongCat-AudioDiT: Advancing Zero-Shot TTS Voice Cloning via Waveform Latent Space Diffusion
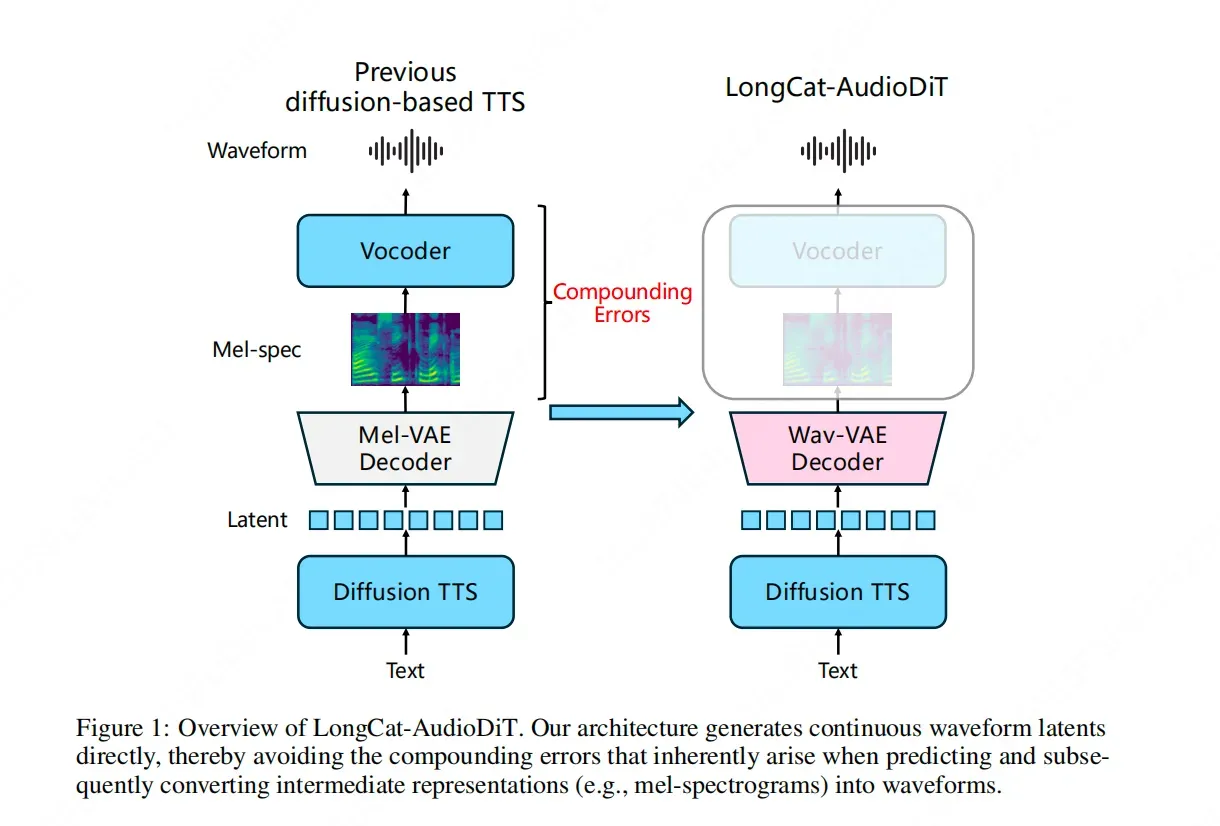
The Meituan LongCat team has officially released LongCat-AudioDiT, a pioneering model designed to overcome existing bottlenecks in zero-shot Text-to-Speech (TTS) voice cloning. By shifting away from traditional intermediate representations such as Mel-spectrograms, the model operates directly within the waveform latent space using a diffusion-based architecture. This strategic technical shift allows the AI to learn the inherent laws of sound directly, effectively bypassing the cascade errors typically associated with multi-stage data conversion. LongCat-AudioDiT represents a significant advancement in audio synthesis, focusing on root-level error prevention and high-fidelity voice reproduction. This development marks a shift toward more streamlined, end-to-end audio generation processes that prioritize the structural integrity of the original voice patterns during the cloning process.
Key Takeaways
- Direct Waveform Processing: LongCat-AudioDiT abandons traditional intermediate representations like Mel-spectrograms to work directly in the waveform latent space.
- Diffusion-Based Architecture: The model utilizes a diffusion-based approach (AudioDiT) to learn the fundamental laws of sound without intermediate steps.
- Elimination of Cascade Errors: By removing the need for data conversion between different representations, the model prevents the accumulation of errors at the source.
- Zero-Shot Capability: The system is specifically designed to push the upper limits of zero-shot voice cloning performance.
In-Depth Analysis
Breaking the Bottleneck: Moving Beyond Mel-spectrograms
In the traditional landscape of Text-to-Speech (TTS) and voice cloning, the industry has long relied on intermediate representations, most notably Mel-spectrograms. While effective, these representations act as a bridge between text and the final audio output, often requiring a two-step process: generating the spectrogram and then using a vocoder to convert that spectrogram back into a waveform. The Meituan LongCat team identified this as a critical technical bottleneck.
LongCat-AudioDiT introduces a paradigm shift by "thoroughly abandoning" these intermediate stages. The core philosophy behind this breakthrough is to allow the AI to directly perceive and learn the underlying patterns and laws of sound itself. By removing the Mel-spectrogram layer, the model reduces the complexity of the synthesis pipeline. This direct approach ensures that the nuances of the original voice are not lost or distorted during the translation between different data formats, which has historically been a primary source of quality degradation in zero-shot cloning scenarios.
Waveform Latent Space and Diffusion Transformers
The technical foundation of LongCat-AudioDiT lies in its use of the waveform latent space combined with a diffusion model. Traditional diffusion models in audio often operate on spectrograms, but LongCat-AudioDiT applies the Diffusion Transformer (DiT) framework directly to a compressed latent representation of the waveform. This allows the model to capture high-dimensional audio features while maintaining computational efficiency.
By operating in the latent space, the model can perform complex denoising processes to reconstruct high-fidelity audio from text inputs and a short voice prompt. The significance of this approach is the "root-level" blocking of cascade errors. In multi-stage systems, an error in the spectrogram generation phase is inevitably amplified during the vocoding phase. LongCat-AudioDiT’s architecture ensures that the generation process is unified, meaning the model learns the mapping from text to sound in a single, cohesive environment. This results in a more robust voice cloning capability that can handle the diverse requirements of zero-shot synthesis where the model must replicate a voice it has never encountered during training.
Industry Impact
The release of LongCat-AudioDiT by Meituan's technical team signals a major shift in the AI audio generation industry. By proving the viability of direct waveform latent space diffusion, the project sets a new standard for how voice cloning models are structured. The primary impact is the potential for significantly higher fidelity in zero-shot applications, which are crucial for personalized user experiences, digital assistants, and content creation.
Furthermore, the reduction of cascade errors addresses one of the most persistent challenges in neural audio synthesis. As the industry moves toward more integrated and end-to-end solutions, the methodologies pioneered in LongCat-AudioDiT may lead to more efficient training and inference processes. By skipping the intermediate "Mel-spectrogram" step, researchers can focus on optimizing the direct relationship between linguistic input and acoustic output, potentially lowering the barrier for high-quality, real-time voice cloning technology.
Frequently Asked Questions
Question: What makes LongCat-AudioDiT different from traditional TTS models?
Traditional TTS models usually convert text into a Mel-spectrogram before turning it into sound. LongCat-AudioDiT skips this intermediate step and works directly in the waveform latent space using a diffusion model to learn sound patterns directly.
Question: How does this model prevent errors in voice cloning?
It prevents "cascade errors," which occur when mistakes in one stage of data conversion (like creating a spectrogram) are passed on and worsened in the next stage. By using a direct, end-to-end diffusion process, these conversion steps are eliminated.
Question: What is the benefit of "zero-shot" voice cloning?
Zero-shot voice cloning allows the AI to replicate a person's voice using only a very short sample, without needing to be specifically trained on that person's voice beforehand. LongCat-AudioDiT aims to push the performance limits of this specific capability.