
Meituan LongCat Team Unveils LongCat-AudioDiT: Advancing Zero-Shot TTS via Direct Waveform Latent Space Diffusion
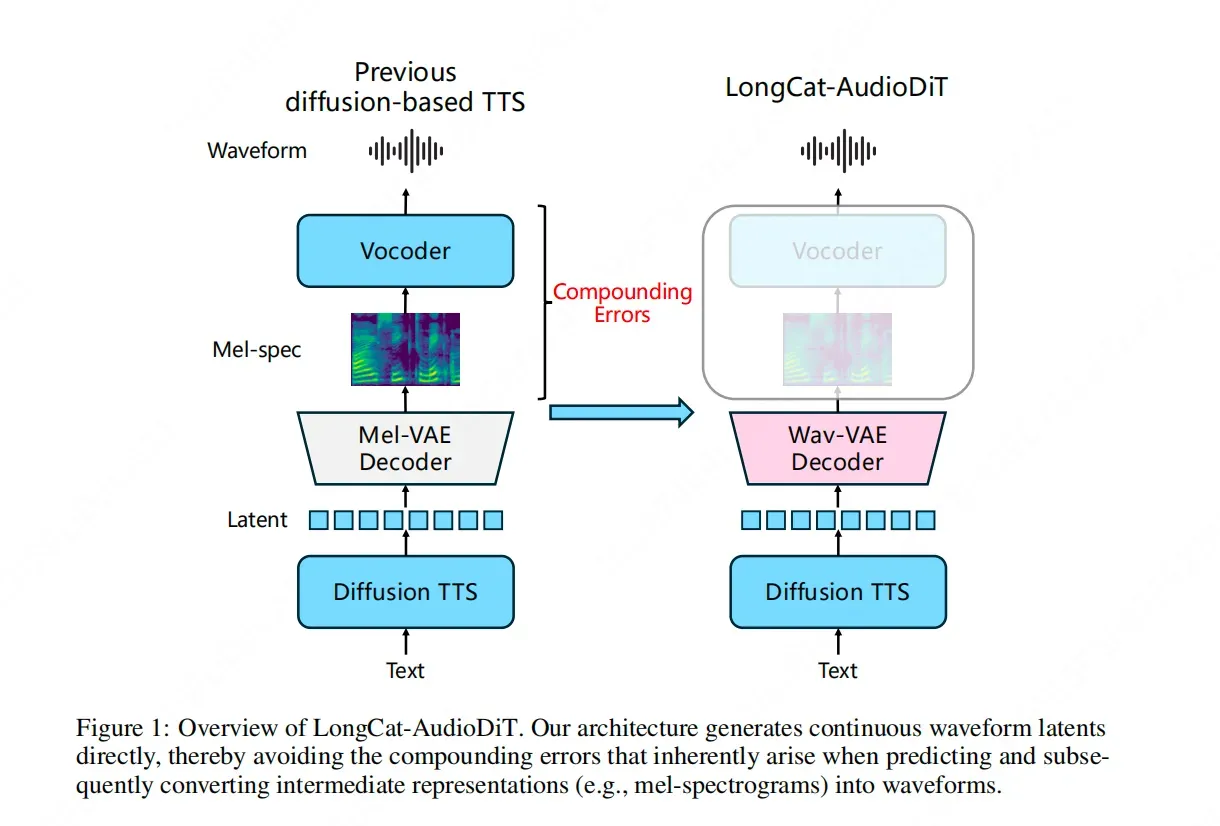
The Meituan LongCat technical team has officially introduced LongCat-AudioDiT, a pioneering model designed to redefine the limits of zero-shot Text-to-Speech (TTS) voice cloning. By fundamentally altering the synthesis pipeline, the model abandons traditional intermediate representations such as Mel-spectrograms in favor of direct operation within the waveform latent space. Utilizing a diffusion-based architecture, LongCat-AudioDiT aims to allow AI to learn the inherent laws of sound directly, thereby eliminating the cascade errors typically caused by multi-stage data conversions. This breakthrough focuses on architectural purity to enhance the fidelity and authenticity of cloned voices, marking a significant technical shift in how generative audio models process and reconstruct human speech without the need for extensive fine-tuning.
Key Takeaways
- Elimination of Intermediate Steps: LongCat-AudioDiT removes the need for Mel-spectrograms, moving directly from text to waveform latent space.
- Diffusion-Based Architecture: The model leverages diffusion processes to synthesize high-fidelity audio, focusing on the underlying patterns of sound.
- Reduction of Cascade Errors: By bypassing traditional data conversion stages, the system prevents the accumulation of errors that often degrade voice cloning quality.
- Zero-Shot Capability: The technology is specifically designed to push the boundaries of zero-shot voice cloning, allowing for high-quality mimicry without specific training on target voices.
- Direct Sound Law Learning: The AI is engineered to understand the fundamental physical and acoustic laws of audio directly from the waveform latent space.
In-Depth Analysis
Moving Beyond Mel-Spectrograms
In the evolution of Text-to-Speech (TTS) technology, the industry has long relied on intermediate representations, most notably Mel-spectrograms, to bridge the gap between abstract text and audible waveforms. While effective, these intermediate steps act as a bottleneck. The Meituan LongCat team identifies these representations as a source of "cascade errors"—where inaccuracies in the conversion from text to spectrogram, and subsequently from spectrogram to waveform, compound and result in a loss of vocal nuance and clarity.
LongCat-AudioDiT represents a radical departure from this convention. By abandoning Mel-spectrograms entirely, the model operates within a waveform latent space. This approach ensures that the generative process remains as close to the raw audio data as possible. The significance of this shift cannot be overstated; it allows the AI to capture the complexities of human speech—such as timbre, emotion, and prosody—without the filtering effect of traditional frequency-domain representations.
Diffusion Models in the Waveform Latent Space
The core mechanism of LongCat-AudioDiT is its use of diffusion models applied directly to the waveform latent space. Diffusion models have proven exceptionally capable in image generation, and the LongCat team has successfully adapted this logic to the temporal and harmonic complexities of sound. Instead of predicting a static representation of audio, the model iteratively refines noise into a coherent waveform latent representation.
This method allows the AI to "learn the laws of sound itself." Rather than simply mapping text to a visual proxy of sound (the spectrogram), the model develops an understanding of how audio signals are structured at a fundamental level. By operating in the latent space of the waveform, the diffusion process can maintain high-dimensional features of the voice that are often lost in lower-dimensional intermediate steps, leading to a more authentic and robust zero-shot cloning performance.
Overcoming Technical Bottlenecks in Voice Cloning
The primary goal of the LongCat-AudioDiT project is to break the existing "upper limit" of zero-shot voice cloning. Zero-shot cloning is particularly challenging because the model must replicate a voice it has never encountered during its primary training phase based on a very short sample. Traditional models often struggle with this because the conversion errors mentioned earlier become more pronounced when the model lacks specific data for a target speaker.
By blocking the root cause of these errors—the data conversion process—LongCat-AudioDiT provides a cleaner path for the AI to replicate the target's acoustic characteristics. The model's ability to skip the "middleman" of audio processing means that the resulting output is not just a reconstruction of a spectrogram, but a direct synthesis of the voice's unique waveform patterns. This architectural purity is the key to achieving a higher level of naturalness and similarity in zero-shot scenarios.
Industry Impact
The introduction of LongCat-AudioDiT by Meituan signals a potential shift in the standard pipeline for generative audio. For the AI industry, this move toward "end-to-end" waveform latent synthesis suggests that the era of Mel-spectrogram-based TTS may be reaching its conclusion for high-end applications.
Furthermore, the focus on eliminating cascade errors highlights a growing trend in AI research: the move toward architectural simplification to improve output quality. As zero-shot voice cloning becomes more prevalent in customer service, content creation, and personalized digital assistants, the ability to produce high-fidelity audio without the computational and qualitative baggage of intermediate representations will be a significant competitive advantage. LongCat-AudioDiT sets a new benchmark for how models can be designed to respect the raw integrity of the data they are meant to simulate.
Frequently Asked Questions
Question: What makes LongCat-AudioDiT different from traditional TTS models?
Traditional TTS models usually convert text into an intermediate visual representation of sound called a Mel-spectrogram before turning it into a waveform. LongCat-AudioDiT skips this intermediate step and works directly within the waveform latent space using diffusion models, which prevents errors from building up during the conversion process.
Question: Why is the elimination of "cascade errors" important for voice cloning?
Cascade errors occur when small mistakes in one stage of a process (like creating a spectrogram) are carried over and magnified in the next stage (like creating the final audio). By removing the intermediate stages, LongCat-AudioDiT ensures that the final voice output is more accurate and retains the original characteristics of the voice being cloned.
Question: What does "learning the laws of sound directly" mean?
It means that instead of the AI being taught to match text to a specific chart or graph of sound, it is designed to understand the underlying mathematical and physical patterns of how waveforms are constructed. This allows the AI to generate more natural and fluid speech that sounds like a real human voice rather than a digital reconstruction.

