LARYBench Released: Establishing the ImageNet for Embodied Action Representations via Human Video Learning
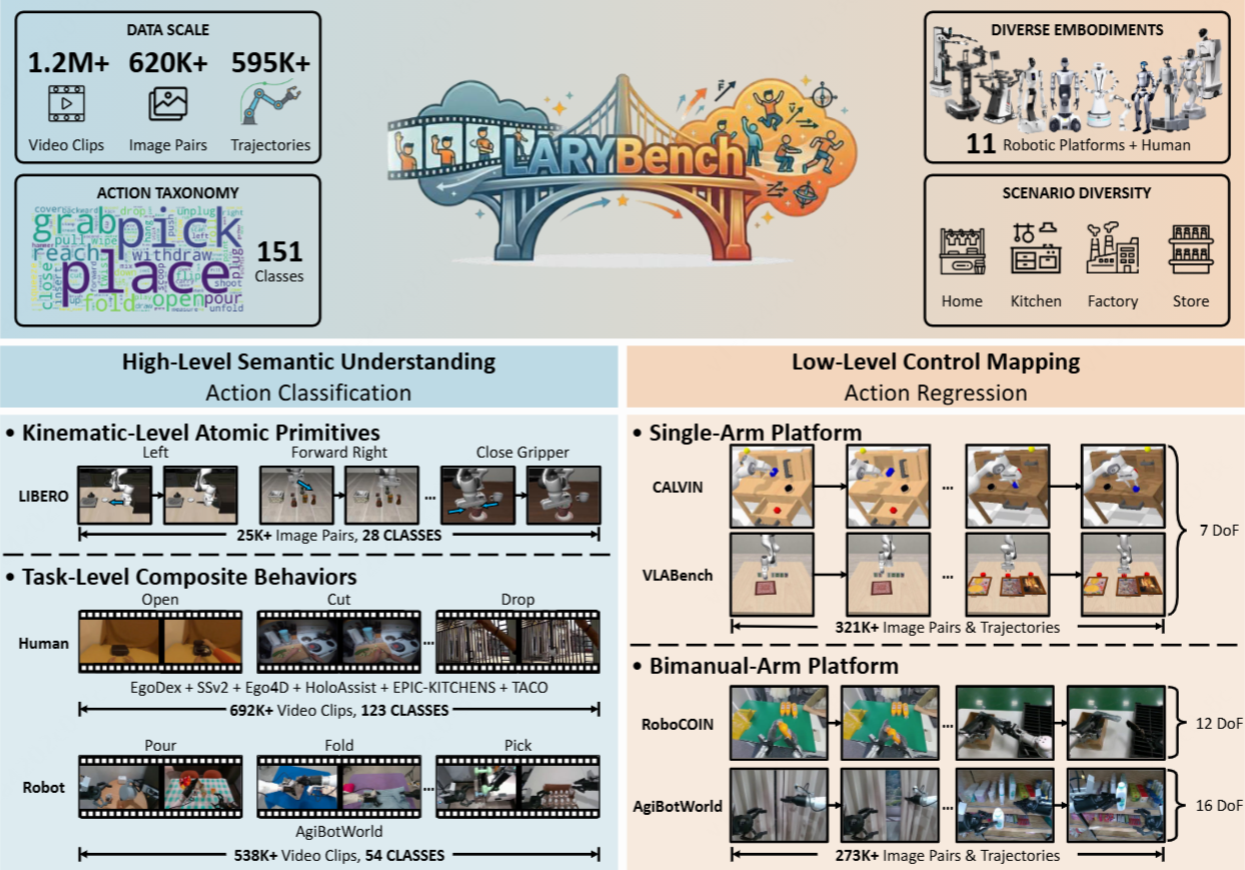
The Meituan Technology Team has officially released LARYBench (Latent Action Representation Yielding Benchmark), a systematic evaluation framework designed to guide the learning of general latent action representations from large-scale visual data. This benchmark marks a significant milestone in embodied AI, drawing parallels to the impact of ImageNet on computer vision. Experimental results provided by the team indicate a paradigm shift: general vision models significantly outperform specialized action expert models in both action generalization and control precision. Crucially, the research demonstrates that sophisticated embodied action representations can emerge naturally from large-scale human video data, offering a new pathway for developing more capable and adaptable autonomous agents.
Key Takeaways
- Introduction of LARYBench: A systematic benchmark designed to evaluate and guide the development of general latent action representations from massive visual datasets.
- Superiority of General Models: General vision models have been found to outperform specialized embodied AI expert models in terms of control precision and generalization capabilities.
- Human Video Data Utility: The benchmark proves that embodied action representations can successfully emerge from large-scale human video data, reducing the reliance on specialized robotic datasets.
- A New Standard for Embodied AI: LARYBench aims to serve as the 'ImageNet' for the field of action representation, providing a standardized metric for progress.
In-Depth Analysis
The Emergence of LARYBench as a Systematic Benchmark
The release of LARYBench (Latent Action Representation Yielding Benchmark) by the Meituan Technology Team addresses a critical gap in the field of embodied AI: the lack of a standardized, systematic way to measure how well an AI understands and represents actions. Much like how ImageNet revolutionized visual object recognition by providing a massive, structured dataset for evaluation, LARYBench is positioned to define the standards for latent action representation. By focusing on learning from large-scale visual data, the benchmark provides a framework for researchers to develop models that do not just see the world, but understand the underlying mechanics of movement and interaction within it.
General Vision Models vs. Specialized Action Experts
One of the most striking findings revealed through LARYBench is the performance gap between general-purpose vision models and specialized embodied AI action expert models. Traditionally, the industry has leaned toward creating 'expert' models—AI systems specifically trained on narrow robotic or task-specific datasets to achieve high precision. However, the experimental results from LARYBench suggest that general vision models, which are trained on broader and more diverse visual information, possess a superior ability to generalize across different actions and maintain higher control precision. This suggests that the breadth of data inherent in general models provides a more robust foundation for embodied intelligence than the depth of specialized, but limited, expert training.
Action Representation Emergence from Human Videos
Perhaps the most significant technical insight provided by the LARYBench release is the confirmation that embodied action representations can emerge from large-scale human video data. This is a transformative concept for the industry. Instead of requiring labor-intensive, robot-specific demonstrations for every possible task, AI models can learn the 'latent' rules of action by observing the vast amount of human activity captured in existing video libraries. LARYBench demonstrates that the visual patterns of human movement contain sufficient information for AI to derive generalizable action representations, which can then be applied to embodied tasks. This discovery validates the use of diverse human video datasets as a primary resource for training the next generation of autonomous systems.
Industry Impact
The introduction of LARYBench is likely to redirect the focus of embodied AI research toward the utilization of general-purpose foundation models. By proving that general vision models are more effective than specialized experts, the benchmark encourages a shift away from siloed data collection toward the integration of massive, diverse visual datasets. For the robotics and automation industries, this means that the path to high-precision control and broad generalization may lie in leveraging human-centric video data, which is far more abundant than specialized robotic telemetry. Furthermore, as a standardized benchmark, LARYBench will allow for objective comparisons between different modeling approaches, accelerating the pace of innovation in how machines learn to interact with their physical environments.
Frequently Asked Questions
Question: What is the primary purpose of LARYBench?
LARYBench is a systematic evaluation benchmark designed to guide and measure the learning of general latent action representations from large-scale visual data, acting as a foundational metric for embodied AI.
Question: How do general vision models compare to specialized expert models according to the benchmark?
Experimental results from LARYBench show that general vision models significantly outperform specialized action expert models in both the precision of control and the ability to generalize actions across different scenarios.
Question: Can AI learn how to act by simply watching human videos?
Yes, according to the findings associated with LARYBench, embodied action representations can emerge from large-scale human video data, allowing models to learn generalizable action patterns from observing human movements.