Gemini 3.8 & 3.8 Live Extended Thinking favicon

Gemini 3.8 & 3.8 Live Extended Thinking

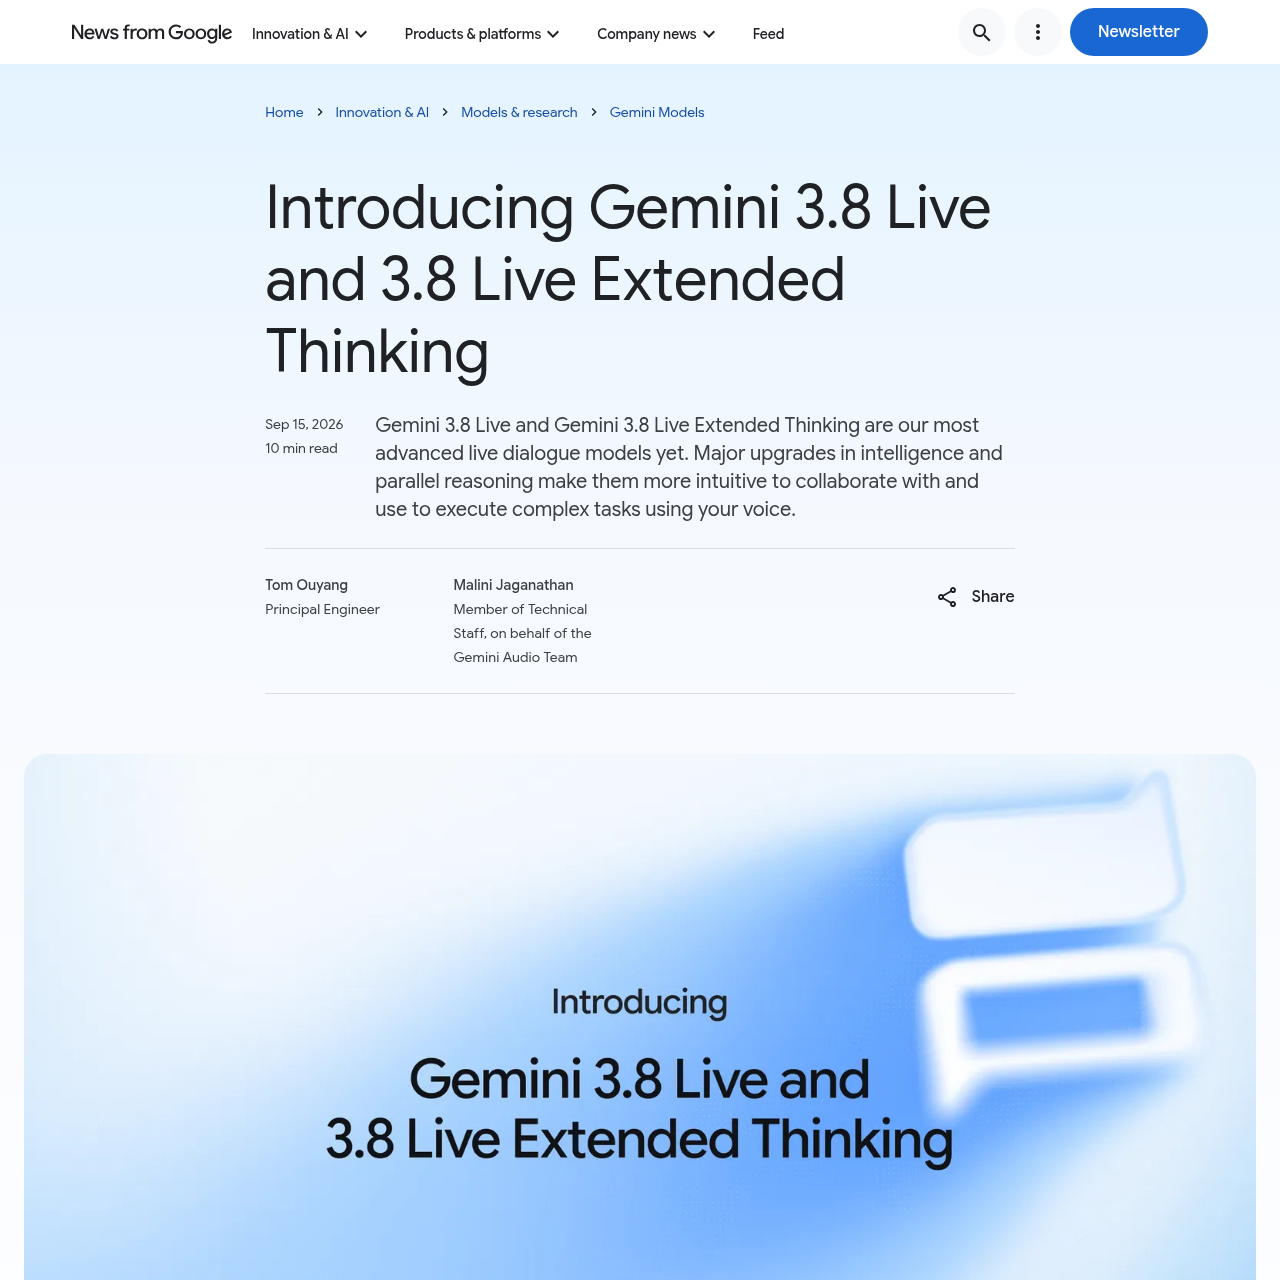
Gemini 3.8 Live and 3.8 Live Extended Thinking are real-time voice and multimodal dialogue models engineered for concurrent reasoning, background tool calling, and live interactive voice workflows.

Chat BotSimultaneous spoken dialogue and…Automatic identification and…Visual context processingAsynchronous background tool execution…
Gemini 3.8 & 3.8 Live Extended Thinking product interface screenshot
Estimated monthly visits
8.8M
Data period:
Listed on AIToolly

What Is Gemini 3.8 & 3.8 Live Extended Thinking? Product Overview

What the product does and how it is positioned

Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking are dialogue models designed for near real-time voice interactions, visual grounding, and multi-step reasoning.

Gemini 3.8 Live focuses on scalable conversational intelligence with automatic language switching across 97 languages, while 3.8 Live Extended Thinking delivers simultaneous parallel reasoning, early conversational cues, and continuous background task narration.

What Can You Use Gemini 3.8 & 3.8 Live Extended Thinking For?

Source-supported ways to use the product

Real-Time Employee Onboarding

Guiding employee onboarding sessions dynamically by answering questions using real-time visual context.

Asynchronous Booking Coordination

Coordinating multi-step bookings and running background function calls without interrupting live spoken conversation.

Visual Code Generation from Sketches

Transforming hand-drawn visual sketches and spoken instructions into functional React components.

Parallel Reasoning and Background Tool Execution

Gemini 3.8 Live Extended Thinking addresses interruptions in voice workflows by reasoning and speaking at the same time. Rather than pausing dialogue while processing complex requests, the model introduces conversational cues like verbal acknowledgments and progress narration.

Background execution capabilities allow both models to make API calls, run external tools, and handle multi-step actions asynchronously. Spoken interaction continues without pauses while underlying tasks finalize.

  • Uses early verbal cues such as acknowledgments to confirm incoming requests naturally
  • Delivers live progress narration to explain multi-step actions as they execute in the background
  • Maintains uninterrupted spoken conversations during external tool execution and API calls

What to Test Before Choosing Gemini 3.8 & 3.8 Live Extended Thinking

Checks to run with your own material and workflow

  • Verify whether required conversational languages are supported among the 97 automatically detected languages.
  • Confirm whether your organization has access to private preview programs for Gemini Enterprise deployment.
  • Check whether target workflows require standard live conversation via 3.8 Live or simultaneous multi-step reasoning via 3.8 Live Extended Thinking.

Gemini 3.8 & 3.8 Live Extended Thinking Sources and Last Checked

What was checked and when

Last checked
Category
Chat Bot

Gemini 3.8 & 3.8 Live Extended Thinking Frequently Asked Questions

Answers based on the source-checked product record

How does Gemini 3.8 Live Extended Thinking handle complex tasks during a call?

It reasons and speaks simultaneously, using natural verbal acknowledgments and live progress narration to keep conversation flowing while multi-step tasks run.

How many languages do the models support during live conversation?

The models automatically detect and transition between 97 supported languages mid-conversation without manual setting adjustments.

How is generated audio verified as artificial intelligence output?

All audio output generated by the models is embedded with an imperceptible SynthID watermark to ensure the media remains detectable as AI-generated content.

Where can developers access these voice models?

Developers can access both models through the Gemini API and Google AI Studio, as well as through supported partner streaming platforms.

Can Gemini 3.8 Live process visual context alongside voice?

Yes, Gemini 3.8 Live processes visual inputs in near real-time, allowing the model to ground conversations and answer questions based on visual context.

Explore other recently added tools in the same category.