Black Forest Labs Makes the Case for Learning AGI From Pixels, Motion, and Sound
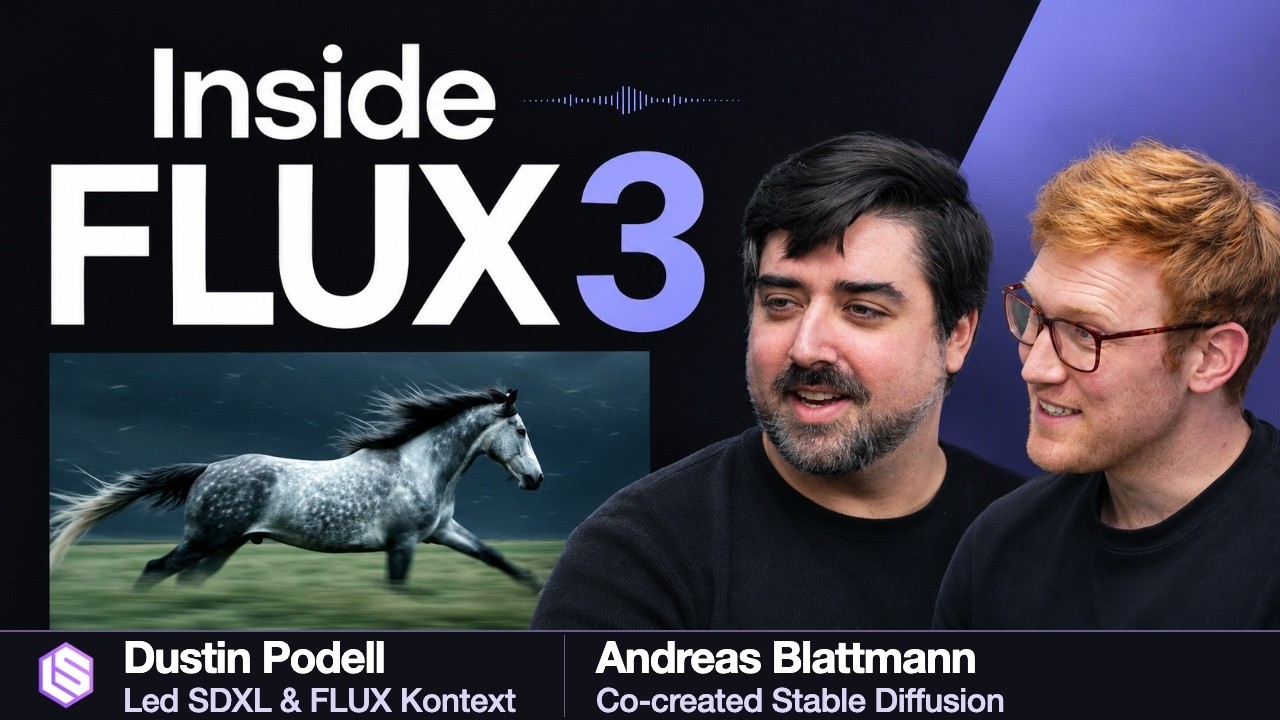
Latent Space’s “Building Visual Intelligence” names Andreas Blattmann and Dustin Podell of Black Forest Labs and presents the lab’s case for learning artificial general intelligence (AGI) from pixels, motion, and sound. The title puts visual intelligence at the center, while the description makes clear that the topic extends beyond pixels alone: it explicitly includes both motion and sound. The supplied material states the premise but does not explain how those inputs would be used, describe a model, or report results. The key distinction is that the piece is framed as a case for a way to learn AGI, not as an announcement that Black Forest Labs has achieved it.
Key Takeaways
- Latent Space’s “Building Visual Intelligence” names Andreas Blattmann and Dustin Podell of Black Forest Labs.
- The description presents Black Forest Labs’ case for learning artificial general intelligence (AGI) from pixels, motion, and sound.
- Although the title emphasizes visual intelligence, the description explicitly includes sound alongside pixels and motion.
- The supplied description gives the premise but does not specify a training method, describe a model, or report results.
In-Depth Analysis
What “Building Visual Intelligence” puts in focus
The title and description do different jobs. “Building Visual Intelligence” identifies the theme, while the description identifies the broader goal: learning AGI from pixels, motion, and sound. That distinction matters because the title alone might suggest a piece concerned exclusively with visual inputs. The description makes that reading too narrow. Pixels are named, but so are motion and sound, and sound in particular places part of the stated premise outside the visual domain. At the same time, the description does not define visual intelligence or explain its relationship to AGI. It does not say whether Black Forest Labs treats visual intelligence as a step toward AGI, a component of it, or the focus of an argument that reaches beyond vision. What can be said with confidence is that the item puts visual intelligence in the foreground and describes a case for learning AGI from all three named inputs. The supplied material does not establish a more specific relationship between the title and that goal.
What the list of inputs tells us—and what it does not
Pixels, motion, and sound are the most concrete part of the description. Motion is named separately from pixels, so summarizing the item as a case for learning AGI from pixels alone would leave out part of the premise. The same applies to sound: omitting it would turn a description that explicitly reaches beyond vision into one about vision alone. But the list does not tell readers how to interpret the role of each input. It does not say whether motion is learned from pixels or represented separately, whether sound is paired with visual material, or whether all three would be used together. Nor does it establish that these are the only inputs Black Forest Labs considers relevant. The wording identifies what the case is about, not how it would be implemented. A faithful reading therefore needs to preserve the specificity of the list without treating it as a training plan. The three terms explain why the title is not the whole story, but they do not explain how the proposed learning would work.
Why “the case for” is the key phrase
The description calls this Black Forest Labs’ “case for” learning AGI from the named inputs. That framing distinguishes an argument from an outcome. It tells readers what the lab is making a case for; it does not tell them what evidence the piece presents or whether any system has demonstrated the proposed capability. The supplied material names Andreas Blattmann and Dustin Podell in the title, but it does not quote either of them or attribute a particular part of the argument to either person. Likewise, it does not name a model, describe an experiment, or provide a result. Those are limits of the material supplied here, not statements about what the full Latent Space piece contains. The most precise account is that Latent Space identifies the direction of Black Forest Labs’ argument without providing enough detail in the supplied description to evaluate the argument itself.
Industry Impact
For AI industry readers, the relevance of this item lies in the question it foregrounds: what should a system learn from if the goal is AGI? Black Forest Labs’ case, as described by Latent Space, brings pixels, motion, and sound into that discussion. The distinction worth carrying forward is between the aim and the inputs. AGI is the stated aim of the learning described here; pixels, motion, and sound are what the description says the learning would draw on. Naming those inputs makes the lab’s premise more specific than the title alone, but it does not establish that the approach works or show how it compares with alternatives.
The description also provides no basis for identifying a change in industry practice. It does not report a product launch, provide a benchmark, or describe adoption by other organizations. Its significance in the supplied material is narrower: it identifies the position Black Forest Labs is making a case for. Readers can use that premise to frame questions for the full piece, such as how the lab connects visual intelligence to AGI and what role it gives each of the three inputs. The description itself does not answer those questions.
Frequently Asked Questions
What is Black Forest Labs making a case for?
Latent Space describes the piece as Black Forest Labs’ case for learning AGI from pixels, motion, and sound. The supplied description does not explain the reasoning behind that case or how the inputs would be used.
Who is named in “Building Visual Intelligence”?
The title names Andreas Blattmann and Dustin Podell of Black Forest Labs. The supplied description does not give their individual remarks or distinguish their contributions to the case.
Does the supplied description say Black Forest Labs has achieved AGI?
No. It presents a case for learning AGI from certain inputs. It does not report an AGI achievement, identify a system that demonstrates it, or provide results supporting such a claim.