
From LOOP to Graph Exploration: Meituan Unveils the Evolution of Its AutoResearch Self-Evolving Architecture
The Meituan Technical Team has detailed the architectural evolution of its autonomous algorithm research system, transitioning from a single-threaded loop to a sophisticated CyclicGraph Engine. Originating from Andrej Karpathy's open-source AutoResearch prototype, the enterprise platform underwent three major architectural iterations to overcome context explosion and operational instability. By introducing an asynchronous state machine and a Spawn-Converge mechanism, the system accelerates research iterations by 18 times compared to earlier architectures. Deployed across two distinct production modeling projects, the self-evolving system slashed end-to-end task turnaround time by 85% and 83% against human engineer baselines. Notably, one autonomous solution achieved full production deployment with documented business gains, while another surpassed manual baselines across all 12 predictive targets, demonstrating the viability of autonomous AI-driven algorithm design.
Key Takeaways
- Architecture Paradigm Shift: Meituan evolved its AutoResearch system through three generations, moving away from single-threaded sequential loops toward a parallelized CyclicGraph Engine.
- Substantial Efficiency Leap: In two distinct production modeling scenarios, the system compressed task completion timelines by 85% and 83% compared to manual baselines.
- Production-Validated Outcomes: One autonomously derived model has been pushed to full production deployment, yielding quantifiable online business gains, while another outpaced human benchmarks across all 12 target objectives.
- Rigid Trustworthiness Engineering: By adhering to the design maxim that "constraints capable of programmatic expression must not rely on prompts," the architecture enforces code diffs, raw metrics, and state machines as strict evidence anchors.
In-Depth Analysis
The Three-Phase Evolution: From Local Prototypes to CyclicGraph Engine
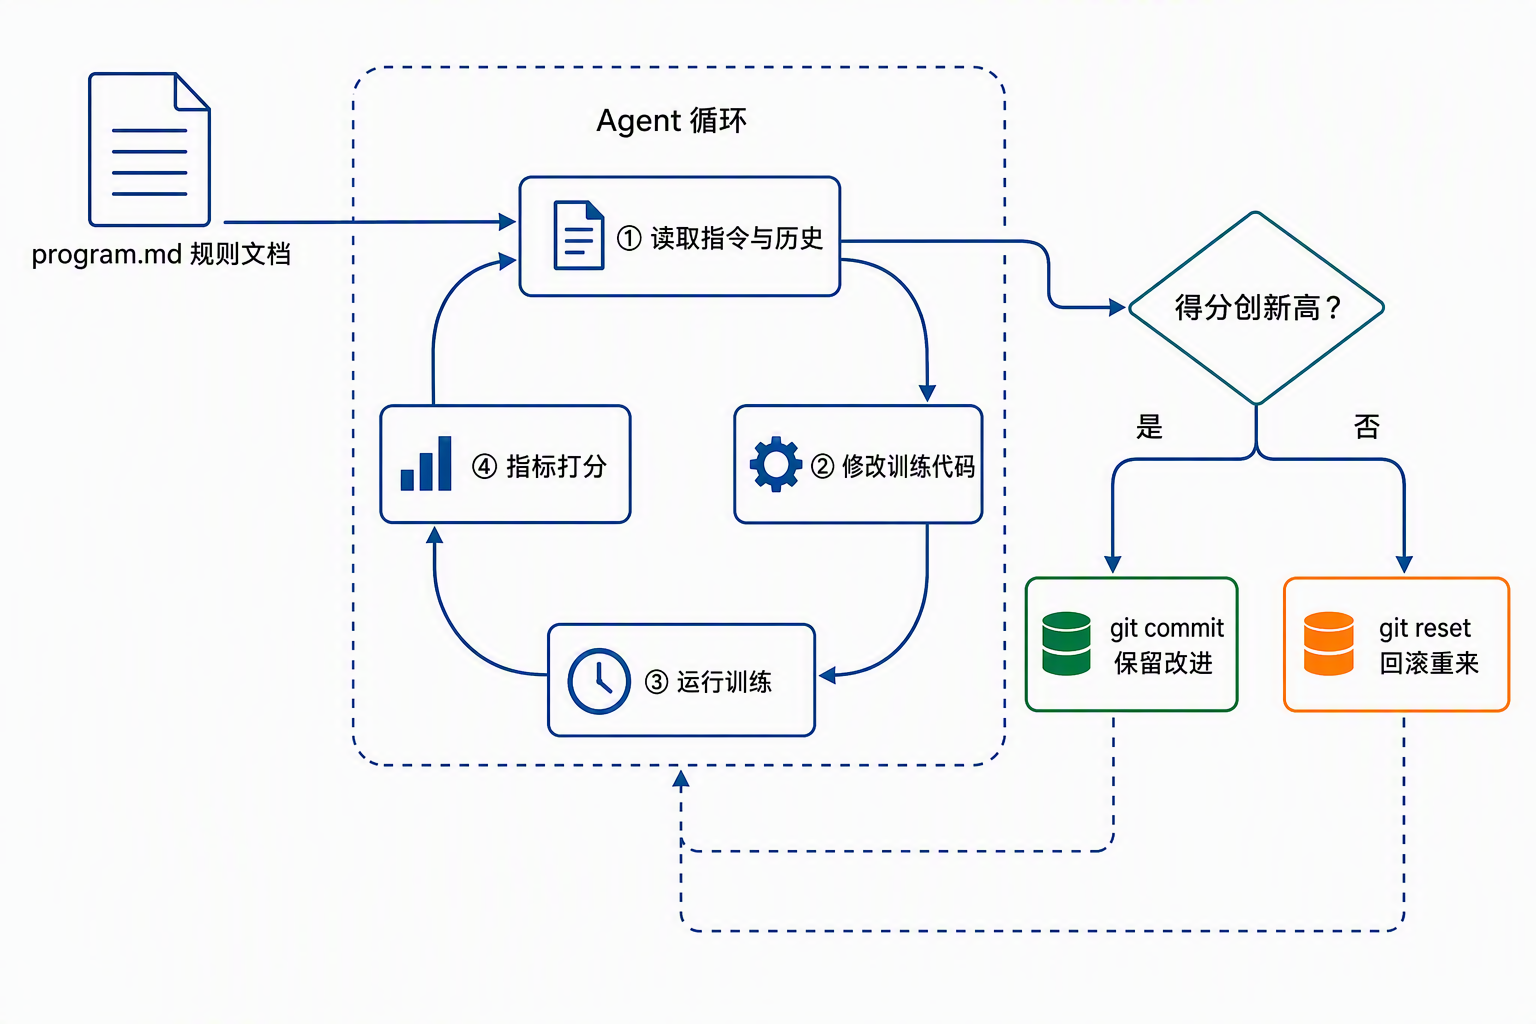
A conventional algorithm engineer's daily workflow is traditionally dominated by a fragmented loop: modifying code, launching training runs, waiting, parsing execution logs, and determining subsequent iterations. Drawing initial inspiration from Andrej Karpathy's open-source AutoResearch prototype—which demonstrated autonomous model tuning using a minimal three-file configuration (program.md, train.py, prepare.py)—Meituan transitioned this concept into enterprise-scale infrastructure through three systematic refactorings:
- Version 1 (Cloud Migration): Adapted the single-threaded linear LOOP framework onto enterprise cloud clusters, validating that autonomous agents could interact with internal computing infrastructure.
- Version 2 (State Machine & Asynchronous Decoupling): Resolved LLM context window saturation by decoupling execution state from conversation history. It implemented a minimal JSON state machine and asynchronous event triggers, allowing fresh agent sessions to resume tasks without maintaining long, brittle conversational contexts.
- Version 3 (Graph Exploration via Spawn-Converge): Replaced sequential trial-and-error with a graph-based exploration model. Under this paradigm, an orchestrating agent formulates mutually exclusive hypotheses and spawns multiple context-isolated sub-agents to execute experiments concurrently. The primary agent subsequently gathers empirical evidence, compares performance, and determines the next research phase, boosting iteration speed by 18 times over the initial LOOP design.
Engineering Trustworthiness: Deterministic Guards Over Prompt Reliance
Autonomous experimentation in enterprise environments introduces critical risks around hallucination and unproductive resource consumption. To mitigate this, Meituan structured the system around deterministic code constraints rather than soft prompt directives:
- State Files as the Single Source of Truth: System states, job progress, and execution checkpoints are persisted strictly in schema-validated files, ensuring absolute recovery and idempotency across cluster restarts.
- Hard Pruning of Falsified Hypotheses: When an experimental trajectory proves ineffective, it is committed as a negative constraint in code to permanently prevent repeated explorations of known failure modes.
- Immutable Evidence Anchors: The system accepts only non-bypassable artifacts—specifically raw evaluation metrics and git diff outputs—to justify model transitions, eliminating self-reported agent assertions.
- Audited Experience Accumulation: While the engine autonomously formulates reusable domain "Skills" from positive experiments, these candidate modules undergo automated pre-checks and mandatory human-in-the-loop review before integration into the active knowledge repository.
Empirical Validation Across Production Workloads
The architectural validity was demonstrated across two production modeling projects featuring completely different structural properties, objectives, and application environments. In the first project, the autonomous framework reduced task completion time by 85%, producing an algorithmic enhancement that was fully deployed to live production traffic and generated measurable business gains. In the second project, focusing on complex multi-objective optimization, the system lowered task time by 83% while simultaneously surpassing human baselines across all 12 predictive metrics. Because both projects shared only the underlying CyclicGraph platform, the efficiency and performance gains are directly attributable to the architecture itself.
Industry Impact
Meituan's evolution of AutoResearch marks an important transition from speculative LLM coding assistants toward autonomous, domain-specific AI research agents operating on real-world industrial workloads. By replacing linear trial-and-error with parallel graph search and decoupling stateless reasoning agents from stateful operational logs, the work establishes an engineering blueprint for scaling automated scientific discovery.
However, the team emphasizes critical operational boundaries: the architecture is strictly applicable to domains where evaluation metrics are mathematically quantifiable, experimental modifications are computationally reversible, and individual training runs incur manageable costs. For enterprise AI teams, this signals that future productivity breakthroughs will increasingly depend on hybrid architectures combining parallel agentic planning with strict deterministic sandboxing and human oversight.
Frequently Asked Questions
What is the primary difference between the original LOOP architecture and the CyclicGraph Engine?
The original LOOP architecture executed experiments sequentially in a single thread, which was vulnerable to context explosion and slow iteration cycles. The CyclicGraph Engine uses a Spawn-Converge pattern that allows a primary agent to dispatch multiple isolated sub-agents to test hypotheses concurrently, increasing iteration throughput by 18 times.
How does the system prevent LLM hallucinations during experimentation?
The system enforces a "code over prompts" philosophy. Decisions require immutable evidence anchors, including Git code diffs and raw evaluation metrics from sandboxed evaluation scripts. Furthermore, experimental memory is managed via strict JSON state machines, and newly generated domain skills must pass automated validation and human peer review prior to repository promotion.
What are the operational limitations of this AutoResearch system?
The system is currently confined to workloads with clearly quantifiable target metrics, reversible code modifications, and controllable single-iteration compute costs. It also exhibits limitations in attribution explainability, and transferring learned skills across unrelated domains still carries hallucination risks requiring human verification.

