Why Local Large Language Models Underperform: An Analysis of Hardware and Software Inference Hazards
Local Large Language Model (LLM) users often find that models perform significantly worse than official benchmarks suggest. This discrepancy is not merely a result of quantization but stems from "implementation-specific hazards" during inference. According to technical insights from Level1Techs, the gap between a "reference implementation"—the original lab's environment—and a home lab setup is vast. Key factors include the use of diverse hardware, such as mixed GPU generations, which utilize different instruction sets. These variations lead to differences in how mathematical calculations for token generation are executed. Consequently, even when using identical model weights, the specific hardware and software configuration of a local system can fundamentally alter the model's output and perceived intelligence, making it feel "dumber" than its advertised capabilities.
Key Takeaways
- Implementation Discrepancy: Local LLM performance often fails to match "reference implementations" due to significant differences in hardware and software environments.
- Hardware Heterogeneity: Mixing different generations of GPUs in a home lab introduces varying instruction sets that execute mathematical operations differently.
- Mathematical Execution: The way a system calculates the "next token" is not universal; it depends on the specific instruction sets of the chips being used.
- Beyond Quantization: While users often focus on quantization (e.g., GGUF formats), the underlying hardware-software interaction is a primary source of performance degradation.
- Reference vs. Local: Original model benchmarks are established on specific, optimized lab hardware that is rarely replicated in local user environments.
In-Depth Analysis
The Reference Implementation Gap
A primary reason for the perceived "stupidity" of local LLMs is the departure from what is known as the "reference implementation." This term refers to the specific environment—both hardware and software—used by the original research lab that published the model and its corresponding benchmarks. When a lab claims a model is "amazing," those claims are backed by first-party hosting and specific hardware configurations that are optimized for that model's architecture.
For the average user, replicating this environment is nearly impossible. Most local users rely on third-party implementations, such as running quantized versions of models in tools like Ollama. The original news highlights that the software and hardware used by labs are "very different" from those found in a typical home lab. This gap creates a fundamental mismatch between the model's theoretical performance (the benchmark) and its practical performance on a local machine. The analysis suggests that the "suckiness" of a local implementation is a universal experience because almost no local setup perfectly mirrors the reference environment.
Hardware Instruction Sets and Token Calculation
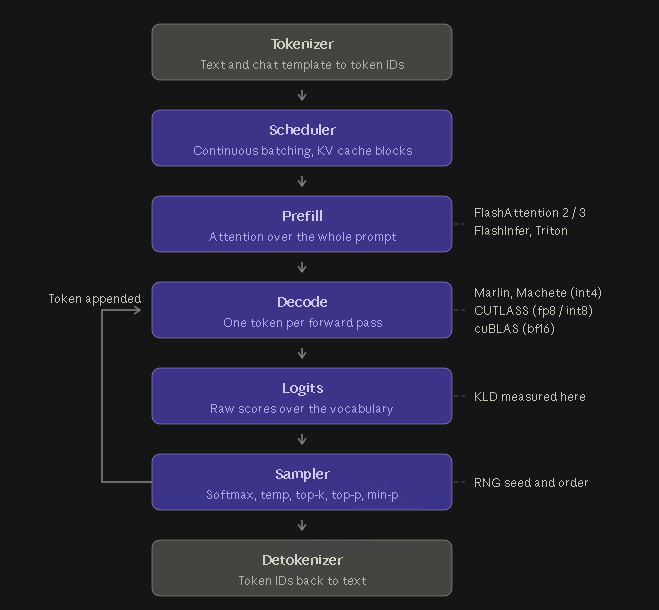
The technical core of the performance issue lies in the hardware's instruction sets. In a typical home lab, users often mix multiple generations of GPUs to maximize their available VRAM. However, these different chips do not process information in the same way. Each generation of GPU may have a unique instruction set that implements and executes the math required to calculate the next token differently from other hardware.
This variation means that even if two users are running the exact same model weights, their hardware might produce different results during the inference process. The math used to determine the probability of the next token is sensitive to these implementation-specific hazards. When the mathematical execution deviates from the reference implementation, the model's logic can appear flawed or "dumber." The author notes that these instruction sets are responsible for the actual execution of the math, and any variation at this level can lead to a cumulative loss of quality in the model's output.
Software and Inference Hazards
Beyond hardware, the software stack used for local inference introduces its own set of hazards. The original news points out that the software used in local setups is often "very different" from the lab-grade software used for original benchmarks. These implementation-specific hazards are not just about the speed of inference but the quality of the inference itself.
While the industry has seen a surge in research papers and emerging fields regarding LLM optimization, the practical reality for the user is often a simplified version of these technologies. The author intentionally glosses over the complex math and research to highlight a simple truth: the way your local software interacts with your specific hardware creates a unique environment that likely degrades the model's performance compared to its original state. This suggests that the "intelligence" of an LLM is not just a property of its weights, but a product of the entire stack it runs on.
Industry Impact
The realization that local LLM performance is heavily dependent on hardware-specific instruction sets has significant implications for the AI industry. It suggests that standardized benchmarks may be misleading for the average user, as they do not account for the hardware heterogeneity found in the wild. For the "home lab" community, this highlights a need for more robust testing methods that can measure how much a specific local setup deviates from the reference implementation.
Furthermore, this analysis shifts the focus from model weights and quantization alone to the importance of the inference engine and hardware compatibility. As the industry moves toward more localized AI, addressing these "implementation-specific hazards" will be crucial for ensuring that models remain as capable on consumer hardware as they are in the lab. It also underscores the difficulty in achieving deterministic results across different computing environments in the field of machine learning.
Frequently Asked Questions
Question: What is a "reference implementation" in the context of LLMs?
Answer: A reference implementation refers to the original hardware and software environment used by the research lab that developed and published the model. It is the setup used to establish the model's official benchmarks and performance claims.
Question: Why does mixing different GPU generations affect how an LLM performs?
Answer: Different GPU generations often have different instruction sets. These instruction sets determine how the hardware executes the mathematical calculations necessary to predict the next token. If the math is executed differently than in the reference implementation, the model's output quality can suffer.
Question: Is quantization the main reason why local LLMs feel "dumber"?
Answer: While quantization (like using 2.58-bit GGUF files) can impact performance, the original news suggests that implementation-specific hazards—such as hardware instruction sets and software differences—are significant factors that are often overlooked by the average user.