High-Quality Local Text-to-Speech with Kokoro: A CPU-Friendly Solution for Private AI Voice Synthesis
Kokoro is a compact yet powerful 82-million parameter text-to-speech (TTS) model designed for high-quality, realistic voice generation on local hardware. Unlike many modern AI models that require heavy GPU resources, Kokoro is optimized for CPU execution, allowing users to maintain privacy and save GPU power for other tasks like Large Language Model (LLM) inference. Supporting English, Mandarin, and Hindi with approximately 50 distinct voices, Kokoro offers a versatile solution for developers. It features a Kokoro-FastAPI container for easy deployment and maintains compatibility with the OpenAI speech API, making it a seamless drop-in replacement for existing applications. This breakthrough signifies a major step toward accessible, high-fidelity, and private speech synthesis without the need for cloud-based services.
Key Takeaways
- High Efficiency: Kokoro achieves realistic speech synthesis with a remarkably small footprint of only 82 million parameters.
- CPU-Optimized: Designed to run entirely on local CPUs, freeing up dedicated GPUs for other intensive tasks like LLM processing.
- Multilingual Support: Provides high-quality voice generation in English, Mandarin, and Hindi, featuring about 50 distinct voices.
- Seamless Integration: Fully compatible with the OpenAI speech API, allowing for easy adaptation of existing software and workflows.
- Privacy-Centric: Enables completely offline operation, ensuring that sensitive data never leaves the local machine.
In-Depth Analysis
The Shift to Local and Efficient Speech Synthesis
In recent years, the landscape of speech synthesis has undergone a dramatic transformation. Previously, generating realistic, human-like speech required significant computational power, often necessitating cloud-based solutions that raised concerns regarding data privacy and latency. The emergence of Kokoro represents a significant milestone in this evolution. Despite its relatively small size of 82 million parameters, the model delivers exceptional audio quality that rivals much larger counterparts.
One of the most compelling aspects of Kokoro is its hardware flexibility. While modern AI workflows often bottleneck at the GPU, Kokoro is specifically optimized for CPU-friendly execution. This allows users—such as those running local LLMs on hardware like a GTX 1080 Ti—to reserve their dedicated video memory for language processing while the CPU handles the speech synthesis. This parallel processing capability ensures a smoother user experience in complex AI applications without requiring a multi-GPU setup.
Deployment and Developer Accessibility
Kokoro is designed with ease of use in mind, catering to both individual enthusiasts and professional developers. The primary method for deployment is through the Kokoro-FastAPI container image. Although the image is somewhat large at approximately 5 GB—due to the inclusion of pre-downloaded voice models—it simplifies the setup process by eliminating complex dependency management. Using standard tools like Docker or Podman, users can launch a local TTS server with a single command.
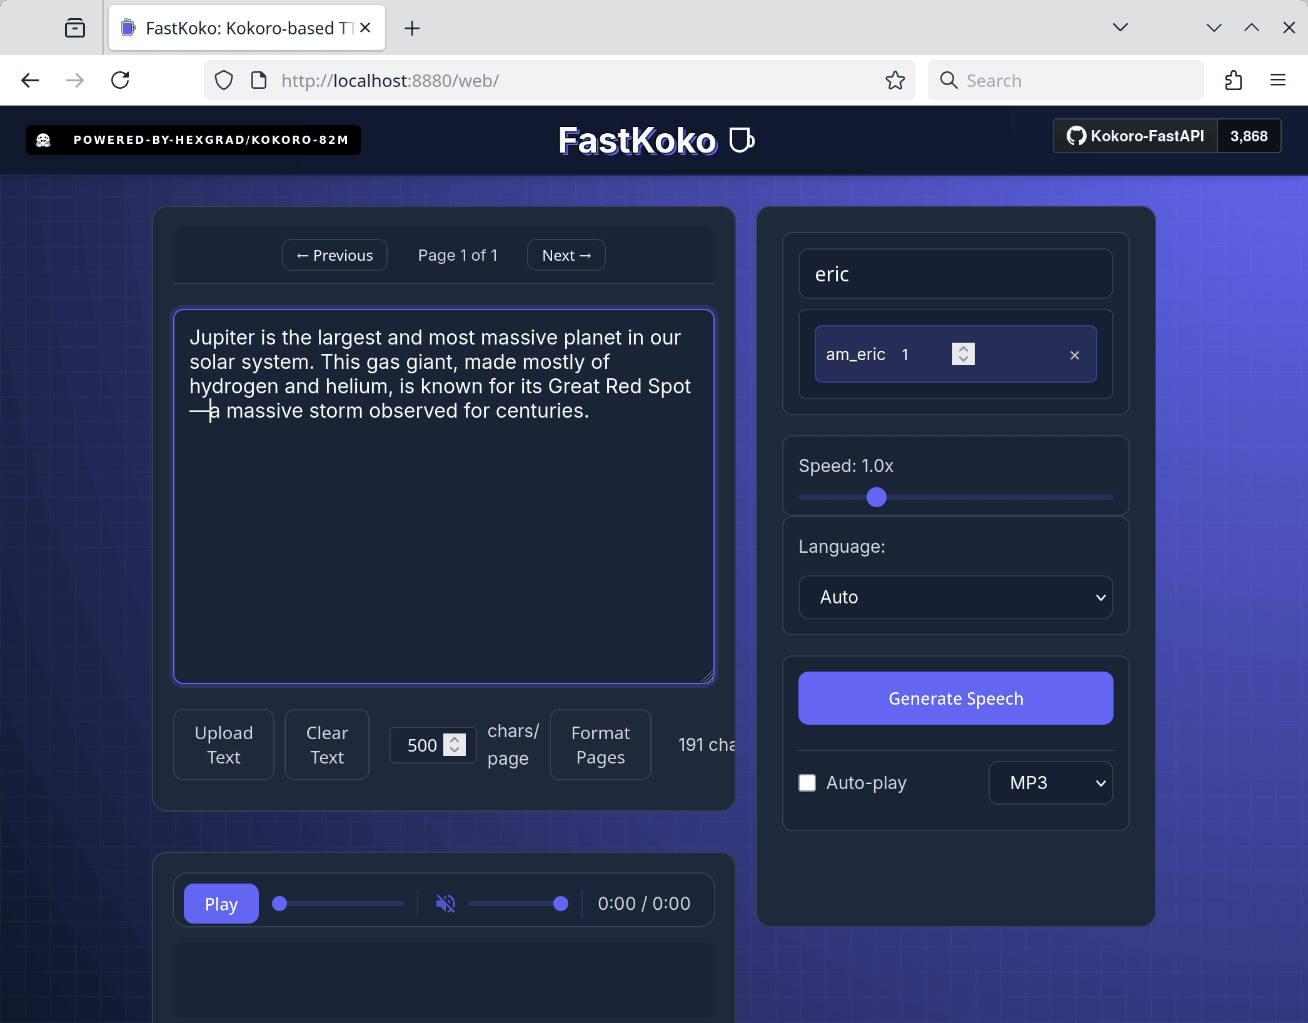
Beyond simple deployment, Kokoro offers a high degree of interoperability. By serving a TTS interface that is compatible with the OpenAI speech API, it functions as a drop-in replacement for developers who have already built applications around OpenAI's ecosystem. This compatibility, combined with available sample code in both JavaScript and Python, significantly lowers the barrier to entry for migrating from cloud-dependent services to local, private alternatives. The inclusion of a built-in web UI at the local host further allows for immediate verification and testing of the model's capabilities.
Industry Impact
Democratizing High-Fidelity TTS
The release and optimization of Kokoro have profound implications for the AI industry, particularly in the realm of accessibility. By proving that high-quality speech synthesis does not require massive parameter counts or high-end GPUs, Kokoro democratizes the technology. Small-scale developers and researchers can now integrate sophisticated voice interfaces into their projects using standard consumer-grade hardware. This shift reduces the reliance on expensive API subscriptions and cloud infrastructure, fostering innovation in the open-source community.
Privacy and the Future of Edge AI
As privacy becomes a paramount concern for users and enterprises alike, the ability to run high-performance models like Kokoro locally is a critical advantage. In sectors such as healthcare, legal, or personal assistance, where data sensitivity is high, local TTS ensures that spoken content remains confidential. Furthermore, Kokoro's success highlights a growing trend toward "Edge AI," where the goal is to move processing closer to the user. By supporting multiple languages like Mandarin and Hindi alongside English, Kokoro is well-positioned to serve a global market, pushing the boundaries of what is possible with local, CPU-based artificial intelligence.
Frequently Asked Questions
Question: Does Kokoro require a dedicated GPU to function?
No. While Kokoro can run on machines with GPUs, it is specifically designed to be CPU-friendly. This allows the GPU to be reserved for other tasks, such as running Large Language Models, while the CPU handles the speech synthesis without a significant loss in quality.
Question: What languages and voices are supported by Kokoro?
Kokoro currently supports English, Mandarin, and Hindi. It offers approximately 50 distinct voices, though the current optimization is primarily focused on English-speaking voices.
Question: How can I integrate Kokoro into my existing Python or JavaScript projects?
Kokoro is highly compatible with existing workflows because it serves an interface that matches the OpenAI speech API. Developers can use sample code provided in Python or JavaScript and simply point their API base URL to the local container address (e.g., http://127.0.0.1:8880/v1) to begin generating speech.