
Meituan Open-Sources LongCat-Next: A Native Multimodal Approach to Physical World AI
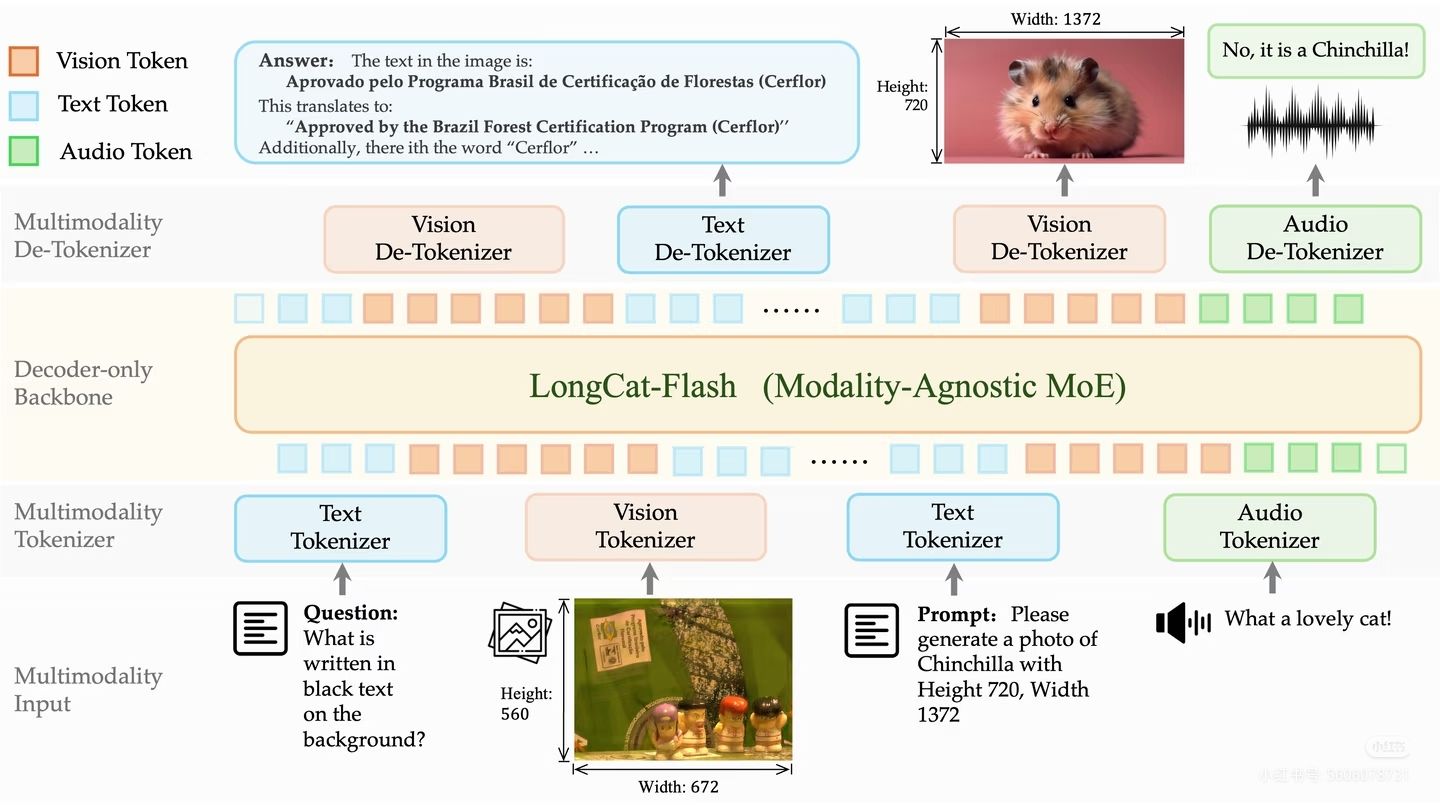
Meituan's technical team has officially announced the open-source release of LongCat-Next, a native multimodal model designed to bridge the gap between artificial intelligence and the physical world. By treating vision and speech as "native languages" rather than secondary inputs, LongCat-Next represents a significant shift in how AI perceives and interacts with its environment. In a move to support the broader developer community, Meituan has released both the core model and its specialized discrete tokenizer. This initiative aims to provide the foundational tools necessary for building AI systems that can truly perceive, understand, and act within real-world scenarios, marking a pivotal step in Meituan's exploration of embodied and physical-world AI technologies.
Key Takeaways
- Native Multimodality: LongCat-Next integrates vision and speech as core "native" languages, moving away from traditional models that treat non-text data as secondary or auxiliary inputs.
- Open Source Commitment: Meituan has open-sourced both the LongCat-Next model and its discrete tokenizer, encouraging community-driven development and innovation.
- Physical World Focus: The model is specifically designed as an exploration into "Physical World AI," focusing on the ability to perceive, understand, and act in real-world environments.
- Developer Empowerment: By providing the core research ideas and technical components, Meituan aims to enable developers to build more sophisticated AI that interacts with the tangible world.
In-Depth Analysis
The Shift to Native Multimodality
The release of LongCat-Next by the Meituan technical team highlights a significant evolution in multimodal AI architecture. The core philosophy behind this model is the treatment of vision and speech as "native languages." In many previous iterations of multimodal systems, AI models were primarily text-based, with visual or auditory data being converted or "translated" into a format the text model could understand. LongCat-Next seeks to eliminate this translation layer by building a framework where different modalities are processed natively. This approach is intended to allow the AI to maintain a more direct and nuanced understanding of visual and auditory signals, which is crucial for tasks that require high-fidelity interaction with the physical environment.
By focusing on vision and speech as foundational components, Meituan is positioning LongCat-Next as a tool for "Physical World AI." This concept refers to AI systems that are not confined to digital interfaces but are capable of navigating and interpreting the complexities of the real world. The ability to perceive and understand the physical world is a prerequisite for advanced applications in robotics, autonomous systems, and real-time environmental interaction, which are areas of significant interest for a technology company deeply embedded in physical services like Meituan.
Open Sourcing the Discrete Tokenizer
A critical aspect of the LongCat-Next announcement is the decision to open-source the model's discrete tokenizer alongside the model itself. In the context of multimodal AI, a tokenizer is the component responsible for breaking down complex data—such as images or audio waves—into discrete units that the neural network can process. By open-sourcing this specific component, Meituan is providing the community with the "key" to how LongCat-Next interprets the world.
The discrete tokenizer is essential for achieving the "native" multimodal processing described by the technical team. It allows the model to handle diverse data types within a unified framework. For developers, access to this tokenizer means they can not only use the pre-trained model but also understand and potentially refine the way the AI discretizes and perceives non-textual information. This level of transparency is aimed at fostering a deeper level of research and development, allowing others to build upon Meituan's foundational work in physical world perception.
Industry Impact
The release of LongCat-Next has several implications for the AI industry, particularly in the realm of open-source development and embodied AI. First, it challenges the industry to move toward more integrated multimodal architectures. As vision and speech become "native" to AI models, we can expect a decrease in the latency and information loss typically associated with multi-step data processing. This is vital for industries requiring real-time response, such as logistics, automated delivery, and smart infrastructure.
Furthermore, Meituan's decision to open-source such a core piece of their research infrastructure signals a trend toward collaborative development in the race for Physical World AI. By lowering the barrier to entry for high-quality multimodal perception tools, Meituan is likely to accelerate the pace of innovation in applications that require AI to "act" on the real world. This move not only strengthens Meituan's position as a technical leader in the AI space but also provides a robust platform for the next generation of developers focusing on the intersection of AI and physical reality.
Frequently Asked Questions
Question: What is the primary goal of the LongCat-Next project?
LongCat-Next is an exploration by the Meituan technical team into the development of "Physical World AI." Its primary goal is to create a model that can perceive, understand, and act upon the real world by treating vision and speech as native languages within the AI's architecture.
Question: What specific components has Meituan open-sourced?
Meituan has open-sourced the core LongCat-Next model as well as its discrete tokenizer. These components represent the core research ideas and technical foundations of their native multimodal approach.
Question: Why is the "native" treatment of vision and speech important?
Treating vision and speech as native languages allows the AI to process these modalities directly, rather than as secondary translations of text. This is intended to lead to more accurate perception and a better understanding of the physical world, which is essential for AI that needs to interact with real-world environments.