
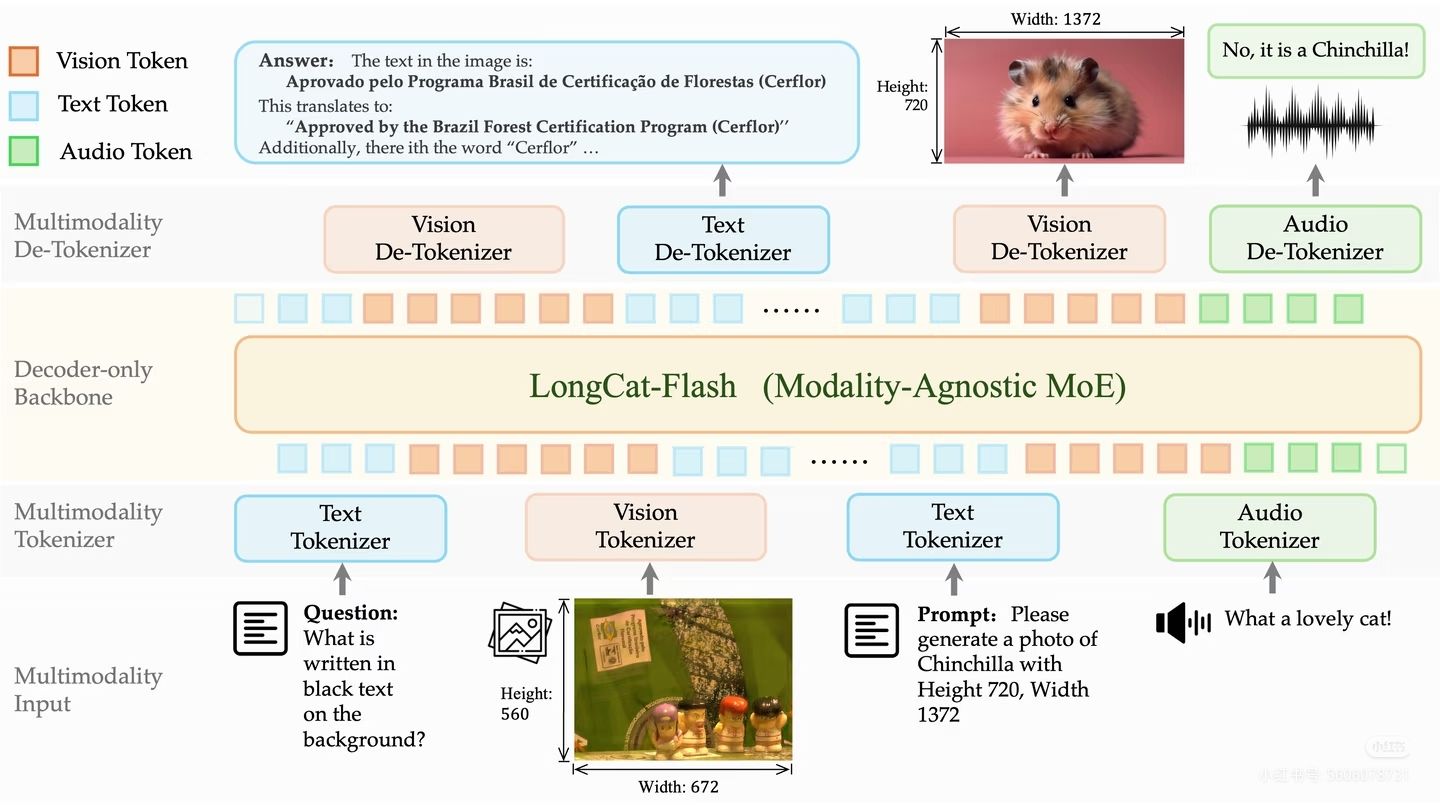
Meituan Open Sources LongCat-Next: A Native Multimodal Model for Physical World AI Perception
Meituan's technical team has officially announced the release and open-sourcing of LongCat-Next, a native multimodal model designed to advance AI's capabilities in the physical world. By treating vision and speech as native languages, the model aims to bridge the gap between digital intelligence and real-world interaction. The release includes both the core LongCat-Next model and its specialized discrete tokenizer, providing developers with the essential tools to build systems that can perceive, understand, and act within physical environments. This strategic move highlights Meituan's commitment to embodied AI research and its effort to foster a collaborative ecosystem for next-generation multimodal applications.
Key Takeaways
- Open-Source Release: Meituan has made the LongCat-Next model and its discrete tokenizer available to the global developer community.
- Native Multimodality: The model is designed to treat vision and speech as "native languages," moving beyond traditional text-centric AI architectures.
- Physical World Focus: The primary objective of LongCat-Next is to enable AI to perceive, understand, and interact with the real, physical world.
- Developer Empowerment: By sharing the core research ideas and tools, Meituan aims to facilitate the creation of AI that can act upon real-world environments.
In-Depth Analysis
Advancing AI Toward Physical World Interaction
The introduction of LongCat-Next represents a significant shift in Meituan's AI research strategy, moving from purely digital information processing toward what the team describes as "physical world AI." The core philosophy behind LongCat-Next is to enable artificial intelligence to move beyond the constraints of text-based understanding. By integrating vision and speech as native components of the model's architecture, Meituan is addressing the fundamental challenge of how AI perceives its surroundings. The goal is not merely to process data but to create a system that can "perceive, understand, and act" in a way that is meaningful within a physical context. This suggests a focus on embodied AI, where the model's intelligence is directly applicable to real-world tasks and environmental navigation.
The Strategic Importance of the Discrete Tokenizer
A critical component of this release is the open-sourcing of the discrete tokenizer alongside the LongCat-Next model. In the context of multimodal AI, a tokenizer is the bridge that converts raw sensory data—such as images or audio—into a format that the model can process. By providing a discrete tokenizer specifically designed for this native multimodal approach, Meituan is offering the community the "core research idea" behind their breakthrough. This allows developers to understand how the model discretizes complex visual and auditory signals into a unified language that the AI can interpret. The availability of this tool is essential for researchers looking to replicate Meituan's results or build specialized applications that require high-fidelity perception of the physical world.
Open Source as a Catalyst for Multimodal Innovation
By choosing to open-source LongCat-Next, Meituan is positioning itself as a key contributor to the evolving landscape of multimodal AI. The technical team explicitly stated their hope that developers will use these tools to build AI that can "truly perceive" the real world. This open-source approach serves two purposes: it accelerates the pace of innovation by allowing the global community to refine and expand upon the model, and it establishes Meituan's technical framework as a potential standard for physical world AI. The focus on "native" vision and speech suggests that LongCat-Next is built from the ground up to handle these inputs, rather than relying on external translation layers, which could lead to more efficient and responsive AI systems.
Industry Impact
The release of LongCat-Next is poised to influence the AI industry in several ways. First, it pushes the boundaries of multimodal research by emphasizing the importance of "native" integration of non-textual data. As the industry moves toward more complex robotics and autonomous systems, the ability for AI to understand vision and speech as primary languages becomes a competitive necessity. Second, Meituan's decision to open-source the tokenizer lowers the barrier to entry for other companies and independent researchers working on embodied AI. This could lead to a surge in applications related to smart logistics, autonomous delivery, and real-world assistance, where AI must navigate and interact with physical spaces. Finally, this move reinforces the trend of major tech companies contributing core research to the open-source community to drive collective progress in the field of artificial general intelligence (AGI).
Frequently Asked Questions
Question: What is the primary goal of Meituan's LongCat-Next?
The primary goal of LongCat-Next is to explore the path toward "physical world AI." It is designed to enable artificial intelligence to perceive, understand, and act within the real world by treating vision and speech as its native languages.
Question: What specific components have been open-sourced by the Meituan Technical Team?
Meituan has open-sourced the core LongCat-Next model and its accompanying discrete tokenizer. These tools represent the core research ideas behind their approach to native multimodal AI.
Question: Why is the "native" aspect of vision and speech important for this model?
By making vision and speech "native" to the model, LongCat-Next can process these inputs directly rather than treating them as secondary data types. This is intended to create a more integrated and effective understanding of the physical world, similar to how humans perceive their environment.