Meituan LongCat Team Unveils WBench: The First Systematic Multi-Round Benchmark for Interactive Video World Models
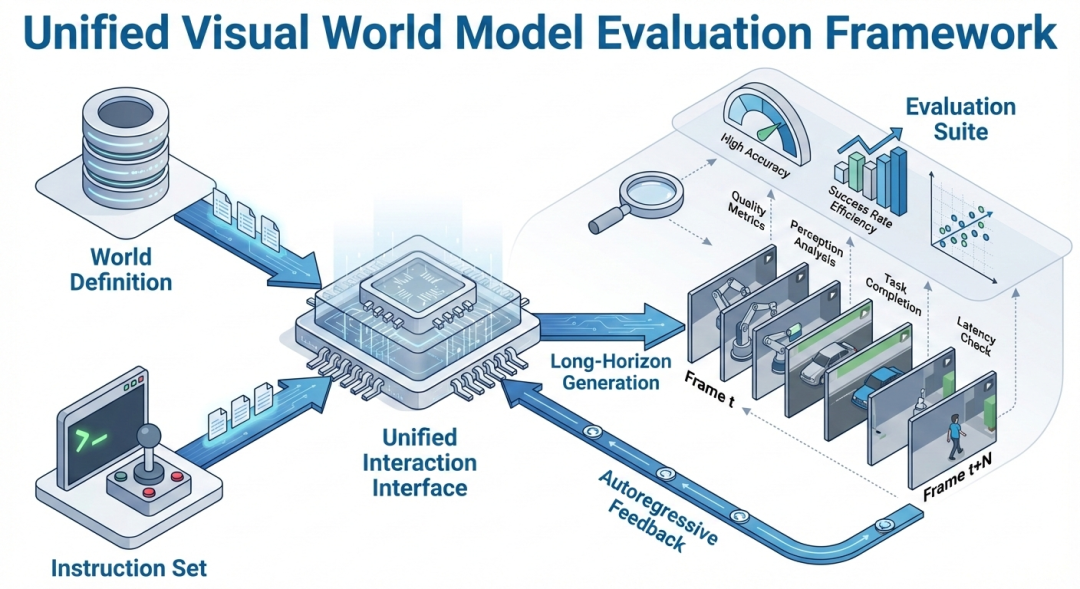
The Meituan LongCat team has announced the release and open-sourcing of WBench, a pioneering systematic multi-round evaluation benchmark specifically designed for interactive video world models. Positioned as a diagnostic "CT scanner" for AI, WBench aims to provide precise insights into the technical bottlenecks that occur during the transition from passive video generation to active user interaction. By evaluating models across diverse scenarios—ranging from lunar walks to futuristic cyber cities—WBench addresses the critical need for standardized metrics in the evolving field of world models. This benchmark represents a significant step in identifying where current AI systems struggle to maintain consistency and logic during complex, multi-stage interactive sequences, offering a roadmap for future development in the industry.
Key Takeaways
- Introduction of WBench: Meituan's LongCat team has developed and open-sourced WBench, the first systematic benchmark for interactive video world models.
- Diagnostic Capabilities: The tool acts as a "CT scanner," providing a high-precision diagnosis of where world models fail during the shift from passive observation to active interaction.
- Multi-Round Evaluation: Unlike traditional single-step assessments, WBench focuses on multi-round interactions to test the sustained logic and consistency of AI environments.
- Broad Evaluative Scope: The benchmark covers a wide range of simulated environments, from "moonwalks" to "cyber cities," testing the boundaries of current world model capabilities.
In-Depth Analysis
Bridging the Gap: From Passive Viewing to Active Interaction
The development of world models has reached a critical juncture where the focus is shifting from merely generating realistic video content to creating environments that can be interacted with dynamically. Meituan's LongCat team identifies this transition as the move from "passive viewing" to "active interaction." In a passive setup, a model might generate a high-quality video of a lunar landscape or a bustling city, but the user remains an observer.
However, the next generation of AI requires these models to function as true "world models"—systems that can respond to user inputs and maintain environmental consistency over time. WBench is specifically designed to measure this capability. By analyzing how a model handles multi-round interactions, the benchmark reveals whether the AI can maintain the physical laws and spatial logic of its generated world when subjected to external changes. This transition is where many current models encounter significant hurdles, and WBench provides the framework to identify these specific points of failure.
The "CT Scanner" Approach to AI Evaluation
The LongCat team describes WBench as a "CT scanner" for world models, a metaphor that underscores the benchmark's diagnostic precision. Traditional evaluation methods often provide a surface-level score that indicates whether a model is "good" or "bad" but fails to explain why a model fails in specific interactive contexts.
WBench changes this by systematically probing the model's performance across multiple rounds of interaction. This "scanning" process allows developers to see exactly where the model's internal logic breaks down. For instance, a model might successfully generate the first few frames of a "cyber city" but lose track of object permanence or spatial relationships after several rounds of user-driven changes. By pinpointing these specific "bottlenecks," WBench enables researchers to move beyond trial-and-error development and toward targeted improvements in model architecture and training data.
Industry Impact
The release of WBench carries significant implications for the AI industry, particularly for teams working on autonomous systems, gaming, and virtual simulations. As the first systematic multi-round benchmark for interactive video world models, it establishes a new standard for how these complex systems should be measured.
By open-sourcing WBench, Meituan is providing the global research community with a tool to harmonize evaluation metrics. This transparency is crucial for the industry to move past the "black box" nature of current world models. Furthermore, the focus on multi-round interaction sets a higher bar for AI performance, pushing the field toward creating more robust, reliable, and interactive virtual environments. As AI continues to integrate into physical and digital interactive spaces, benchmarks like WBench will be essential for ensuring that these "worlds" behave predictably and logically.
Frequently Asked Questions
Question: What is WBench and who developed it?
WBench is the first systematic multi-round evaluation benchmark for interactive video world models. It was developed and open-sourced by the Meituan LongCat team to help diagnose the limitations of current AI world models.
Question: Why is the "multi-round" aspect of WBench important?
Multi-round evaluation is critical because it tests a model's ability to maintain consistency and logic over a series of interactions. While many models can generate a single realistic video clip, maintaining that realism during active, multi-step interaction is a much greater technical challenge that WBench is designed to measure.
Question: What does the "CT scanner" metaphor signify in the context of WBench?
The metaphor signifies WBench's ability to perform a deep, precise diagnosis of a world model's internal failures. Just as a medical CT scanner identifies issues deep within a body, WBench identifies exactly where a model's logic or consistency fails during the transition from passive viewing to active interaction.