
Meituan Open-Sources LongCat-Next: A Native Multimodal Model Integrating Vision and Voice for Physical World AI
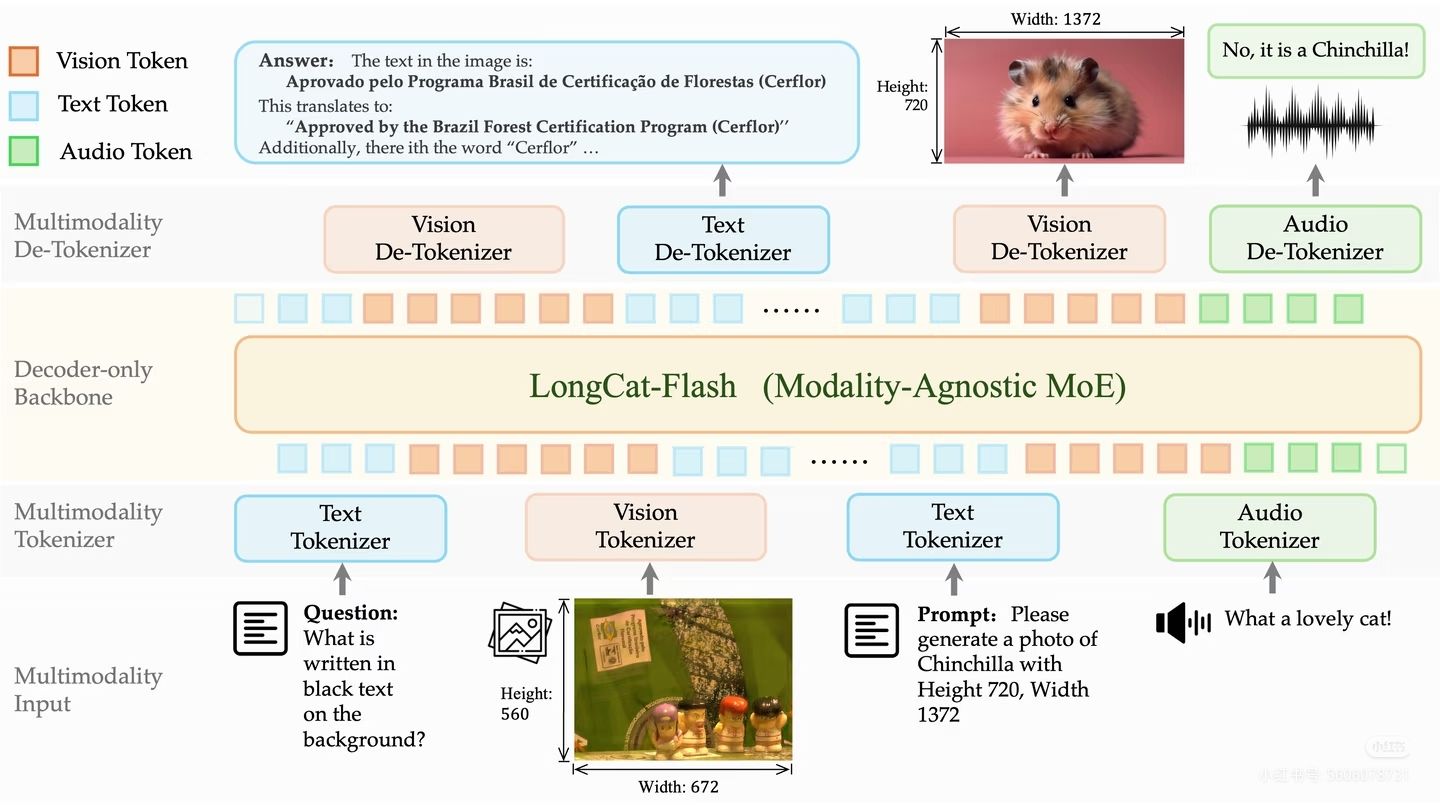
Meituan's technical team has officially announced the release and open-sourcing of LongCat-Next, a native multimodal AI model designed to bridge the gap between digital intelligence and the physical world. By treating vision and voice as "native languages," the model represents a significant step in Meituan's exploration of embodied AI. Alongside the core model, Meituan has also open-sourced its discrete tokenizer, providing the developer community with the essential tools needed to build systems that can perceive, understand, and interact with real-world environments. This move highlights Meituan's commitment to fostering an open-source ecosystem for advanced multimodal research, aiming to empower developers to create AI applications that function effectively within the complexities of the physical world.
Key Takeaways
- Native Multimodal Integration: LongCat-Next is designed to treat vision and voice as native modalities, moving beyond traditional text-centric AI frameworks.
- Open-Source Contribution: Meituan has released both the LongCat-Next model and its core discrete tokenizer to the global developer community.
- Physical World Focus: The project is a primary exploration into "Physical World AI," focusing on the ability of models to perceive and act in real environments.
- Developer Empowerment: By providing these tools, Meituan aims to enable the creation of AI that can truly understand and interact with the tangible world.
In-Depth Analysis
The Vision of Native Multimodality
The release of LongCat-Next by the Meituan technical team marks a strategic pivot toward native multimodality. In the current AI landscape, many models process visual or auditory information as secondary inputs that are translated into text-based representations. However, LongCat-Next is described as a model where vision and voice become the "native language" of the AI. This approach suggests a more integrated architecture where different sensory inputs are processed with the same level of priority and structural depth as text. By developing a system that inherently understands these modalities, Meituan is laying the groundwork for AI that does not just "see" or "hear" as an add-on feature, but uses these senses as fundamental components of its reasoning process.
Bridging AI and the Physical World
A central theme of the LongCat-Next announcement is the transition from digital-only intelligence to AI that operates within the physical world. Meituan characterizes this model as an exploration into the path toward physical world AI. The stated goal is to build systems capable of three core functions: perception, understanding, and action. While many large language models excel at understanding and generating text, they often lack the grounding required to interact with physical objects or navigate real-world spaces. LongCat-Next aims to fill this gap. By open-sourcing the model and its discrete tokenizer, Meituan is inviting the industry to solve the challenges of embodiment—where AI must interpret complex visual scenes and auditory cues to perform tasks in the real world, such as delivery services, robotics, or interactive hardware.
The Significance of the Discrete Tokenizer
One of the most technical aspects of this release is the open-sourcing of the discrete tokenizer. In multimodal models, tokenizers are the critical components that break down continuous data—like images or sound waves—into discrete units that the model can process. By sharing this specific tool, Meituan is providing the community with the "dictionary" that LongCat-Next uses to interpret the world. This allows developers to understand how the model discretizes visual and auditory information, which is essential for fine-tuning, extending the model's capabilities, or integrating it into specialized hardware. The availability of the tokenizer ensures that the research community can build upon Meituan's foundational work with a high degree of transparency and technical compatibility.
Industry Impact
The decision to open-source LongCat-Next has several implications for the AI industry. First, it accelerates the development of embodied AI by providing a high-quality starting point for researchers who may not have the resources to train native multimodal models from scratch. Second, it positions Meituan as a key contributor to the open-source ecosystem, potentially setting a standard for how vision and voice should be integrated into large-scale models. As the industry moves toward more sophisticated robotics and automated services, models like LongCat-Next that prioritize real-world perception will become increasingly vital. This release encourages a shift in the developer community from purely generative text applications toward more practical, action-oriented AI solutions that can navigate the complexities of the physical environment.
Frequently Asked Questions
Question: What specific components did Meituan open-source?
Answer: Meituan has open-sourced the core LongCat-Next model and its accompanying discrete tokenizer, which is used to process multimodal data.
Question: What does "native multimodal" mean in the context of LongCat-Next?
Answer: It refers to the model's ability to treat vision and voice as primary, fundamental languages rather than secondary inputs, allowing for more direct and integrated perception of the physical world.
Question: What is the ultimate goal of the LongCat-Next project?
Answer: The goal is to explore the path toward physical world AI, enabling developers to build systems that can perceive, understand, and act within real-world scenarios.