Meituan LongCat Team Unveils WBench: The First Systematic Multi-Round Benchmark for Interactive Video World Models
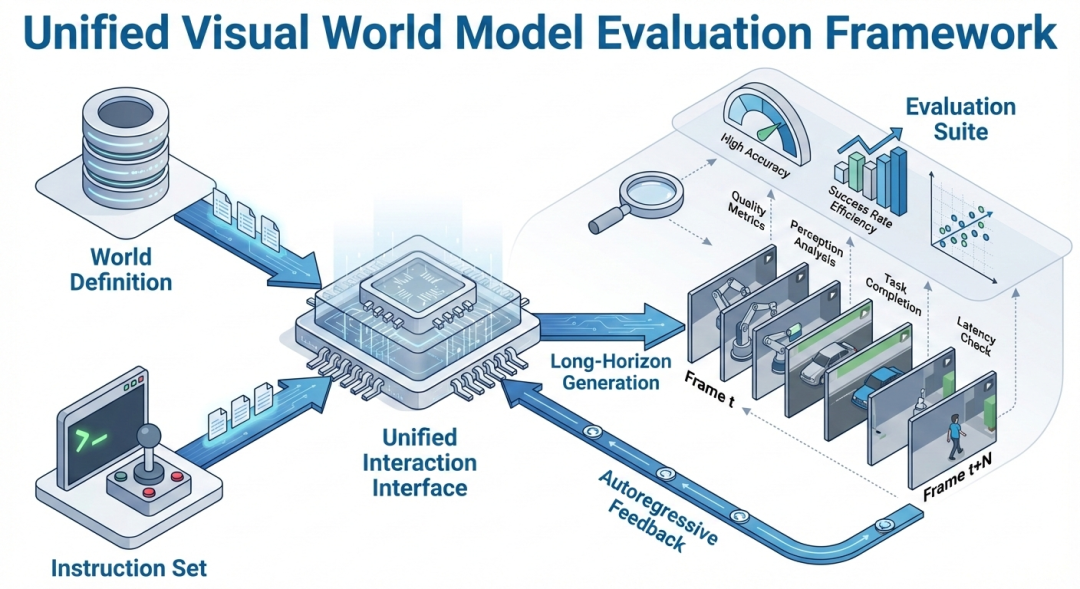
The Meituan LongCat team has officially introduced and open-sourced WBench, a groundbreaking systematic multi-round evaluation benchmark designed specifically for interactive video world models. Positioned as a diagnostic 'CT scanner' for artificial intelligence, WBench is engineered to precisely identify the technical limitations and performance bottlenecks encountered by world models as they transition from passive observation to active interaction. By evaluating models across diverse scenarios—ranging from lunar environments to complex cybernetic cities—WBench provides a framework for measuring how AI navigates the boundaries of simulated reality. This open-source initiative aims to standardize the assessment of interactive capabilities, offering the research community a vital tool to refine how AI systems perceive, simulate, and respond to dynamic, multi-stage user interactions within virtual environments.
Key Takeaways
- Pioneering Benchmark: WBench is the first systematic, multi-round evaluation framework specifically designed for interactive video world models.
- Diagnostic Precision: The tool acts as a "CT scanner," allowing researchers to pinpoint exactly where models fail during the transition from passive viewing to active interaction.
- Open-Source Contribution: Developed by Meituan's LongCat team, the benchmark has been open-sourced to foster industry-wide advancement in world model development.
- Focus on Interaction: Unlike traditional benchmarks, WBench emphasizes multi-round interactions, testing the consistency and responsiveness of AI in simulated environments like lunar landscapes and urban centers.
In-Depth Analysis
Bridging the Gap Between Observation and Agency
The development of world models has traditionally focused on "passive viewing," where AI systems are trained to predict or generate video sequences based on static datasets. However, the Meituan LongCat team identifies a critical boundary in current technology: the shift toward "active interaction." WBench is designed to explore this frontier, measuring how effectively a model can maintain a coherent world state when subjected to user-driven changes. By testing models in varied settings—from the low-gravity physics of a "moonwalk" to the dense, high-complexity data of a "cyber city"—WBench evaluates whether an AI can truly simulate a world that reacts logically to external inputs over multiple rounds of engagement.
The "CT Scanner" Approach to AI Evaluation
One of the most significant aspects of WBench is its role as a diagnostic tool. The LongCat team describes it as a "CT scanner" for world models, a metaphor that highlights its ability to look beneath the surface of a model's output. While a model might produce a visually impressive single-round video, WBench's systematic multi-round testing reveals where the underlying logic begins to fracture. This diagnostic capability is essential for identifying specific "stuck points"—technical bottlenecks where the model loses spatial consistency, temporal coherence, or interactive responsiveness. By providing this level of granular feedback, WBench allows developers to move beyond general performance metrics and focus on solving specific structural weaknesses in their world models.
Systematic Multi-Round Interaction Framework
At the core of WBench is its focus on multi-round evaluation. In a real-world or highly interactive virtual scenario, an agent must make a series of decisions, each affecting the subsequent state of the environment. WBench simulates this complexity by requiring models to sustain their internal logic across several iterations of interaction. This approach tests the limits of a model's memory and its ability to maintain a stable "world state." The benchmark's ability to measure these boundaries is crucial for the next generation of AI applications, where consistency over time is just as important as the immediate visual quality of the simulation.
Industry Impact
The introduction of WBench marks a significant milestone for the AI industry, particularly in the field of generative video and world modeling. By providing an open-source, systematic benchmark, Meituan is helping to standardize how "interactivity" is measured—a metric that has previously been difficult to quantify. This standardization is likely to accelerate the development of more robust AI agents capable of operating in complex, dynamic environments. Furthermore, by open-sourcing the tool, the LongCat team encourages a collaborative approach to overcoming the current boundaries of world models, potentially leading to breakthroughs in robotics, autonomous systems, and immersive virtual simulations. WBench provides the necessary infrastructure for the industry to move from creating "videos that look real" to "worlds that act real."
Frequently Asked Questions
What is WBench and who developed it?
WBench is the first systematic multi-round evaluation benchmark for interactive video world models. It was developed and open-sourced by the LongCat team within the Meituan Technology Team.
Why is WBench compared to a "CT scanner"?
It is compared to a CT scanner because it is designed to perform a deep, diagnostic analysis of world models. It identifies the specific technical points where a model fails or gets "stuck" when trying to transition from passive observation to active, multi-round interaction.
What types of environments does WBench use for testing?
According to the LongCat team, WBench tests models across diverse and challenging scenarios, including lunar simulations ("moonwalk") and complex urban environments ("cyber city"), to measure the boundaries of their interactive capabilities.