
Meituan LongCat-AudioDiT: Breaking Zero-Shot TTS Limits via Direct Waveform Latent Space Diffusion
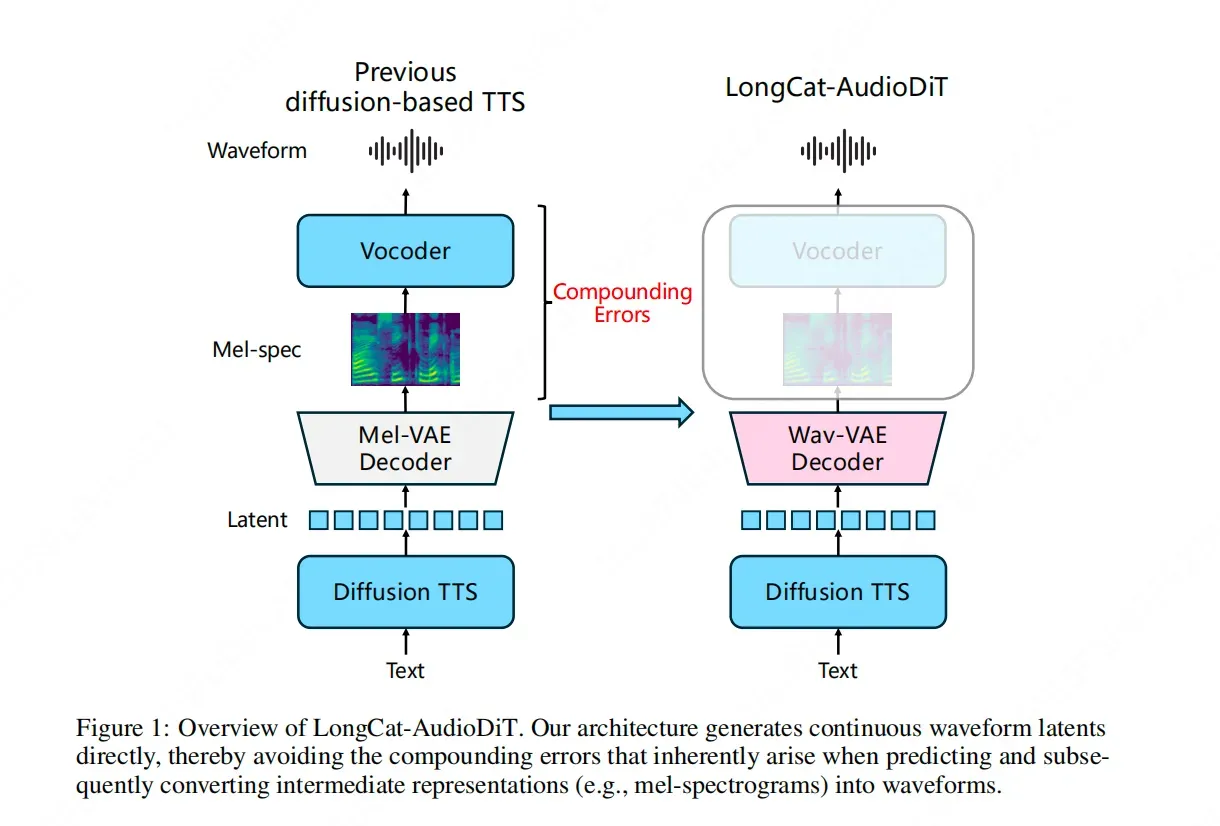
The Meituan LongCat team has officially released LongCat-AudioDiT, a groundbreaking model designed to push the boundaries of zero-shot Text-to-Speech (TTS) and voice cloning. By fundamentally reimagining the audio synthesis pipeline, the team has moved away from traditional intermediate representations such as Mel-spectrograms. Instead, LongCat-AudioDiT operates directly within the waveform latent space using a diffusion-based architecture. This strategic shift is designed to eliminate the cascade errors typically caused by multi-stage data conversions. By allowing the AI to learn the inherent patterns of sound directly, the model aims to achieve a higher level of fidelity and accuracy in voice cloning, providing a more streamlined and robust solution for high-quality audio generation.
Key Takeaways
- Elimination of Intermediate Steps: LongCat-AudioDiT abandons traditional Mel-spectrograms to prevent cascade errors during the audio synthesis process.
- Direct Waveform Latent Space: The model operates directly within the waveform latent space, allowing the AI to learn the fundamental laws of sound.
- Diffusion-Based Architecture: It utilizes a Diffusion Transformer (AudioDiT) approach to handle text-to-speech tasks.
- Zero-Shot Breakthrough: The primary goal is to overcome existing technical bottlenecks in zero-shot voice cloning and improve cloning accuracy.
In-Depth Analysis
Moving Beyond Mel-Spectrograms to Reduce Cascade Errors
In traditional Text-to-Speech (TTS) systems, the process is often divided into multiple stages, typically involving the generation of an intermediate representation like a Mel-spectrogram before converting that representation into an actual audio waveform. However, the Meituan LongCat team identified this multi-stage approach as a significant technical bottleneck. Each conversion step introduces the potential for "cascade errors," where inaccuracies in the first stage are magnified in the second, leading to a loss of fidelity in the final voice output.
LongCat-AudioDiT addresses this by completely discarding these intermediate representations. By removing the need for Mel-spectrograms, the model effectively blocks the source of these cumulative errors. This architectural simplification ensures that the transition from text to sound is more direct, preserving the integrity of the vocal characteristics and resulting in a more authentic voice clone.
Learning the Laws of Sound in Waveform Latent Space
The core innovation of LongCat-AudioDiT lies in its ability to let the AI directly learn the underlying patterns and laws of sound itself. Rather than relying on human-defined features or compressed spectral data, the model functions within the waveform latent space. This allows the system to capture the nuances of audio that are often lost in translation when using traditional methods.
By employing a diffusion-based model (AudioDiT), the system can iteratively refine the audio generation process within this latent space. This method allows the AI to "skip the middle steps" and focus on the relationship between text inputs and the resulting sound waves. The result is a model that can perform zero-shot voice cloning—replicating a voice it has never seen before—with a level of precision that was previously difficult to achieve due to the limitations of data conversion and representation.
Industry Impact
The introduction of LongCat-AudioDiT marks a significant shift in how the industry approaches voice synthesis. By proving that direct waveform latent space diffusion is a viable and superior alternative to Mel-spectrogram-based pipelines, Meituan is setting a new standard for high-fidelity audio generation. This breakthrough is particularly impactful for the field of zero-shot voice cloning, where the ability to replicate a voice from a very small sample is highly sought after.
For the broader AI industry, this research highlights the importance of reducing architectural complexity to minimize error propagation. As AI models become more integrated into consumer products—from virtual assistants to content creation tools—the demand for natural, error-free voice synthesis will only grow. LongCat-AudioDiT provides a technical roadmap for achieving these goals by focusing on the fundamental properties of sound rather than intermediate approximations.
Frequently Asked Questions
Question: What makes LongCat-AudioDiT different from traditional TTS models?
Traditional TTS models usually convert text into a Mel-spectrogram first and then use a separate vocoder to turn that spectrogram into sound. LongCat-AudioDiT skips this intermediate step and generates audio directly in the waveform latent space to avoid errors.
Question: How does this model improve zero-shot voice cloning?
By operating directly on the waveform latent space and using diffusion models, LongCat-AudioDiT can more accurately capture and replicate the unique patterns of a voice without the data loss associated with traditional conversion methods, making it more effective at cloning voices it hasn't been specifically trained on.
Question: What are "cascade errors" in the context of audio synthesis?
Cascade errors occur when a mistake or loss of detail in one part of a multi-step process (like converting text to a spectrogram) is carried over and worsened in the next step (like converting that spectrogram to audio). LongCat-AudioDiT eliminates these by using a more direct, single-pathway approach.

