
LARYBench Released: Redefining Embodied AI Action Representation Through Large-Scale Human Video Learning
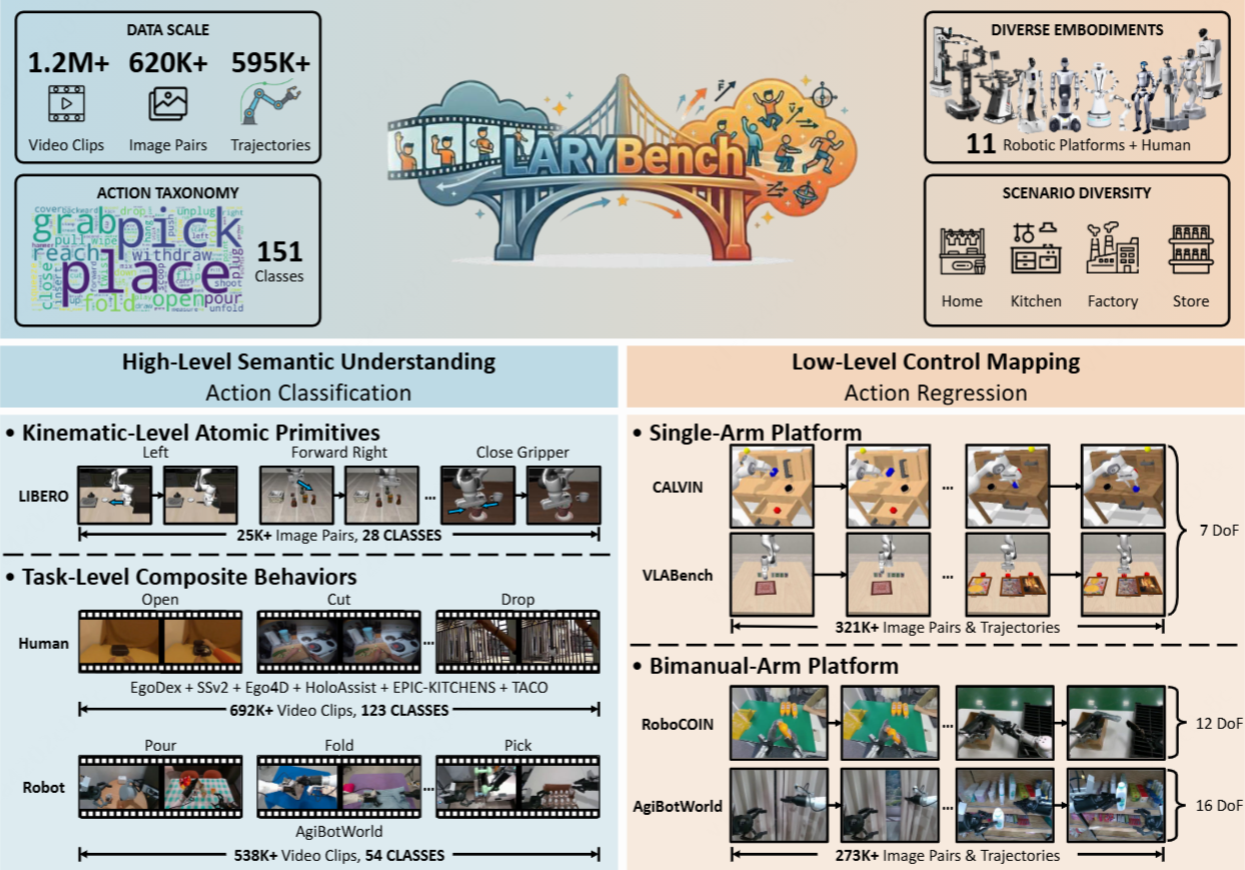
The Meituan Technical Team has officially released LARYBench (Latent Action Representation Yielding Benchmark), a systematic evaluation framework designed to measure general latent action representations derived from large-scale visual data. This benchmark marks a significant milestone in embodied intelligence, often compared to the 'ImageNet' moment for action representation. The research findings reveal a paradigm shift: general-purpose vision models significantly outperform specialized embodied expert models in both action generalization and control precision. Crucially, the study demonstrates that embodied action representations can spontaneously emerge from large-scale human video data, providing a new pathway for developing more capable and generalized robotic systems without relying solely on specialized datasets.
Key Takeaways
- Introduction of LARYBench: A new systematic evaluation benchmark designed to guide the learning of general latent action representations from large-scale visual data.
- Superiority of General Models: Experimental results show that general vision models outperform specialized embodied expert models in action generalization and control precision.
- Emergence from Human Videos: The benchmark proves that embodied action representations can successfully emerge from large-scale human video datasets.
- Standardizing Embodied AI: LARYBench aims to serve as the 'ImageNet' for the field of embodied action representation, providing a first-of-its-kind measurement for generalization.
In-Depth Analysis
The Framework of LARYBench
LARYBench, or the Latent Action Representation Yielding Benchmark, represents a systematic approach to one of the most challenging aspects of embodied AI: how to learn and evaluate action representations that are not tied to a single specific task. By focusing on "latent action representation," the benchmark shifts the focus from direct end-to-end task completion to the underlying features that allow a model to understand and execute movements. This systematic evaluation is essential for identifying models that can truly generalize across different environments and physical embodiments.
According to the Meituan Technical Team, the benchmark is designed to guide the industry toward learning from large-scale visual data. This is a departure from traditional methods that often rely on small, highly curated robotic datasets. By establishing a standardized metric, LARYBench allows researchers to quantify the effectiveness of different visual pre-training strategies in the context of physical action.
General Vision Models vs. Specialized Experts
A core finding of the LARYBench evaluation is the performance gap between general-purpose vision models and specialized embodied action expert models. Traditionally, the industry has leaned toward building "expert" models—architectures specifically tuned for robotic control and embodied tasks. However, the LARYBench results indicate that general vision models, which are trained on broader and more diverse visual datasets, possess a superior ability to generalize actions.
This superiority is manifested in two critical metrics: action generalization and control precision. Action generalization refers to the model's ability to apply learned representations to new, unseen scenarios, while control precision relates to the accuracy of the physical execution. The fact that general models excel in these areas suggests that the rich, diverse features learned from general visual data are more beneficial for embodied intelligence than the narrow, task-specific features learned by specialized expert models.
The Role of Human Video Data
Perhaps the most significant revelation from the LARYBench release is the confirmation that embodied action representations can emerge from large-scale human video data. This finding addresses a major bottleneck in robotics: the scarcity of high-quality robotic interaction data. If models can learn the fundamental representations of action by observing humans in videos, the potential for scaling embodied AI increases exponentially.
The benchmark provides the first formal measurement of this generalization representation learned from human videos. It validates the hypothesis that the visual patterns of human movement contain sufficient information to inform the latent action spaces of AI agents. This emergence suggests that the future of embodied AI may lie in leveraging the vast repositories of human video content available globally, rather than relying solely on physical robot trials.
Industry Impact
The release of LARYBench is poised to have a profound impact on the AI and robotics industry. By defining an "ImageNet" for embodied action, it provides a common language and a clear target for researchers worldwide. This standardization is likely to accelerate the development of general-purpose robots that can function in diverse human environments.
Furthermore, the discovery that general vision models are more effective than specialized experts may lead to a reallocation of research resources. We can expect an increased focus on large-scale visual pre-training and the integration of diverse video data into the training pipelines for embodied agents. This shift could lower the barrier to entry for developing sophisticated robotic controls, as the reliance on expensive, specialized hardware data decreases in favor of abundant visual information.
Frequently Asked Questions
Question: What is the primary goal of the LARYBench system?
LARYBench is designed to be a systematic evaluation benchmark that guides the learning of general latent action representations from large-scale visual data, specifically for the field of embodied AI.
Question: Why are general vision models performing better than specialized expert models?
According to the research, general vision models show significantly better performance in action generalization and control precision. This suggests that the broad visual features learned from diverse data are more robust and adaptable for embodied tasks than the narrow features found in specialized expert models.
Question: How does LARYBench utilize human video data?
LARYBench provides a way to measure how embodied action representations emerge from large-scale human video data. It demonstrates that models can learn generalized representations of action by observing human movements, which can then be applied to embodied intelligence tasks.

