
Meituan Open Sources LongCat-Next: A Native Multimodal Model Designed for Vision and Speech Integration in Physical World AI
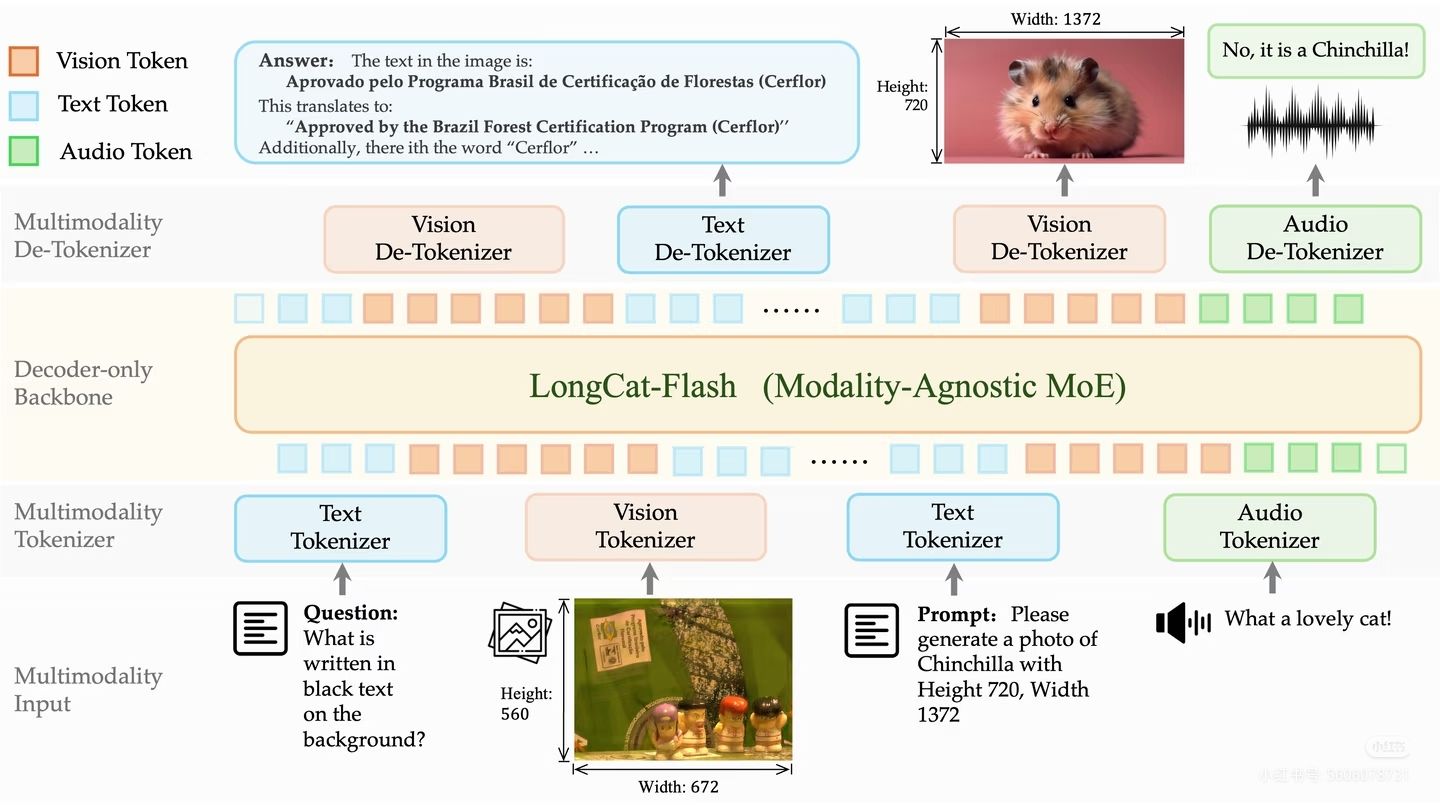
Meituan's technology team has officially announced the release and open-sourcing of LongCat-Next, a groundbreaking native multimodal model. This initiative represents a strategic move toward developing AI capable of navigating and interacting with the physical world. Unlike traditional models that treat non-text data as secondary, LongCat-Next integrates vision and speech as "native languages," allowing for more seamless perception and understanding. By open-sourcing the model alongside its discrete tokenizer, Meituan aims to empower the global developer community to build sophisticated AI systems that can perceive, comprehend, and act within real-world environments. This release underscores Meituan's commitment to advancing multimodal intelligence and fostering an open ecosystem for physical-world AI applications.
Key Takeaways
- Native Multimodal Integration: LongCat-Next treats vision and speech as "native languages," moving beyond traditional text-centric AI architectures.
- Open Source Commitment: Meituan has released both the LongCat-Next model and its specialized discrete tokenizer to the public.
- Physical World Focus: The model is specifically designed to bridge the gap between digital intelligence and physical world perception and action.
- Developer Empowerment: The release is intended to provide the tools necessary for developers to create AI that can truly understand and interact with real-world environments.
In-Depth Analysis
The Shift to Native Multimodality
The release of LongCat-Next marks a significant evolution in how AI models process diverse data types. In the current landscape of artificial intelligence, many models operate on a "text-first" basis, where visual or auditory information is translated or adapted into a format the model can understand. Meituan’s approach with LongCat-Next challenges this paradigm by establishing vision and speech as "native languages" of the AI.
This "native" approach implies a unified architecture where different modalities are processed with the same level of priority and integration as text. By doing so, the model can potentially avoid the information loss that often occurs during the translation between different data formats. For Meituan, a company deeply embedded in physical services—ranging from food delivery to logistics—having an AI that inherently understands visual cues and spoken commands is essential for creating more intuitive and effective automated systems.
Bridging the Gap to the Physical World
One of the most ambitious aspects of the LongCat-Next project is its focus on the "physical world." Most large language models (LLMs) are confined to the digital realm, processing information that has already been digitized and abstracted. However, for AI to be useful in robotics, autonomous delivery, or real-time environmental interaction, it must possess the ability to perceive and act within a three-dimensional, dynamic space.
Meituan describes LongCat-Next as an exploration into "physical world AI." This suggests that the model is built to handle the complexities of real-world data, such as varying lighting conditions in vision or background noise in speech. The goal is to move from an AI that simply "knows" things to an AI that can "perceive" its surroundings and "act" upon them. This transition is critical for the next generation of AI applications that require a high degree of situational awareness and physical coordination.
The Significance of the Discrete Tokenizer
In addition to the model itself, Meituan has taken the significant step of open-sourcing the discrete tokenizer used by LongCat-Next. In the context of multimodal models, a tokenizer is a crucial component that breaks down raw data—whether it be text, images, or audio—into smaller units (tokens) that the model can process.
A discrete tokenizer for vision and speech is particularly valuable because it allows the model to handle continuous signals (like a video stream or a voice recording) as discrete units of information, similar to how words are handled in a sentence. By sharing this technology, Meituan is providing the developer community with the underlying "alphabet" and "grammar" needed to build their own multimodal systems. This move is likely to accelerate research and development in the field, as it lowers the barrier to entry for creating high-performance multimodal AI.
Industry Impact
The open-sourcing of LongCat-Next is poised to have a meaningful impact on the AI industry, particularly in the sectors of robotics and autonomous systems. By providing a framework where vision and speech are native, Meituan is setting a new standard for how multimodal models should be structured. This could lead to a shift away from modular, adapter-based systems toward more integrated, holistic AI architectures.
Furthermore, Meituan’s decision to open-source these tools reflects a growing trend among major tech companies to lead through ecosystem building. By allowing developers to build upon LongCat-Next, Meituan ensures that its architectural philosophy becomes a cornerstone of future physical-world AI developments. This not only enhances Meituan's reputation as a technical leader but also creates a feedback loop where community improvements can eventually benefit the original model's evolution.
Frequently Asked Questions
Question: What makes LongCat-Next different from other multimodal models?
LongCat-Next is distinguished by its "native" approach to multimodality. Instead of treating vision and speech as secondary inputs that need to be adapted for a text-based model, it treats them as primary, native languages. This allows for a more integrated and potentially more accurate understanding of real-world data.
Question: Why did Meituan open-source the discrete tokenizer?
The discrete tokenizer is a fundamental component that allows the model to process visual and auditory information. By open-sourcing it, Meituan enables other developers to understand and replicate the way LongCat-Next "sees" and "hears," fostering innovation in the creation of AI that interacts with the physical world.
Question: What is the primary goal of the LongCat-Next project?
The primary goal is to advance the development of AI that can perceive, understand, and act within the physical world. Meituan views this as a critical step toward creating AI systems that are truly useful in real-world, non-digital environments.