
Meituan Unveils LongCat-Next: Open-Sourcing a Native Multimodal Model for Physical World AI
Meituan's technical team has announced the release and open-sourcing of LongCat-Next, a native multimodal model designed to bridge the gap between artificial intelligence and the physical world. By treating vision and speech as "native languages," the model aims to fundamentally enhance how AI perceives, understands, and interacts with its environment. Alongside the core model, Meituan has open-sourced its discrete tokenizer, providing the global developer community with the essential infrastructure to build sophisticated AI systems capable of real-world action. This move represents a strategic milestone in Meituan's exploration of embodied AI, focusing on the seamless integration of multiple sensory inputs to create more intuitive and functional artificial intelligence that can operate beyond digital constraints.
Key Takeaways
- Native Multimodal Integration: LongCat-Next treats vision and speech as primary "native" languages rather than secondary inputs, allowing for more integrated processing.
- Open-Source Commitment: Meituan has open-sourced both the LongCat-Next model and its specialized discrete tokenizer to the developer community.
- Physical World Focus: The project is a core part of Meituan's exploration into AI that can perceive, understand, and act within the physical world.
- Developer Empowerment: By providing the discrete tokenizer, Meituan enables developers to build and customize AI that interacts with real-world environments.
In-Depth Analysis
The Shift Toward Native Multimodality
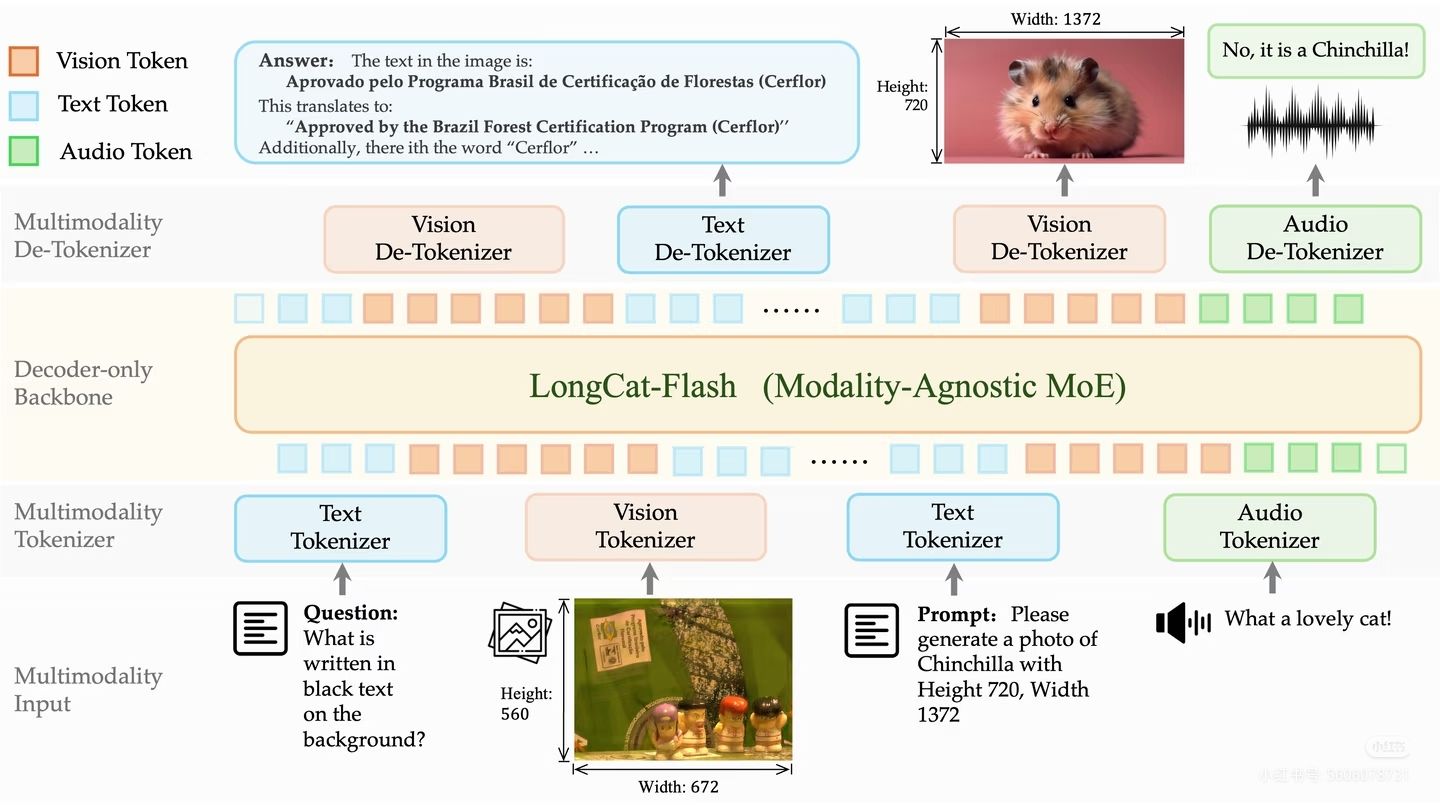
The release of LongCat-Next marks a significant evolution in how multimodal AI is conceptualized. Traditional AI models often treat non-text inputs—such as images or audio—as peripheral data that must be translated into a text-based understanding. Meituan’s approach with LongCat-Next challenges this paradigm by positioning vision and speech as the "native languages" of the AI. This suggests an architecture where sensory data is processed with the same level of primacy and fluidity as text, potentially reducing the loss of information that occurs during cross-modal translation. By focusing on native multimodality, the model is designed to achieve a more holistic understanding of complex environments, which is essential for tasks that require simultaneous visual and auditory processing.
Bridging AI and the Physical World
Meituan describes LongCat-Next as an exploration into "physical world AI." This terminology points toward the field of embodied AI, where the goal is to move artificial intelligence out of purely digital environments and into the physical realm. The ability to "perceive, understand, and act" implies that LongCat-Next is not merely a recognition engine but a foundational step toward AI that can make decisions based on physical context. The inclusion of a discrete tokenizer is particularly noteworthy. In AI architecture, a tokenizer is the component that breaks down data into manageable parts for the model to process. By open-sourcing a discrete tokenizer specifically designed for this multimodal framework, Meituan is providing the technical "vocabulary" necessary for other researchers to expand on how AI interprets physical signals like light and sound.
Open Source as a Catalyst for Innovation
By choosing to open-source the core research ideas, the model, and the tokenizer, Meituan is positioning itself as a foundational contributor to the next generation of AI development. The technical team expressed a clear intent: to allow developers to build upon their research to create AI that can "act upon the real world." This open-access strategy likely aims to accelerate the refinement of multimodal systems by leveraging the collective intelligence of the global developer community. It lowers the barrier to entry for smaller teams looking to experiment with complex vision-speech integration, potentially leading to a surge in applications ranging from robotics to advanced automated services that require a nuanced understanding of human-centric environments.
Industry Impact
The introduction of LongCat-Next has several implications for the broader AI industry. First, it reinforces the trend toward "native" multimodality, where the industry is moving away from modular add-ons toward unified architectures. This could set a new standard for how large-scale models are trained to handle diverse data types. Second, Meituan’s focus on the "physical world" highlights the growing importance of AI in logistics, robotics, and real-time environmental interaction—sectors where Meituan already holds significant operational expertise. By sharing these tools, they are effectively steering the industry's focus toward practical, embodied applications of AI. Finally, the release of the discrete tokenizer provides a critical technical building block that could standardize how vision and speech data are represented in future multimodal research, fostering greater interoperability between different AI systems.
Frequently Asked Questions
Question: What makes LongCat-Next different from traditional AI models?
LongCat-Next is a native multimodal model, meaning it is designed to treat vision and speech as its primary languages. Unlike models that primarily focus on text and treat other inputs as secondary, LongCat-Next integrates these modalities at a fundamental level to better perceive and understand the physical world.
Question: What specific components has Meituan open-sourced?
Meituan has open-sourced the core LongCat-Next model along with its discrete tokenizer. The tokenizer is a critical component that allows the model to break down and process multimodal data, and its release enables developers to build and iterate on the model's research framework.
Question: What is the primary goal of the LongCat-Next project?
The primary goal is to explore the path toward "physical world AI." Meituan aims to create and share a framework that allows AI to not only perceive and understand but also act within the real, physical environment, moving beyond purely digital or text-based interactions.