Meituan LongCat Open-Sources General 365: A Rigorous New Benchmark for AI Reasoning Performance
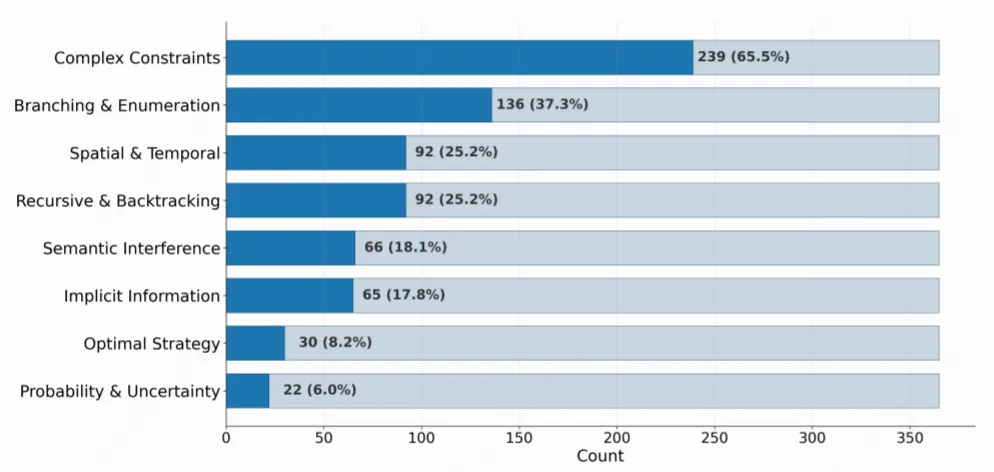
Meituan's LongCat team has officially released General 365, a new open-source benchmark designed to evaluate the reasoning capabilities of large language models (LLMs). The benchmark's debut has sent ripples through the AI community by revealing a significant performance gap in current technology. In a comprehensive test of 26 mainstream models, even the industry-leading Gemini 3 Pro managed an accuracy rate of only 62.8%. More strikingly, the vast majority of the models tested failed to reach the 60% threshold, which is typically considered a passing grade. This release by Meituan Technical Team establishes a new, more challenging standard for AI reasoning, suggesting that current models still face substantial hurdles in complex cognitive tasks.
Key Takeaways
- New Evaluation Standard: Meituan's LongCat team has launched General 365, an open-source benchmark specifically focused on AI reasoning.
- Gemini 3 Pro Performance: The model currently regarded as the strongest, Gemini 3 Pro, achieved an accuracy of 62.8% on the benchmark.
- Widespread Failure to Pass: Most of the 26 mainstream models tested failed to reach a 60% accuracy score, highlighting a significant deficiency in current reasoning capabilities.
- Industry Benchmark Shift: General 365 aims to set a more rigorous bar for evaluating how models handle complex reasoning compared to existing metrics.
In-Depth Analysis
The Launch of General 365 and the Reasoning Crisis
The release of General 365 by Meituan's LongCat team marks a pivotal moment in the evolution of AI benchmarking. For years, the industry has relied on a variety of metrics to measure the progress of large language models. However, as models become more sophisticated, many existing benchmarks have begun to suffer from saturation, where top-tier models achieve near-perfect scores, making it difficult to distinguish true reasoning ability from pattern matching or data memorization.
General 365 addresses this by introducing a framework that appears significantly more demanding than its predecessors. By open-sourcing this tool, Meituan is providing the global developer community with a "reality check." The initial data provided by the LongCat team suggests that the industry is currently facing a "reasoning crisis." When 26 of the most prominent models are put to the test and the majority cannot even secure a 60% accuracy rate, it indicates that the path toward true artificial general intelligence (AGI) is still fraught with fundamental challenges in logical processing and multi-step reasoning.
Analyzing the Performance of Gemini 3 Pro
The most telling data point from the General 365 release is the performance of Gemini 3 Pro. As a model widely recognized as one of the most capable in the world, its score of 62.8% serves as a benchmark for the current "ceiling" of AI reasoning. While 62.8% represents the top of the class in this specific evaluation, it is a modest figure in absolute terms.
This score suggests that even the most advanced architectures are struggling with the specific types of reasoning tasks curated in General 365. The fact that the "strongest" model is only slightly above the 60% mark implies that General 365 is designed to expose the edge cases and complex logical dependencies where current LLMs typically fail. It shifts the narrative from how well models can generate text to how accurately they can navigate complex problem-solving environments. For researchers, the 62.8% mark is not just a score; it is a target that defines the current frontier of the industry.
The 60% Threshold: A New Baseline for AI Maturity
Perhaps the most alarming revelation from the LongCat team's report is that the vast majority of mainstream models failed to reach the 60% accuracy threshold. In many academic and professional contexts, 60% is the baseline for a passing grade. The failure of most models to reach this level on General 365 suggests that many current AI solutions may be less reliable in high-stakes reasoning scenarios than previously thought.
This widespread underperformance highlights a potential over-optimization of models for conversational fluency at the expense of deep reasoning. As Meituan sets this new "ruler" for the industry, it forces a re-evaluation of what constitutes a "capable" model. If a model can write poetry but cannot pass a basic reasoning threshold on General 365, its utility in technical, legal, or scientific fields may be limited. The benchmark effectively separates models that are merely good at language from those that possess genuine analytical depth.
Industry Impact
The introduction of General 365 is likely to influence the AI industry in several key ways. First, it provides a transparent, open-source metric that discourages "benchmark gaming," as the difficulty level is high enough to reveal true performance variances. Second, it places pressure on major AI labs to improve the logical consistency of their models rather than just increasing parameter counts or training data volume.
Furthermore, Meituan’s decision to open-source the benchmark allows smaller research teams to align their development with industry-leading standards. By identifying that even the best models are currently hovering around the 60% mark, General 365 defines the next phase of the AI arms race: the quest for robust, reliable reasoning. This will likely lead to a shift in training methodologies, with a greater emphasis on synthetic reasoning data and reinforcement learning from human feedback (RLHF) focused on logical accuracy.
Frequently Asked Questions
Question: What is General 365?
General 365 is an open-source reasoning evaluation benchmark released by the Meituan LongCat team. It is designed to test the complex reasoning capabilities of mainstream large language models through a rigorous set of evaluations.
Question: How did the top AI models perform on this benchmark?
According to the report, Gemini 3 Pro, currently considered the strongest model, achieved an accuracy of 62.8%. However, the majority of the 26 mainstream models tested failed to reach an accuracy of 60%.
Question: Why is the 60% score significant in this context?
The 60% score is significant because it is often viewed as the minimum threshold for a "passing" grade. The fact that most models failed to reach this mark suggests that current AI technology still has a long way to go in mastering complex reasoning tasks.