
Google Research Explores Private Analytics via Zero-Trust Aggregation for Enhanced Data Privacy
Google Research has announced a new focus on private analytics through the implementation of zero-trust aggregation. This research, published on May 27, 2026, falls under the critical domain of Security, Privacy, and Abuse Prevention. The initiative aims to bridge the gap between data-driven insights and individual privacy by utilizing zero-trust frameworks in the aggregation process. By categorizing this work within its core security and privacy research track, Google signals a continued commitment to developing technologies that protect user data while allowing for meaningful analytical processing. The announcement highlights the evolving landscape of privacy-preserving computation and the importance of zero-trust architectures in modern data analytics.
Key Takeaways
- Focus on Private Analytics: Google Research is prioritizing the development of analytical methods that maintain high levels of data privacy.
- Zero-Trust Aggregation: The core methodology involves zero-trust frameworks to ensure that data aggregation does not compromise security.
- Strategic Categorization: The research is officially part of Google’s Security, Privacy, and Abuse Prevention research initiatives.
- Industry Leadership: This announcement underscores the ongoing efforts by major research entities to advance privacy-preserving technologies.
In-Depth Analysis
The Emergence of Private Analytics
The publication titled "Private analytics via zero-trust aggregation" by Google Research highlights a significant area of study within the tech industry. Private analytics refers to the ability to derive statistical insights from a dataset without exposing the individual data points of the contributors. By focusing on this field, the research addresses a fundamental challenge in the digital age: how to utilize large-scale data for improvement and analysis while strictly adhering to privacy standards. The inclusion of this topic in the Google Research Blog suggests that the development of these systems is a high priority for the organization's security and privacy teams.
Understanding Zero-Trust Aggregation
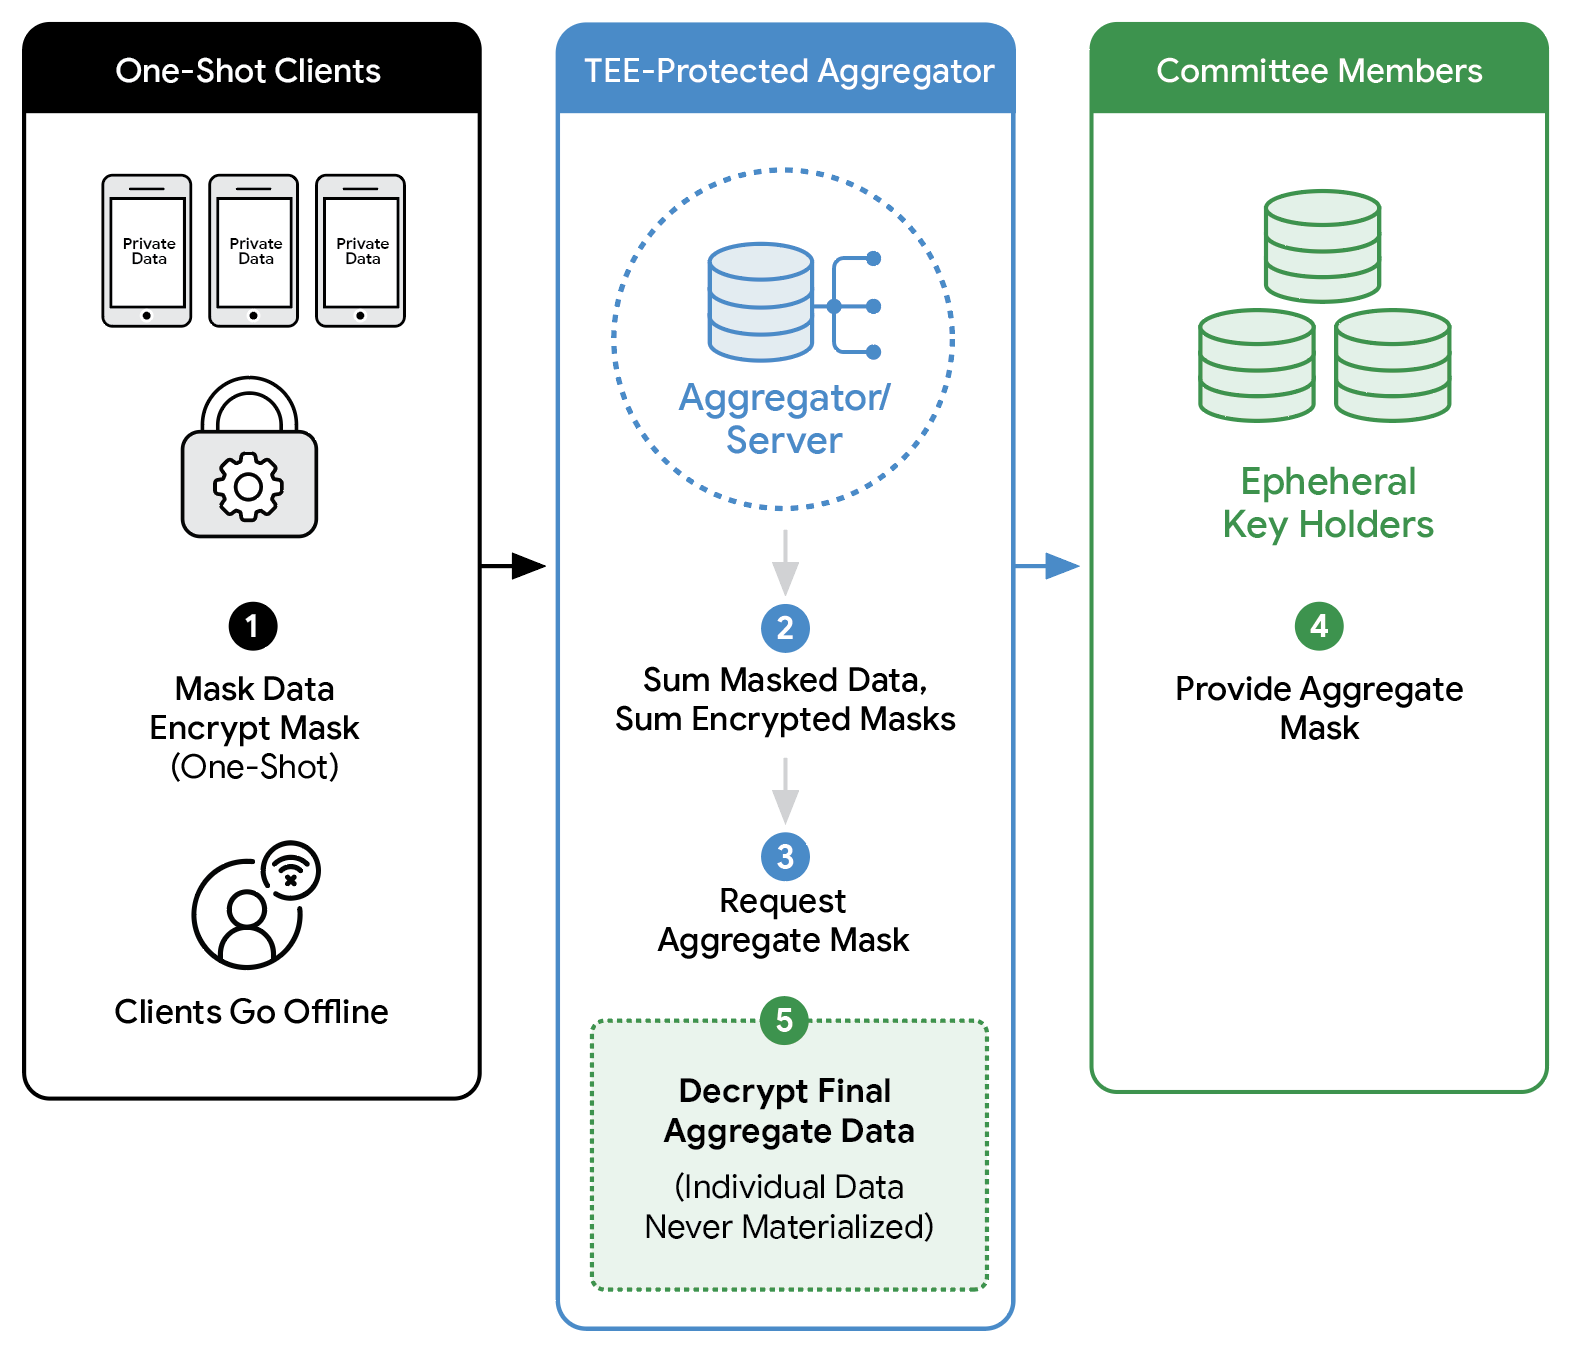
Central to this research is the concept of "zero-trust aggregation." In traditional data processing, aggregation often requires a central authority that is trusted to handle raw data before it is summarized. However, a zero-trust approach implies a framework where no single component or entity is implicitly trusted with the unencrypted or raw information. By applying zero-trust principles to the aggregation process, the research aims to create a more resilient and private system. This methodology ensures that even if parts of the system are compromised, the underlying individual data remains protected, as the aggregation process itself is designed to be secure and privacy-preserving from the ground up.
Security, Privacy, and Abuse Prevention Framework
The research is categorized under "Security, Privacy, and Abuse Prevention," which is one of the primary pillars of Google’s research ecosystem. This categorization indicates that the work on zero-trust aggregation is not merely a theoretical exercise but is intended to have practical applications in preventing data abuse and enhancing user security. By integrating private analytics into this framework, the research seeks to provide a robust defense against unauthorized data access while still enabling the beneficial outcomes of data analysis, such as identifying trends and improving service quality without individual tracking.
Industry Impact
The announcement of research into private analytics via zero-trust aggregation has several implications for the broader AI and data science industries. First, it sets a technical precedent for how large-scale service providers might handle user data in the future. As privacy regulations become more stringent globally, the shift toward zero-trust models in analytics provides a potential roadmap for compliance and ethical data usage. Furthermore, this research encourages the development of new standards in privacy-preserving computation, potentially leading to more widespread adoption of similar technologies across different sectors, including healthcare, finance, and telecommunications, where data sensitivity is paramount.
Frequently Asked Questions
Question: What is the main goal of the research titled "Private analytics via zero-trust aggregation"?
The main goal is to explore methods for performing data analytics that preserve individual privacy by utilizing a zero-trust aggregation framework, ensuring that no single entity needs to be fully trusted with raw data.
Question: Who published this research and what is its primary category?
This research was published by Google Research and is categorized under the fields of Security, Privacy, and Abuse Prevention.
Question: Why is zero-trust important in the context of data aggregation?
Zero-trust is important because it removes the reliance on a single trusted party to handle sensitive data. By assuming that no part of the system is inherently secure, zero-trust aggregation builds privacy directly into the data processing architecture.

