
Model Routing Is Simple. Until It Isn’t: Navigating the Hidden Complexities of AI Orchestration
The concept of model routing—directing user queries to the most appropriate large language model (LLM)—is often presented as a straightforward solution for optimizing AI performance and cost. However, a recent exploration by IBM Research, featured on the Hugging Face blog, suggests that the transition from conceptual simplicity to production-scale implementation is fraught with challenges. While basic routing logic may seem intuitive, the reality of managing multiple models involves navigating a complex web of trade-offs between latency, accuracy, and operational expenses. This analysis delves into the dichotomy of model routing, examining why initial implementations often fail to account for the dynamic variables of enterprise-grade AI environments and how the industry is shifting toward more sophisticated orchestration strategies to bridge this gap.
Key Takeaways
- The Simplicity Paradox: Model routing appears simple at the outset, often involving basic if-then logic or static rules to direct queries to specific models.
- Production Complexity: The "Until It Isn’t" phase begins when developers encounter real-world variables such as fluctuating costs, varying model latencies, and performance drift.
- Strategic Trade-offs: Effective routing requires a delicate balance between the high performance of large models and the cost-efficiency of smaller, specialized models.
- IBM Research Focus: The collaboration between IBM Research and Hugging Face highlights a growing industry need for robust, automated routing frameworks that can handle enterprise-scale demands.
In-Depth Analysis
The Illusion of Simplicity in Model Routing
At its core, model routing is the process of selecting the best model for a given task. In the early stages of development, this often looks like a simple classification problem. Developers might use a small, inexpensive model to handle basic administrative tasks or greetings, while reserving a larger, more capable model for complex reasoning or creative writing. This "simple" phase is characterized by static decision trees and predictable input types. The logic is clear: if the task is X, use Model A; if the task is Y, use Model B. This approach works well in controlled environments or prototypes where the volume of requests is low and the variety of prompts is limited.
However, the simplicity of this model selection process is often an illusion created by the lack of scale. In these early stages, the overhead of the routing mechanism itself is negligible, and the cost differences between models might not yet impact the bottom line. The focus is primarily on functional validation rather than operational optimization. As long as the query reaches a model that can provide a coherent answer, the routing is considered a success.
The Transition to "Until It Isn’t"
The complexity of model routing escalates dramatically when moved into a production environment. This is the point where the "Until It Isn’t" reality sets in. Several factors contribute to this shift. First, the diversity of user inputs in the wild is far greater than what can be captured in a static rule set. Semantic routing—using embeddings to determine the intent of a query—becomes necessary, but it introduces its own layer of latency and computational cost. The router itself becomes a model that must be managed, updated, and monitored.
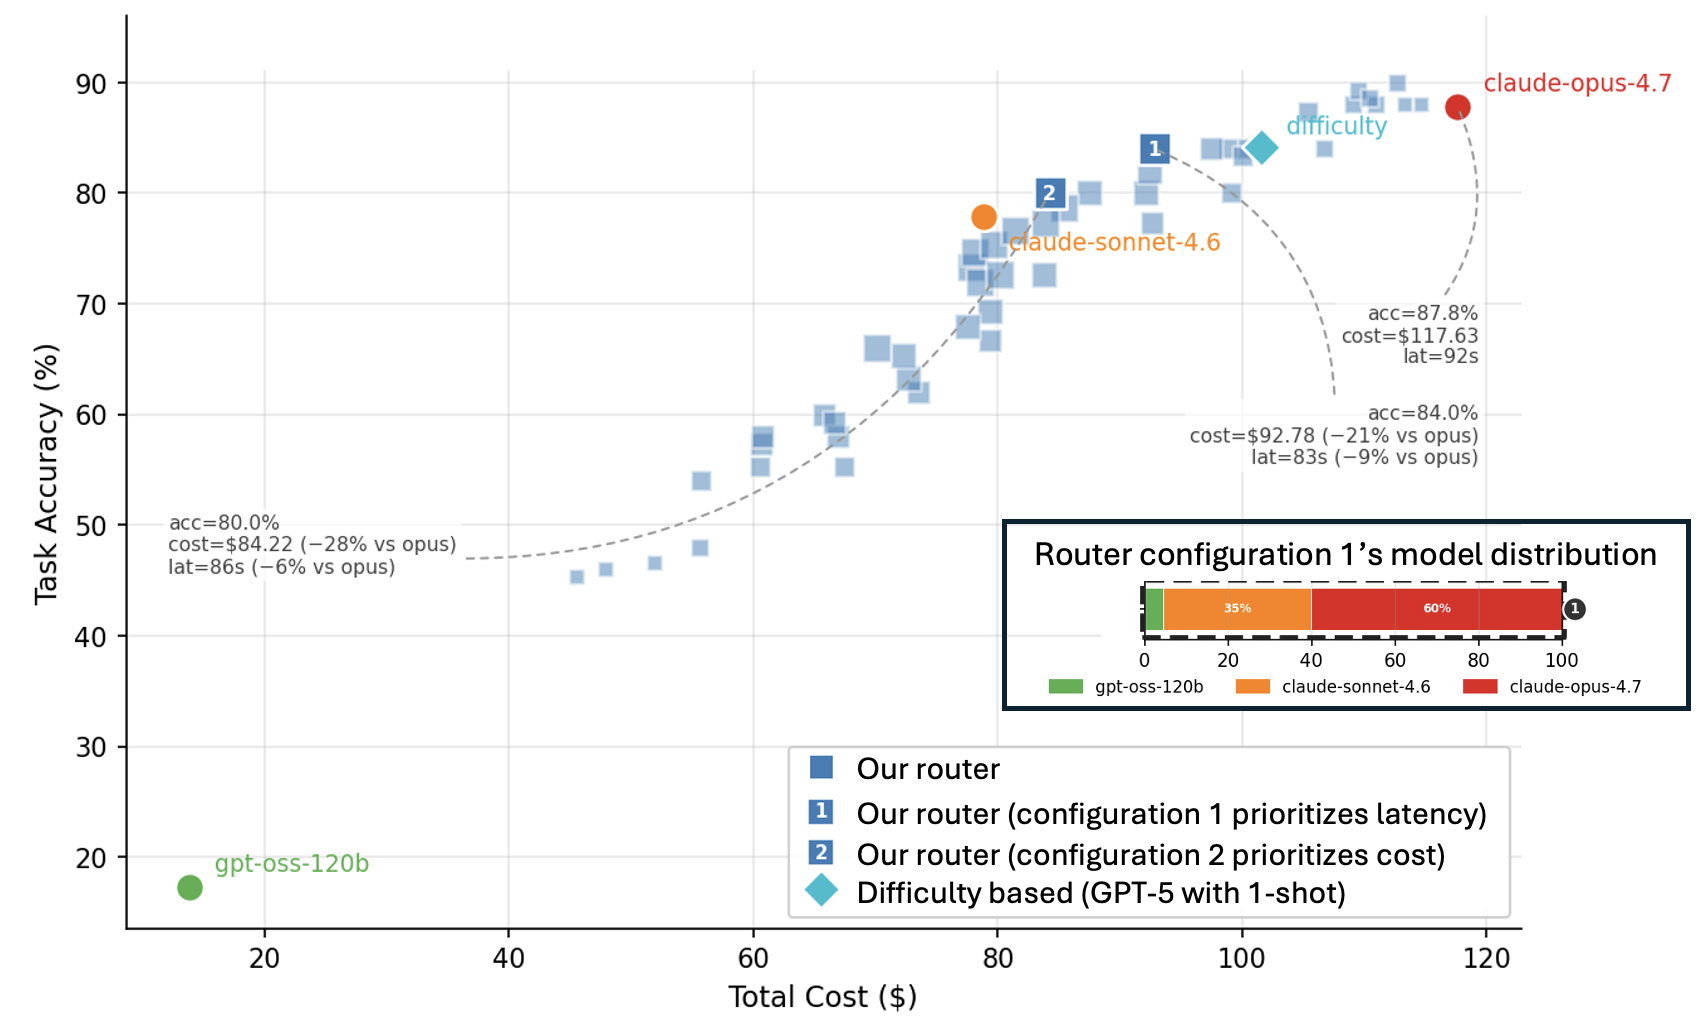
Second, the economic reality of running AI at scale introduces the need for cost-aware routing. Prices for API-based models can change, and the cost-to-performance ratio of open-source models versus proprietary ones is constantly shifting. A routing strategy that was optimal last month may be prohibitively expensive today. Furthermore, performance is not a static metric. Models can exhibit "drift," where their effectiveness on certain tasks changes over time due to updates or changes in the underlying data distribution. Managing these dynamic variables requires a level of orchestration that far exceeds simple conditional logic.
The Role of IBM Research and Hugging Face
The involvement of IBM Research in discussing these challenges on the Hugging Face blog signifies a shift in the industry's focus from model creation to model management. As the ecosystem moves toward a "multi-model" world, the infrastructure that connects these models becomes as important as the models themselves. IBM’s exploration into this space suggests that the future of AI deployment lies in sophisticated orchestration layers that can automatically navigate the Pareto frontier of cost and performance. By highlighting the hidden difficulties of routing, this research encourages developers to move beyond ad-hoc solutions and toward standardized, research-backed frameworks that can provide reliability and efficiency at scale.
Industry Impact
The realization that model routing is a complex engineering challenge has significant implications for the AI industry. We are likely to see a surge in the development of "Router-as-a-Service" products and open-source routing frameworks designed to abstract this complexity away from the end developer. For enterprises, this means a shift in investment from simply licensing the largest available model to building intelligent gateways that can leverage a diverse portfolio of models. This approach not only reduces costs but also increases system resilience; if one model provider experiences downtime, an intelligent router can automatically redirect traffic to an alternative without interrupting the user experience. Ultimately, the maturation of model routing will be a key driver in making large-scale AI deployments economically viable and operationally stable.
Frequently Asked Questions
Question: What is the primary goal of model routing?
The primary goal of model routing is to direct a specific user query to the most suitable AI model based on predefined criteria such as cost, speed, and the complexity of the task. It aims to maximize efficiency by ensuring that expensive, high-capacity models are only used when absolutely necessary, while simpler tasks are handled by smaller, faster models.
Question: Why does model routing become difficult at scale?
At scale, routing becomes difficult because the number of variables increases. Developers must account for real-time latency requirements, fluctuating API costs, model availability, and the need for high accuracy across a vast range of unpredictable user prompts. Additionally, the routing mechanism itself adds a layer of latency that must be minimized to maintain a good user experience.
Question: How does IBM Research contribute to this field?
IBM Research contributes by identifying the gap between theoretical routing and production reality. Their work, often shared through platforms like Hugging Face, focuses on developing more robust methods for model selection and orchestration, helping the industry move toward automated systems that can handle the complexities of enterprise AI environments.


