Managing AI Coding Through Agent Evaluation: A Case Study of Refactoring 310,000 Lines of Code
As AI-generated code accounts for over 90% of development output, the primary challenge in software engineering has shifted from production speed to the effective governance of AI capabilities. Meituan's technical team recently shared their experience in refactoring 310,000 lines of code using an "Agent evaluation" mindset. By implementing a structured framework—including technical debt assessment, rule establishment, standardized operating procedures (SOPs), and a Pre-PR mechanism—the team successfully transitioned high-cost refactoring projects into continuous, iterative daily tasks. This approach ensures that AI-driven development does not amplify system chaos but instead adheres to architectural standards, providing a blueprint for large-scale AI code management in the industry.
Key Takeaways
- Shift in Focus: In an environment where over 90% of code is AI-generated, the critical factor is no longer coding speed but the ability to constrain and govern AI output.
- Scale of Practice: The methodology was proven through the massive undertaking of refactoring 310,000 lines of code.
- Agent Evaluation Framework: The management strategy utilizes an "Agent evaluation" logic, treating AI as an autonomous agent that requires rigorous benchmarking and constraints.
- Core Mechanisms: Success relies on four pillars: technical debt sorting, rule construction, a Refactoring SOP, and a Pre-PR (Pull Request) mechanism.
- Continuous Iteration: These strategies transform refactoring from a high-cost, specialized project into a sustainable, daily development activity.
In-Depth Analysis
The Paradox of AI Productivity: Speed vs. Governance
The advent of AI in software engineering has reached a tipping point where the vast majority of code—exceeding 90% in some workflows—is produced by artificial intelligence. However, this surge in productivity introduces a significant risk: without a unified set of standards and constraints, AI has the potential to exponentially increase system complexity and technical debt. The core issue identified in the practice of refactoring 310,000 lines of code is that AI, if left unguided, tends to amplify existing chaos. Therefore, the priority for technical teams must shift from "who writes faster" to "how to effectively constrain AI capabilities" to ensure long-term system maintainability.
The Agent Evaluation Mindset in Code Management
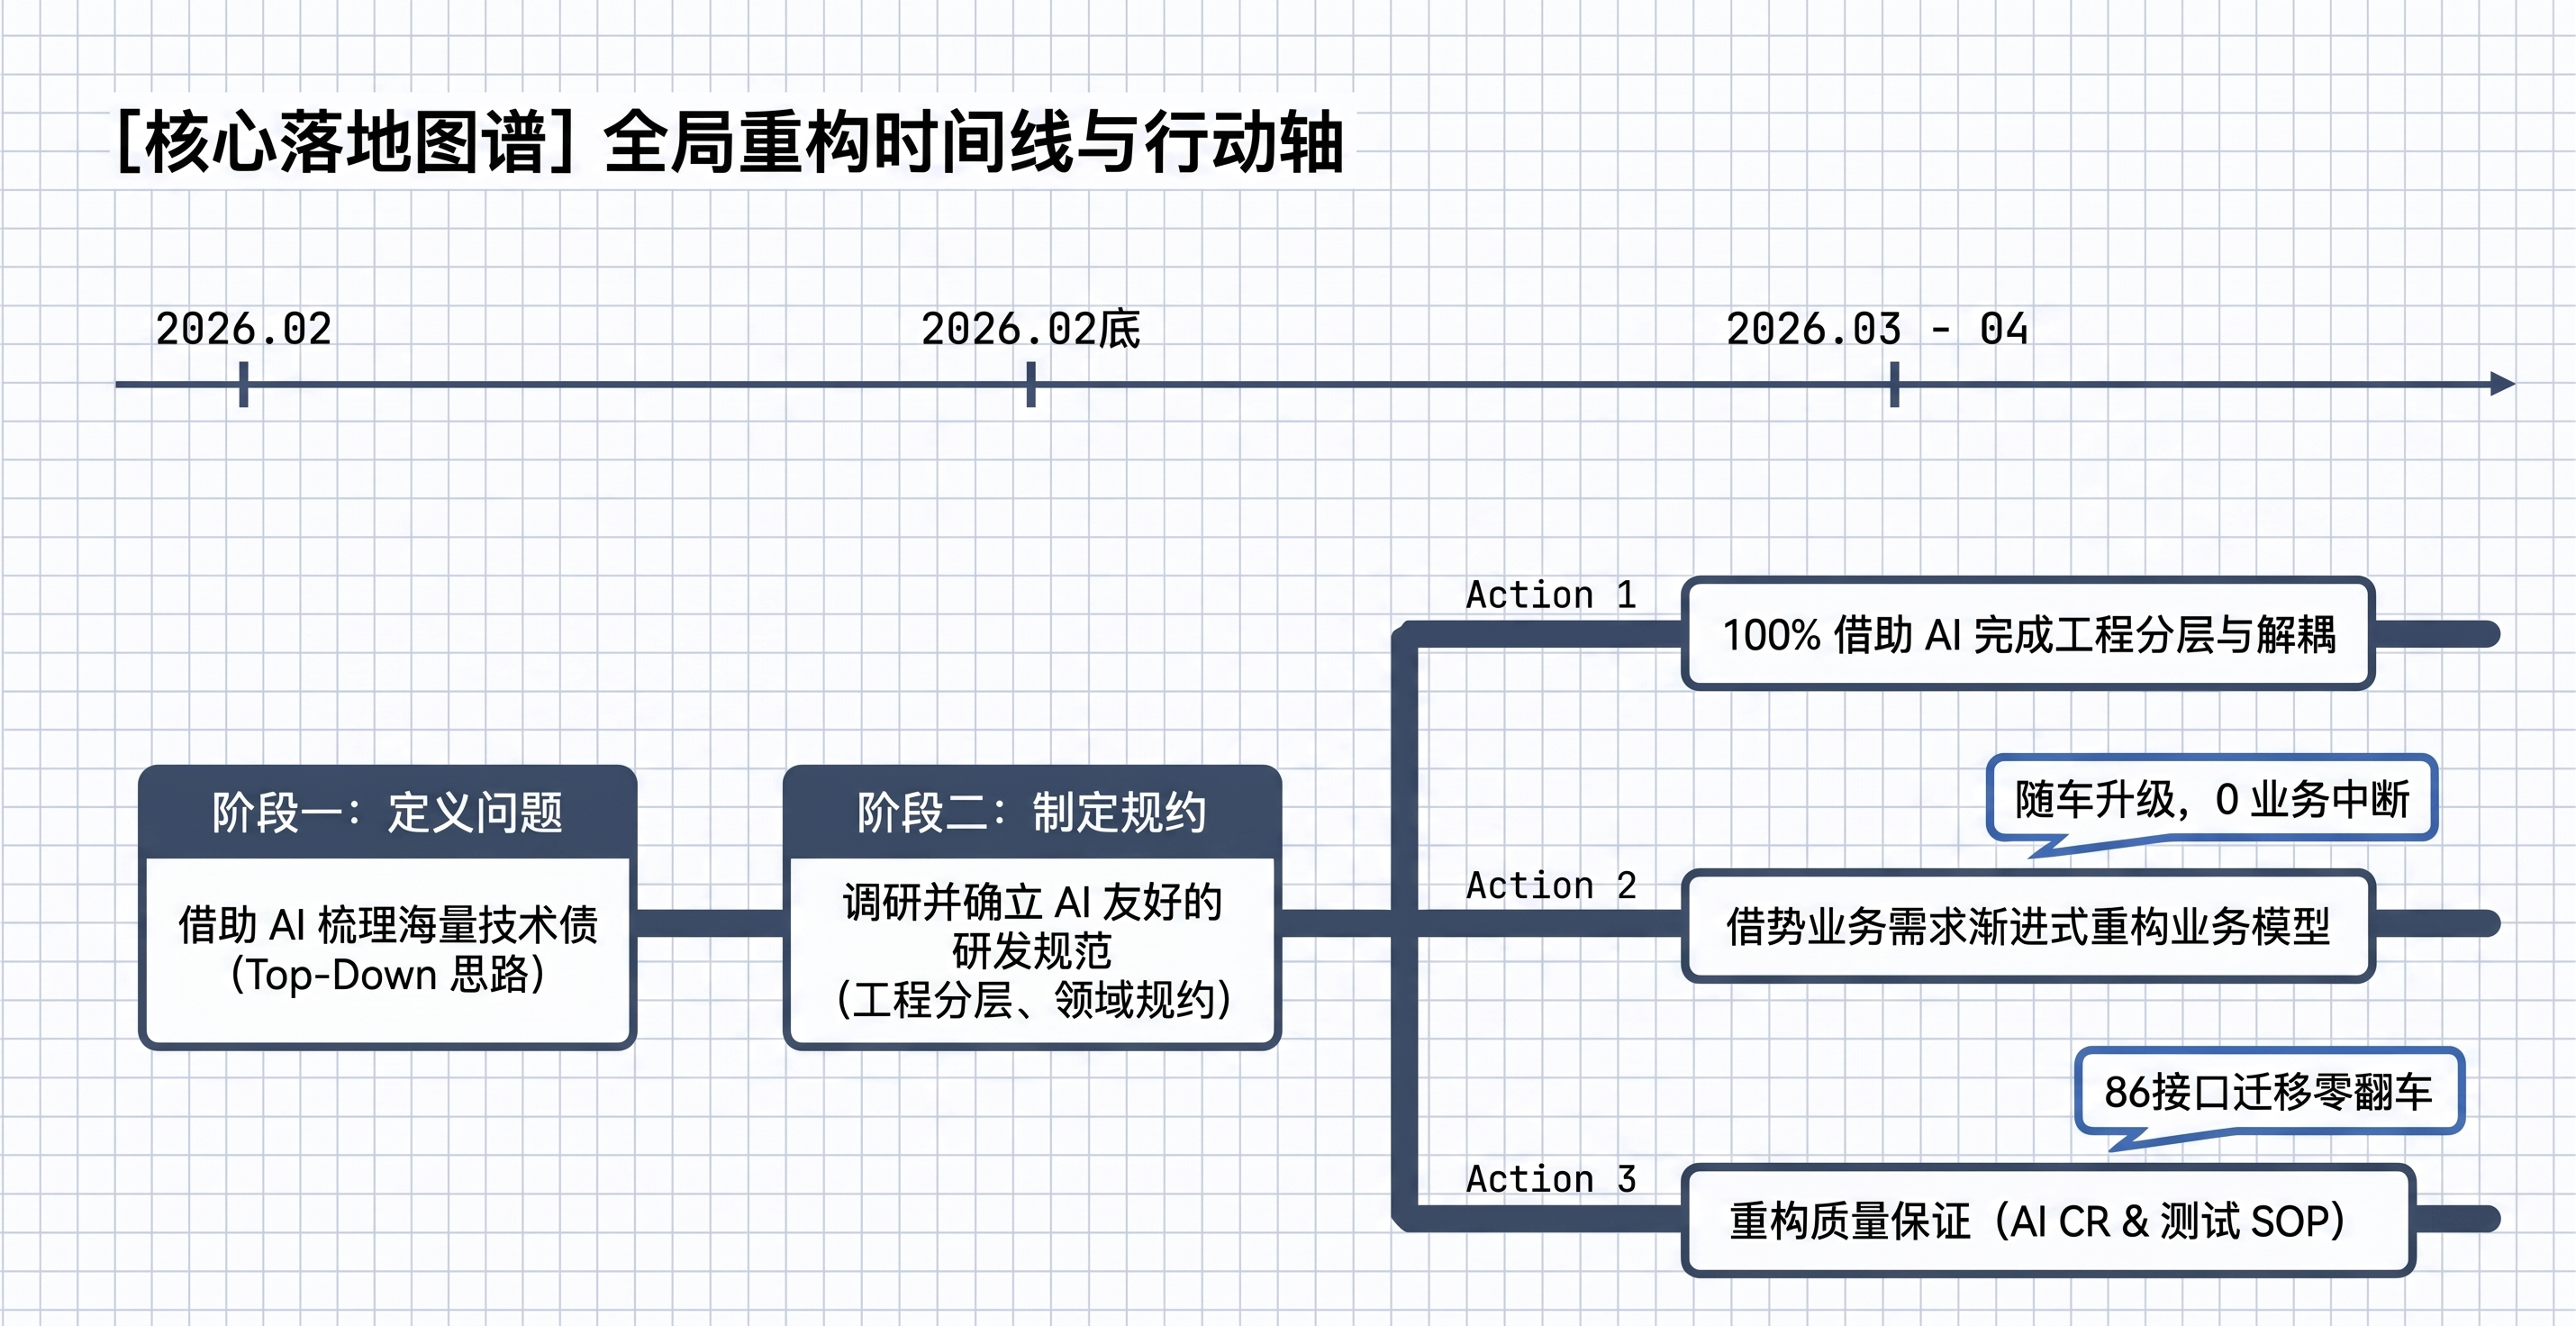
To manage large-scale AI coding, the Meituan technical team adopted an "Agent evaluation" approach. This perspective treats the AI coding tool not merely as a text generator but as an autonomous agent that must be evaluated and directed through specific technical frameworks. This management style is built upon several key components:
- Technical Debt Sorting: Before AI can effectively refactor code, there must be a clear understanding of existing technical debt. This involves identifying legacy issues and structural weaknesses that the AI needs to address.
- Building Rules: Establishing a robust set of rules is essential. These rules act as the guardrails for the AI, ensuring that the generated or refactored code aligns with the organization's architectural standards and coding conventions.
- Refactoring SOP (Standard Operating Procedure): By standardizing the refactoring process, the team ensures consistency across the 310,000 lines of code. An SOP provides a repeatable workflow that AI can follow, reducing the likelihood of idiosyncratic errors.
- Pre-PR Mechanism: The Pre-PR (Pull Request) mechanism serves as a critical gatekeeping stage. It allows for the automated or semi-automated validation of AI-generated code against established rules before it is even submitted for human review, significantly reducing the burden on senior developers.
Integrating Refactoring into the Daily Lifecycle
One of the most significant outcomes of this practice is the transformation of refactoring from a "high-cost special project" into a "continuous daily action." Traditionally, refactoring hundreds of thousands of lines of code would require a dedicated, resource-intensive effort. However, by leveraging AI within a structured evaluation framework, the process becomes part of the regular iteration cycle. This shift allows technical debt to be addressed incrementally, preventing the accumulation of "technical bankruptcy" and ensuring that the codebase evolves healthily alongside new feature development.
Industry Impact
The methodology shared by Meituan provides a critical reference point for the global software industry as it moves toward AI-native development. As AI becomes the primary author of code, the role of the human developer evolves into that of a "system architect" and "rule setter." The success of refactoring 310,000 lines of code demonstrates that with the right governance structures—specifically the Agent evaluation mindset—AI can be harnessed to improve code quality at a scale previously thought impossible. This sets a new standard for how large-scale enterprises can maintain agility and code health in the age of generative AI.
Frequently Asked Questions
Question: Why is speed no longer the most important metric in AI coding?
When AI can generate 90% of the code, the bottleneck is no longer how fast code is written, but how much effort is required to maintain, review, and fix that code. If the AI produces inconsistent or messy code at high speed, it creates more work for human developers in the long run. Governance and constraints become the new priorities to ensure system stability.
Question: What is the benefit of a Pre-PR mechanism in AI-driven refactoring?
A Pre-PR mechanism acts as an automated quality gate. It checks the AI's output against predefined rules and standards before the code reaches the formal review stage. This ensures that only high-quality, compliant code is presented to human reviewers, making the refactoring of 310,000 lines of code manageable and reducing the risk of introducing new bugs.
Question: How does the "Agent evaluation" approach differ from traditional code review?
Traditional code review is often reactive and human-centric. The "Agent evaluation" approach is proactive and systemic; it treats the AI as an agent that must be continuously measured against a set of benchmarks and rules. It focuses on building the environment and the constraints (the SOPs and Rules) that guide the AI's behavior, rather than just checking the final output.