
Thinking to Recall: How Reasoning Mechanisms Unlock Parametric Knowledge in Large Language Models
Google Research has introduced a compelling concept titled "Thinking to Recall," which explores the intricate relationship between reasoning processes and the retrieval of parametric knowledge within Large Language Models (LLMs). As the field of Generative AI evolves, the focus is shifting from simple pattern matching to understanding how internal reasoning can act as a key to unlock information stored within a model's weights. This analysis delves into the implications of using reasoning as a retrieval mechanism, the definition of parametric knowledge in the context of modern AI, and how this research from Google Research Blog signals a new direction for improving the accuracy and depth of generative systems.
Key Takeaways
- Reasoning as a Retrieval Tool: The core premise suggests that reasoning is not just for problem-solving but serves as a mechanism to access stored parametric knowledge.
- Parametric Knowledge Access: Large Language Models (LLMs) contain vast amounts of information within their parameters, and "thinking" or reasoning steps may be required to accurately recall this data.
- Generative AI Evolution: This research highlights a shift in Generative AI toward more sophisticated internal processing to improve the reliability of information retrieval.
- Google Research Leadership: The study originates from Google Research, emphasizing the industry's focus on the intersection of logic and memory in AI architectures.
In-Depth Analysis
The Concept of Parametric Knowledge in LLMs
To understand the significance of the "Thinking to Recall" research, one must first define the nature of parametric knowledge. In the realm of Large Language Models, parametric knowledge refers to the information that is internalized during the training process and stored within the model's weights (parameters). Unlike external knowledge retrieval, where a model queries a database or the internet, parametric knowledge is the "built-in" memory of the AI.
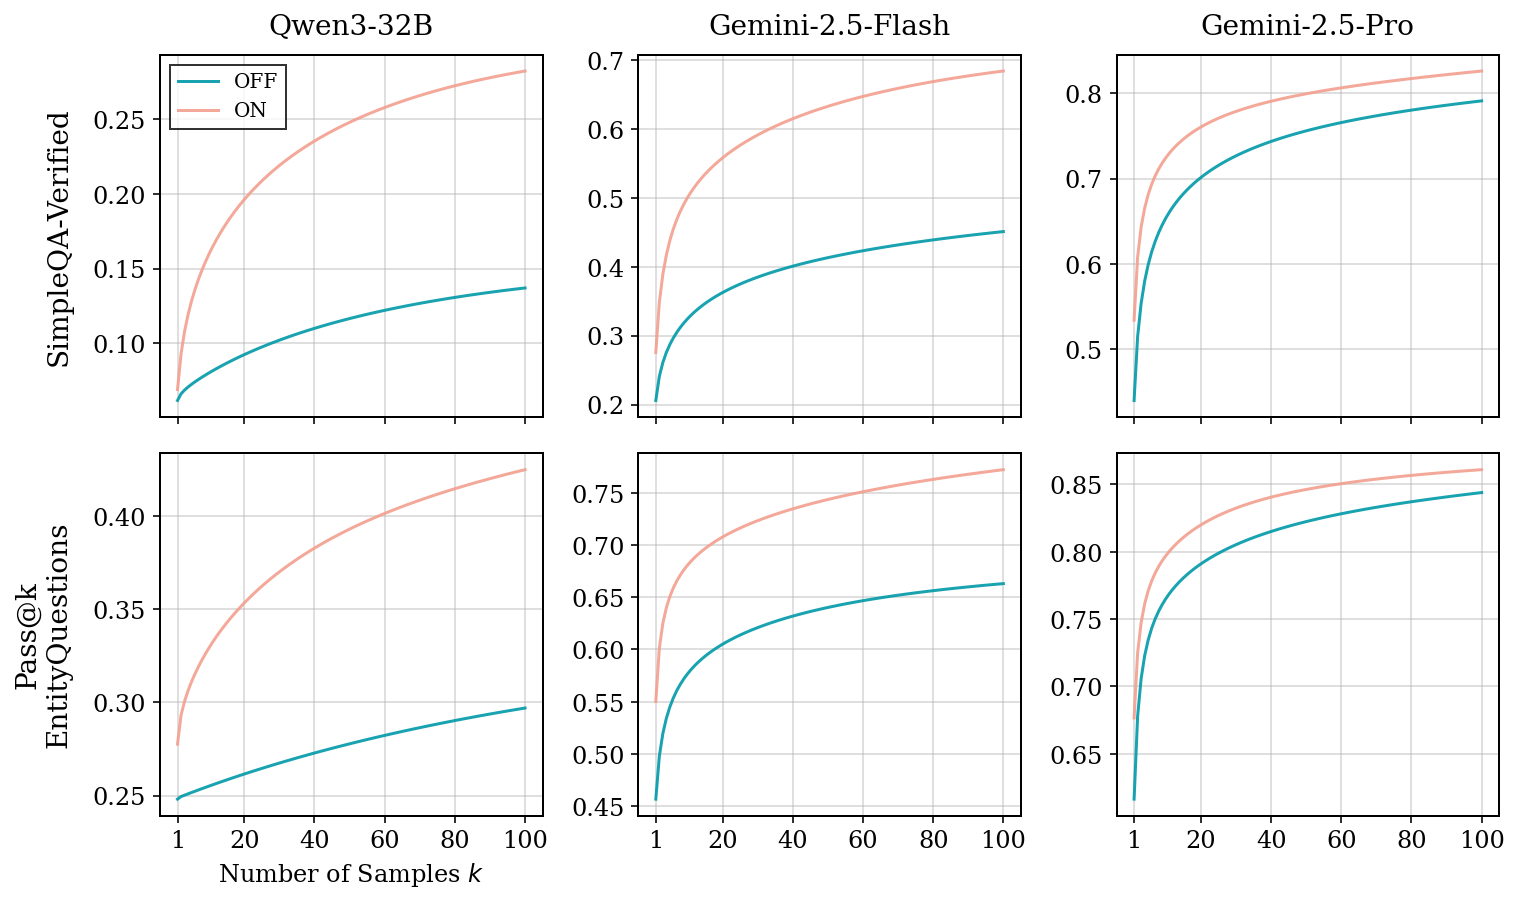
However, accessing this knowledge is not always straightforward. Models often suffer from "hallucinations" or failures to retrieve specific facts even when they have been exposed to them during training. The research from Google Research suggests that the bottleneck may not be the absence of knowledge, but the mechanism used to retrieve it. By framing the problem as one that requires "thinking" to solve, the research implies that the model's internal reasoning capabilities are the primary drivers for navigating its own vast parameter space.
"Thinking to Recall": A New Paradigm for Retrieval
The title of the Google Research post, "Thinking to recall: How reasoning unlocks parametric knowledge in LLMs," introduces a paradigm shift. Traditionally, reasoning (such as Chain-of-Thought processing) has been viewed as a method for tackling complex logical puzzles or mathematical problems. In contrast, this new perspective suggests that reasoning is equally vital for the fundamental task of memory recall.
When an LLM is asked a question, it doesn't just "look up" an answer in a static index. Instead, it generates a sequence of tokens based on probabilistic weights. The "Thinking to Recall" approach suggests that by engaging in intermediate reasoning steps, the model can better align its internal state to the specific region of its parametric memory where the relevant information resides. This implies that "thinking" acts as a sophisticated search query within the model's own neural network, allowing it to "unlock" facts that might otherwise remain obscured or incorrectly retrieved through direct prompting.
The Role of Reasoning in Generative AI
Generative AI has reached a plateau where simply increasing the number of parameters or the volume of training data yields diminishing returns in terms of factual accuracy. The industry is now looking toward architectural and procedural improvements. The insight that reasoning unlocks knowledge suggests that the future of LLMs lies in their ability to process information internally before producing an output.
This research underscores the importance of the "thinking" phase in the generative process. If reasoning is the key to unlocking knowledge, then models that are trained to be better reasoners will naturally become better at recalling facts. This creates a synergistic relationship between logic and memory. As Google Research explores these mechanisms, the focus remains on how to make Generative AI more robust, ensuring that the information it generates is not just a plausible sequence of words, but a precise reflection of its underlying parametric knowledge.
Industry Impact
The implications of this research for the AI industry are profound. First, it provides a theoretical foundation for why techniques like Chain-of-Thought (CoT) prompting are effective even for non-mathematical tasks; they are essentially helping the model "search" its own memory. Second, it suggests that future AI training might prioritize reasoning capabilities as a way to maximize the utility of existing model sizes, rather than simply building larger models.
For developers and enterprises, this shift means that the focus of prompt engineering and model fine-tuning may move toward optimizing the "thinking" paths of LLMs. If reasoning is the gateway to knowledge, then improving a model's logical flow is the most direct route to reducing hallucinations and increasing the factual density of AI-generated content. This research reinforces Google's position at the forefront of foundational AI research, providing the industry with a new lens through which to view the relationship between intelligence and memory.
Frequently Asked Questions
Question: What is the difference between parametric knowledge and external retrieval?
Parametric knowledge is the information stored directly within the AI model's weights during its training phase. It is "hard-wired" into the model. External retrieval, often referred to as Retrieval-Augmented Generation (RAG), involves the model looking up information from an outside source, such as a document folder or a website, at the time of the query.
Question: How does "thinking" help an AI recall information?
According to the research title and context, "thinking" refers to the reasoning processes or intermediate steps a model takes. These steps help the model navigate its internal parameters more effectively, allowing it to find and "unlock" specific information that might be difficult to access through a simple, direct response.
Question: Why is this research from Google Research important for Generative AI?
It identifies a critical link between a model's reasoning ability and its factual accuracy. By understanding how reasoning unlocks knowledge, researchers can develop more efficient models that provide more reliable and accurate information without necessarily needing to be larger in size.

