Meituan LongCat Team Unveils LongCat-AudioDiT to Redefine Zero-Shot TTS Voice Cloning via Waveform Latent Space
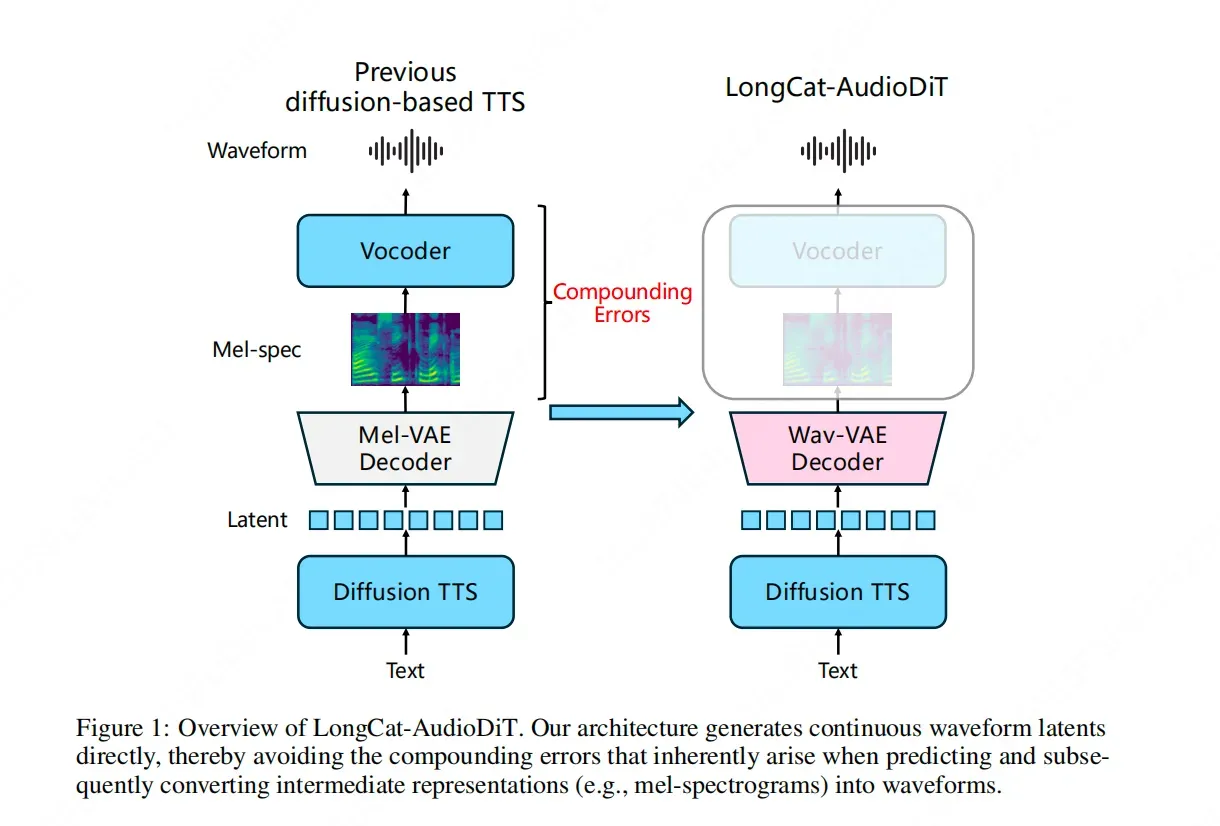
The Meituan LongCat team has announced the release of LongCat-AudioDiT, a pioneering model designed to advance the capabilities of zero-shot Text-to-Speech (TTS) voice cloning. By fundamentally restructuring the synthesis process, the model moves away from traditional intermediate representations like Mel-spectrograms, which are often identified as sources of cascade errors. Instead, LongCat-AudioDiT operates directly within the waveform latent space using a diffusion-based framework. This approach allows the AI to learn the inherent laws of sound directly from the data, bypassing intermediate stages that can degrade audio quality. The development aims to overcome existing technical bottlenecks in voice synthesis, providing a more direct and error-resistant method for high-fidelity voice cloning without the need for extensive per-speaker training.
Key Takeaways
- Innovation in Architecture: Meituan's LongCat team has officially launched LongCat-AudioDiT, a model specifically engineered to push the boundaries of zero-shot TTS voice cloning.
- Elimination of Intermediate Steps: The model completely abandons the use of Mel-spectrograms and other intermediate representations to prevent data conversion errors.
- Direct Waveform Processing: LongCat-AudioDiT utilizes a Diffusion Transformer (DiT) approach that operates directly within the waveform latent space.
- Error Mitigation: By skipping intermediate links, the model is designed to block the "cascade errors" typically associated with multi-stage data transformation in audio synthesis.
- Direct Learning: The AI is trained to learn the fundamental laws and patterns of sound directly, rather than through secondary visual or spectral representations.
In-Depth Analysis
Overcoming the Cascade Error Bottleneck
In the realm of Text-to-Speech (TTS) and voice cloning, the traditional pipeline often involves multiple stages of data conversion. A common approach involves converting text into an intermediate representation, such as a Mel-spectrogram, which is then transformed into a final audio waveform by a separate vocoder. The Meituan LongCat team identifies this multi-stage process as a significant technical bottleneck. According to the team's research, these intermediate steps introduce "cascade errors"—where inaccuracies in the first stage of conversion are amplified in subsequent stages, ultimately limiting the fidelity of the cloned voice.
LongCat-AudioDiT is designed to solve this problem by "thoroughly abandoning" these intermediate representations. By removing the need for Mel-spectrograms, the model seeks to block the root cause of these cumulative errors. This structural simplification ensures that the relationship between the input text and the output sound is more direct, preserving the nuances of the original voice that might otherwise be lost during the conversion to and from spectral data. This focus on architectural purity is a strategic move to break the current performance ceiling of zero-shot voice cloning technology.
Direct Learning in the Waveform Latent Space
The core technical breakthrough of LongCat-AudioDiT lies in its ability to allow AI to "directly learn the laws of sound itself." This is achieved by shifting the entire synthesis process into the waveform latent space. Unlike traditional models that might interpret sound through filtered or compressed representations, LongCat-AudioDiT uses a diffusion model (AudioDiT) to operate on the latent characteristics of the raw waveform.
By "skipping the intermediate links," the model can focus on the fundamental patterns that define a specific voice's timbre, pitch, and rhythm. The use of a Diffusion Transformer (DiT) in this latent space allows for a more sophisticated modeling of sound dynamics. This direct learning approach is intended to make the AI more efficient at capturing the essence of a voice in a zero-shot context, where the model must replicate a speaker's voice based on a very limited sample without prior specific training on that individual's data. The team's emphasis on learning the "laws of sound" suggests a move toward more generalized and robust audio AI that understands the structural properties of waveforms.
Industry Impact
The release of LongCat-AudioDiT by Meituan's LongCat team marks a significant milestone in the evolution of audio synthesis and AI-driven voice cloning. By demonstrating the viability of a model that bypasses Mel-spectrograms, the team provides a new technical direction for the industry, emphasizing the importance of reducing error propagation in complex AI pipelines.
For the broader AI industry, this development highlights the potential of diffusion models when applied directly to latent signal spaces. As zero-shot voice cloning becomes increasingly important for applications ranging from personalized digital assistants to content creation, the ability to produce high-fidelity, error-free speech from minimal samples is a critical competitive advantage. LongCat-AudioDiT’s approach of direct learning from sound laws could influence future research into other signal-processing tasks, encouraging a shift away from traditional feature engineering toward more integrated, end-to-end latent space architectures.
Frequently Asked Questions
Question: What makes LongCat-AudioDiT different from traditional TTS models?
LongCat-AudioDiT differs by completely removing intermediate representations like Mel-spectrograms. While traditional models convert text to a spectrogram and then to audio, LongCat-AudioDiT performs text-to-speech directly in the waveform latent space using a diffusion model, which minimizes data conversion errors.
Question: What are "cascade errors" in the context of voice cloning?
Cascade errors refer to the accumulation and amplification of inaccuracies that occur when data is converted through multiple stages. In TTS, errors introduced during the creation of a Mel-spectrogram can lead to further distortions when that spectrogram is converted into a final audio waveform. LongCat-AudioDiT avoids this by using a more direct synthesis path.
Question: How does the model achieve zero-shot voice cloning?
The model achieves zero-shot cloning by learning the fundamental laws of sound directly within the waveform latent space. This allows it to capture and replicate the unique characteristics of a new voice based on a brief sample, without requiring the model to be specifically fine-tuned or trained on that speaker's data.