
Meituan Open-Sources LongCat-Next: A Native Multimodal Model Designed for Physical World AI Interaction
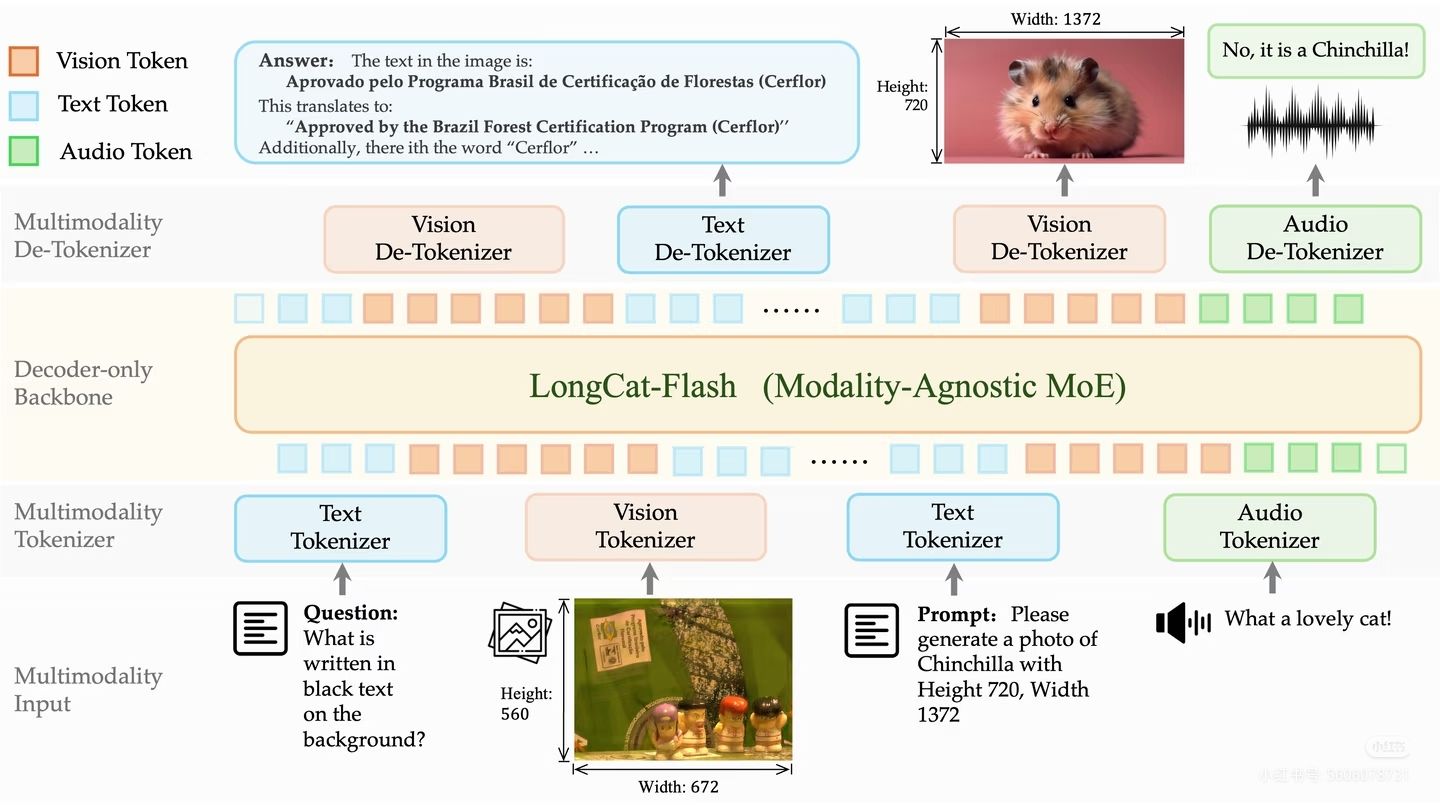
Meituan's technical team has officially announced the release and open-sourcing of LongCat-Next, a groundbreaking native multimodal model. By integrating vision and speech as "native languages" rather than peripheral inputs, LongCat-Next represents a significant step toward AI that can perceive and interact with the physical world. Alongside the model, Meituan has also open-sourced its discrete tokenizer, providing developers with the essential tools to build AI systems capable of understanding and acting within real-world environments. This strategic move aims to foster a collaborative ecosystem for the development of embodied AI and advanced multimodal understanding, bridging the gap between digital intelligence and physical reality.
Key Takeaways
- Open-Source Release: Meituan has made the LongCat-Next model and its core discrete tokenizer available to the global developer community.
- Native Multimodality: The model treats vision and speech as "native languages," moving beyond traditional additive multimodal approaches.
- Physical World Focus: The primary objective of LongCat-Next is to enable AI to perceive, understand, and act effectively within the physical world.
- Developer Empowerment: By sharing the research core and tokenizer, Meituan aims to accelerate the creation of AI applications that interact with real-world environments.
In-Depth Analysis
Redefining Multimodality: Vision and Speech as Native Languages
The release of LongCat-Next marks a pivotal shift in how AI models process diverse data types. Traditional multimodal systems often treat non-textual inputs, such as images and audio, as secondary data that must be translated or adapted for a text-centric core. However, Meituan’s approach with LongCat-Next emphasizes "native" multimodality. This suggests an architecture where vision and speech are integrated at a fundamental level, allowing the model to process sensory information with the same fluency as text. By treating these modalities as native languages, the model can potentially achieve a deeper, more nuanced understanding of the environment, which is critical for tasks requiring real-time perception and reaction in complex physical spaces.
Empowering the Ecosystem via Open-Source Tokenization
A critical component of the LongCat-Next release is the open-sourcing of its discrete tokenizer. In the context of multimodal AI, a tokenizer is responsible for converting continuous sensory data—like the pixels of a video or the waves of a voice—into discrete units that the model can process. By sharing this specific technology, Meituan is providing the community with the "building blocks" necessary to replicate and extend their research. This transparency allows developers to understand exactly how the model interprets the physical world, facilitating the creation of specialized applications that can see and hear with higher fidelity. The move reflects a broader industry trend toward open-source collaboration as a means to solve the complex challenges of embodied AI.
Bridging the Gap: From Digital Intelligence to Physical Action
The ultimate goal of the LongCat-Next project is to move AI beyond the confines of digital screens and into the physical world. Meituan describes this as an exploration toward "physical world AI." This involves more than just passive recognition; it requires the AI to perceive environmental context, understand the relationships between objects and sounds, and eventually determine how to act within that space. For a company like Meituan, which operates extensively in the physical realm through delivery and local services, this research is highly strategic. By open-sourcing these tools, they are inviting the global research community to help solve the fundamental problems of perception and interaction that will define the next generation of autonomous and assistive technologies.
Industry Impact
The introduction of LongCat-Next is poised to influence the AI industry in several key ways. First, it reinforces the importance of native multimodal architectures over modular ones, potentially setting a new standard for how sensory-heavy models are built. Second, by open-sourcing a discrete tokenizer specifically designed for vision and speech, Meituan is lowering the barrier to entry for smaller labs and independent developers to experiment with high-level multimodal AI. Finally, the focus on "physical world AI" aligns with the growing global interest in embodied AI and robotics, signaling that the next frontier of artificial intelligence will be defined by its ability to navigate and influence the tangible world around us.
Frequently Asked Questions
Question: What makes LongCat-Next different from other multimodal models?
LongCat-Next is designed with vision and speech as "native languages," meaning these modalities are integrated into the core of the model's architecture rather than being treated as external additions. This allows for a more seamless and integrated understanding of sensory data.
Question: Why did Meituan choose to open-source the discrete tokenizer?
Open-sourcing the tokenizer allows developers to see the fundamental way the model breaks down and interprets visual and auditory information. This transparency is essential for building, debugging, and improving AI systems that need to interact with the real world.
Question: What is the primary goal of the LongCat-Next project?
The project aims to advance the development of AI that can perceive, understand, and act within the physical world, moving beyond purely digital or text-based applications to solve real-world interaction challenges.