How to Stop Shipping Low-Quality RL Environments: Critical Insights on Model Degradation
In a recent analysis published by Latent Space, author Auriel Wright addresses a significant bottleneck in Reinforcement Learning (RL): the deployment of low-quality environments and broken harnesses. Wright argues that these faulty training setups are not merely neutral but are actively making AI models worse. Drawing from years of experience in 'eyeballing' trajectories—the step-by-step paths models take through an environment—the author highlights that many developers overlook fundamental flaws in their training infrastructure. The article serves as a call to action for AI practitioners to prioritize the integrity of their RL harnesses and environment designs to prevent performance regression and ensure more robust model development.
Key Takeaways
- Model Degradation: Broken harnesses and low-quality environments are identified as active contributors to declining model performance in Reinforcement Learning.
- The Importance of Trajectory Analysis: Manual inspection, or 'eyeballing,' of trajectories is presented as a vital practice for identifying hidden flaws in the training process.
- Infrastructure Integrity: The quality of the interface between the model and its environment (the harness) is as critical as the model architecture itself.
- Fixing the Feedback Loop: Identifying and correcting environmental errors is essential to stop shipping sub-optimal RL systems.
In-Depth Analysis
The Hidden Cost of Broken Harnesses
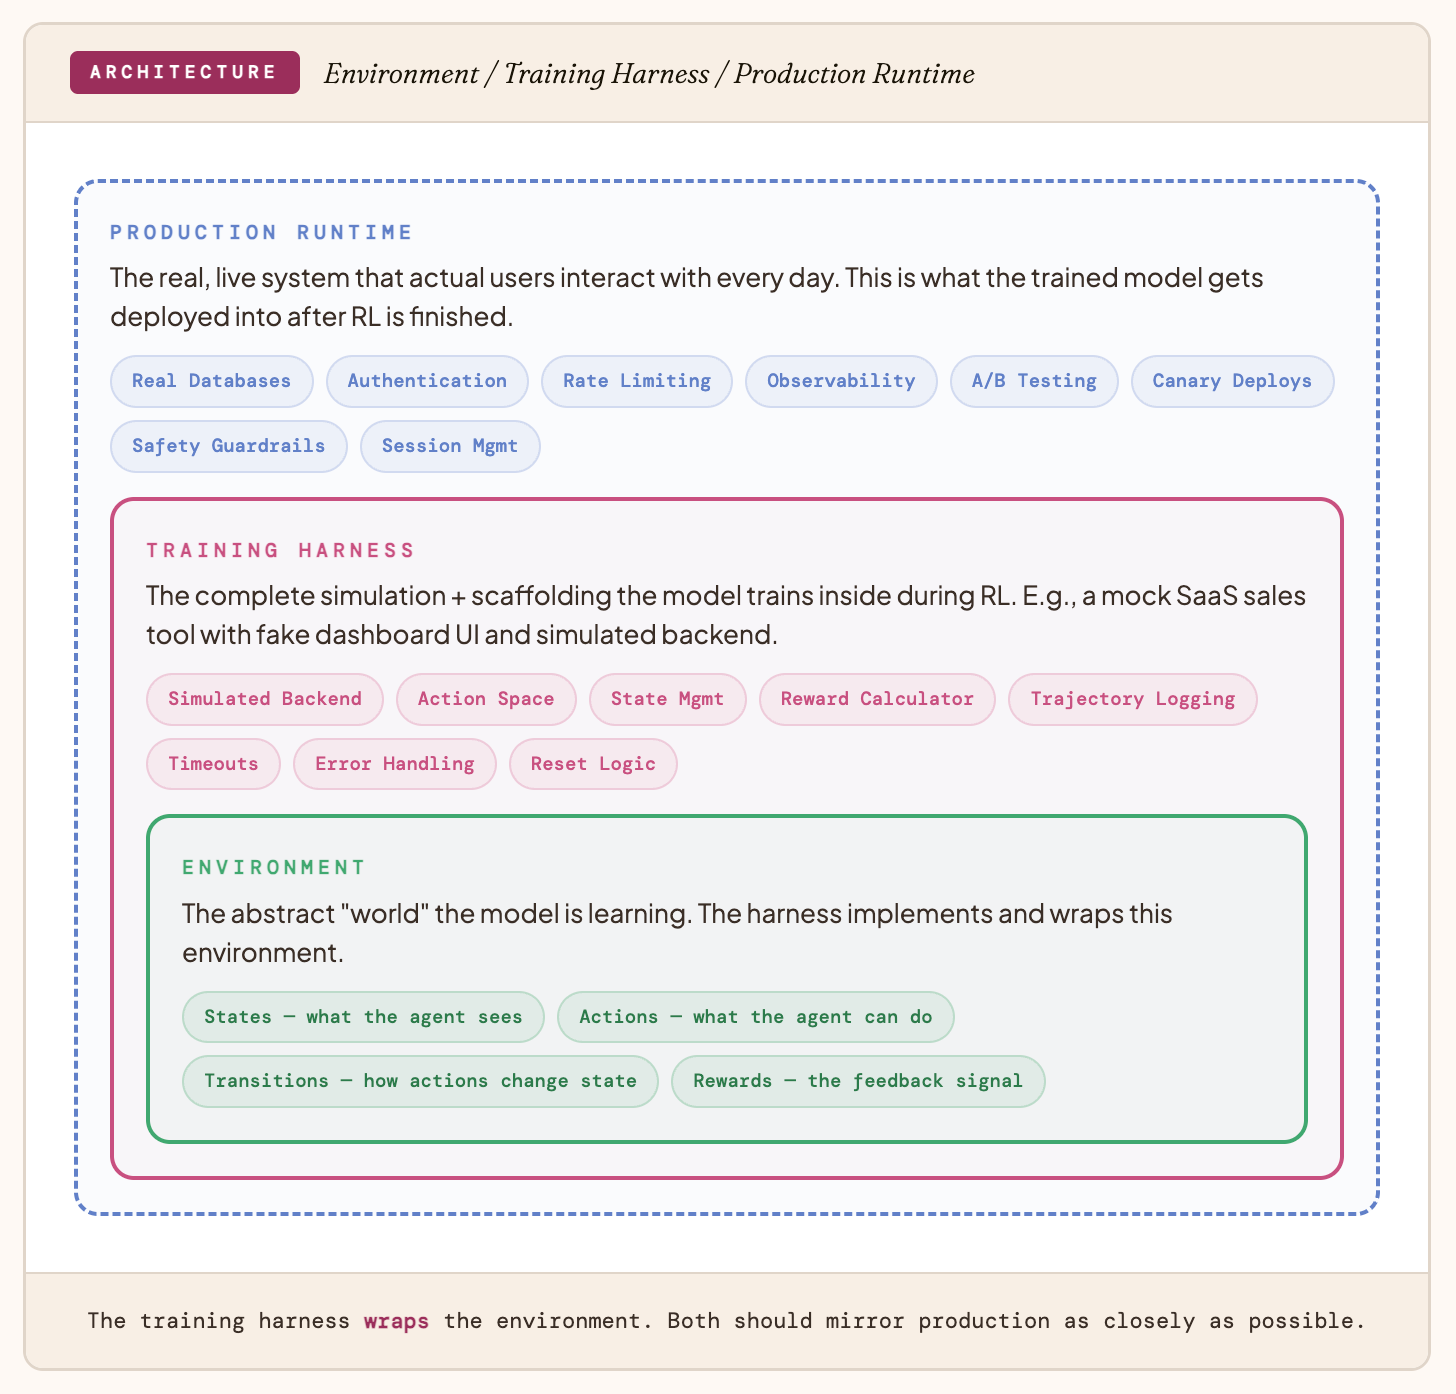
In the field of Reinforcement Learning (RL), the 'harness' refers to the infrastructure and interface that connects an AI agent to its training environment. According to Auriel Wright, a recurring issue in the industry is the shipping of 'broken' harnesses. These are not just minor technical bugs; they are fundamental misalignments in how the model interacts with its surroundings. When a harness is broken, the feedback loop—the system of rewards and penalties that guides the model's learning—becomes corrupted.
Wright emphasizes that a broken harness does not simply result in a model that fails to learn; it actively makes the model worse. This suggests that the model begins to optimize for the wrong objectives or learns to exploit flaws in the environment rather than developing the intended skills. This phenomenon of 'reward hacking' or learning from noise can lead to models that appear successful in a specific, flawed environment but fail catastrophically when applied to real-world scenarios or more robust benchmarks.
The Role of Trajectory Eyeballing in Quality Control
One of the most significant insights shared by Wright is the necessity of 'eyeballing trajectories.' In RL, a trajectory is the sequence of states, actions, and rewards that an agent experiences during an episode. While many developers rely on high-level metrics like mean reward or success rate, these numbers can often mask underlying issues.
By manually reviewing trajectories, developers can observe exactly how a model is behaving. Wright notes that years of observing these paths have revealed consistent patterns of failure that automated testing often misses. This manual oversight allows researchers to see where the environment might be providing misleading signals or where the harness might be clipping essential data. The transition from 'shipping' to 'fixing' requires a shift in focus from purely algorithmic improvements to a rigorous evaluation of the environment's physical and logical constraints.
Industry Impact
Elevating Standards for RL Environments
The insights provided by Auriel Wright signal a necessary shift in the AI industry toward higher standards for environment and harness design. As Reinforcement Learning moves from academic research into production-ready applications, the cost of low-quality environments increases. If the industry continues to ship broken harnesses, the progress of RL-based agents—ranging from robotics to automated decision-making systems—will be significantly hindered.
This analysis encourages a culture of 'environment debugging' that is just as rigorous as code debugging. By highlighting that the environment is a primary driver of model quality, Wright pushes the industry to treat RL infrastructure with the same level of scrutiny as the neural network architectures themselves. This could lead to more standardized testing protocols for RL environments and a greater emphasis on transparency in how trajectories are recorded and analyzed.
Frequently Asked Questions
Question: What does it mean for an RL harness to be 'broken'?
A broken harness refers to a flawed interface between the AI model and its training environment. This can include incorrect reward signals, misaligned state observations, or technical bugs that prevent the model from receiving accurate feedback on its actions. Such flaws lead to the model learning incorrect behaviors or degrading in performance.
Question: Why is 'eyeballing trajectories' considered a best practice?
'Eyeballing trajectories' involves the manual inspection of the step-by-step actions taken by an AI agent. This practice is crucial because high-level performance metrics can be deceptive. Manual review allows developers to identify specific moments where the environment fails or where the model is exploiting a flaw in the harness, ensuring the learning process is actually aligned with the intended goals.
Question: How do low-quality environments affect the final AI model?
Low-quality environments provide inaccurate or noisy data to the model during its training phase. Instead of improving, the model may learn to optimize for the flaws in the environment, leading to a decrease in generalizability and overall performance. In short, a bad environment actively trains the model to behave incorrectly.