Google Research Explores Generative AI for Photo Re-composition and Camera Angle Adjustments
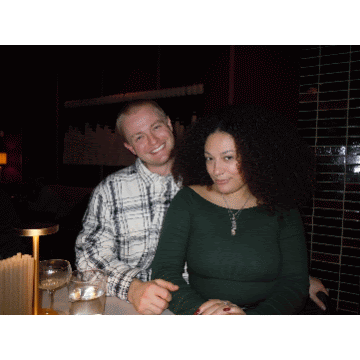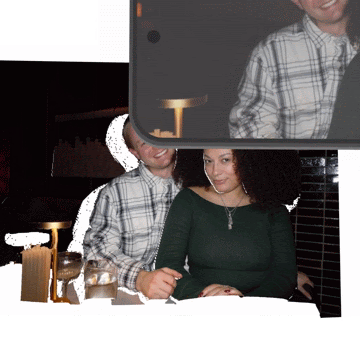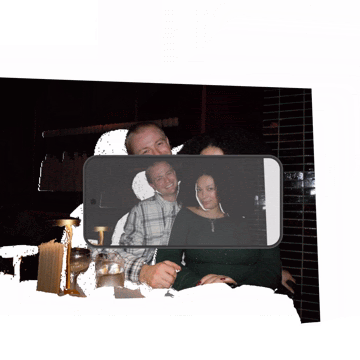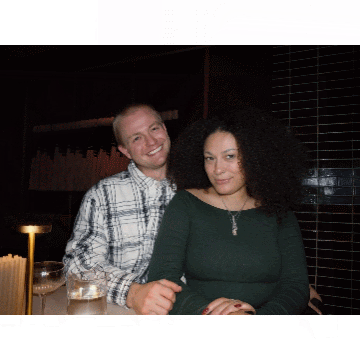
Google Research has introduced a new exploration into the capabilities of Generative AI, specifically focusing on the ability to re-compose and adjust the angles of existing photographs. The research highlights how generative models can be utilized to modify the perspective and framing of images after they have been captured. By leveraging advanced AI techniques, the technology aims to provide users with greater flexibility in photo editing, allowing for the seamless adjustment of camera angles that were previously fixed at the moment of capture. This development represents a significant step forward in the intersection of generative modeling and digital photography, offering a glimpse into the future of intelligent image manipulation tools.
Key Takeaways
- Google Research is leveraging Generative AI to enable the re-composition of captured photographs.
- The technology focuses on adjusting camera angles and perspectives post-capture.
- This innovation aims to provide more creative control over image framing using AI-driven synthesis.
In-Depth Analysis
Re-imagining the Camera Angle
The core of this research revolves around the concept of "re-composition." Traditionally, the angle and framing of a photograph are determined the moment the shutter is pressed. However, Google Research is utilizing Generative AI to break these physical constraints. By understanding the 3D geometry and semantic content of a 2D image, generative models can synthesize new views that mimic a change in the physical position of the camera. This allows for the correction of poorly framed shots or the exploration of new artistic perspectives from a single original photo.
The Role of Generative AI in Composition
Generative AI serves as the engine for these transformations. Unlike traditional cropping or warping, which can lose detail or distort the subject, generative models fill in the gaps and maintain visual consistency when the perspective is shifted. This process involves sophisticated algorithms that can predict what parts of a scene would look like from a slightly different angle, ensuring that textures, lighting, and shapes remain realistic throughout the re-composition process.
Industry Impact
The introduction of AI-driven re-composition has profound implications for the digital imaging industry. For professional photographers and casual users alike, it reduces the pressure of achieving the "perfect shot" in the moment, as framing can be refined later. Furthermore, this technology sets a new standard for photo editing software, moving beyond simple filters toward structural image manipulation. As Generative AI becomes more integrated into consumer devices, we can expect a shift in how visual media is produced, edited, and consumed, making high-level cinematography and photography techniques accessible to everyone.
Frequently Asked Questions
Question: What is photo re-composition in the context of Generative AI?
Photo re-composition refers to using AI models to change the framing, perspective, or camera angle of an image after it has been taken, effectively allowing the user to "re-shoot" the scene digitally.
Question: How does this differ from standard photo editing?
Standard editing typically involves adjusting colors or cropping existing pixels. Generative re-composition actually synthesizes new visual information to account for changes in perspective, maintaining the integrity of the scene from a new angle.